 EN
 Deutsch
 Español
 Français
 Italiano
 Português
 Nederlands
 Polski
 Bahasa Indonesia
 Русский
 Українська
 العربية
 עברית
 हिन्दी
 日本語
 한국어
2026-08-09 · Season 2
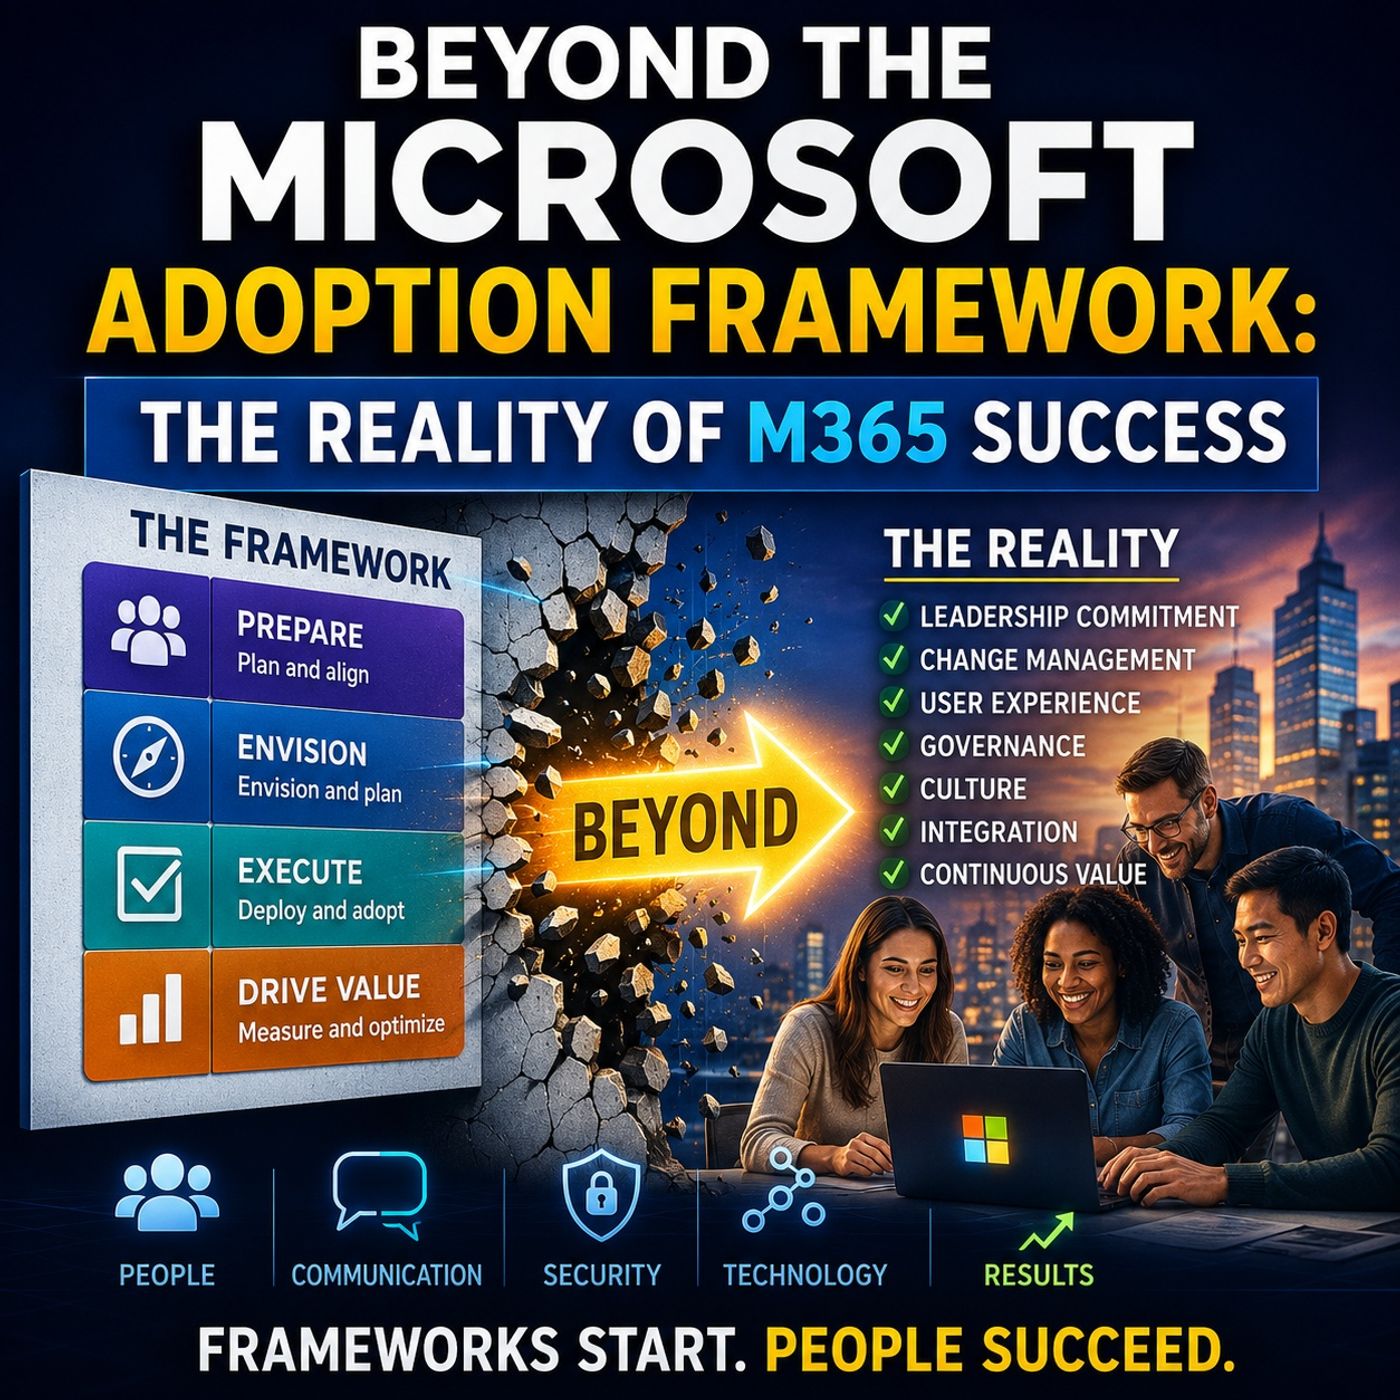
Beyond the Microsoft Adoption Framework- The Reality of M365 Success
Show notes
Microsoft 365 transformation is often discussed as though success can be engineered by following the right framework closely enough. Define the strategy, prepare the environment, migrate workloads, establish governance, train users, measure adoption, and continue optimizing. On paper, the process appears logical and comprehensive. In practice, organizations can follow almost every recommended step, successfully deploy Microsoft Teams, SharePoint, OneDrive, Microsoft 365 Copilot, and the wider Microsoft cloud platform, and still discover that very little about the way the organization actually works has changed. That is the central problem explored in this episode. Microsoft 365 adoption rarely fails because the technology itself is incapable of supporting the organization. The more persistent failure occurs because deployment is treated as transformation, activity is interpreted as adoption, and a framework is expected to compensate for an operating model that was never redesigned. The result can be a technically successful Microsoft 365 implementation sitting on top of exactly the same organizational behaviors, unclear responsibilities, information silos, governance gaps, and inefficient processes that existed before the migration. The Microsoft Cloud Adoption Framework and Microsoft 365 adoption guidance remain useful, but they cannot answer the most important organizational questions on their own. They cannot decide who owns a Team after the project that created it has finished. They cannot determine where a business decision should be documented instead of remaining inside someone's inbox. They cannot force employees to stop recreating shared-drive structures inside SharePoint. They cannot determine which Copilot use cases matter to finance, legal, sales, operations, or HR. Most importantly, they cannot change the mental model employees and leaders have developed over years of working in a particular way. THE FRAMEWORK IS A MAP, NOT THE TRANSFORMATION Microsoft's adoption and cloud frameworks contain substantial experience accumulated across many implementations, but their usefulness depends on how organizations interpret them. A framework can provide direction, identify common failure points, describe architectural patterns, and force teams to consider questions they might otherwise overlook. What it cannot provide is a universal operating model suitable for every organization regardless of size, maturity, industry, risk profile, existing technology, and organizational culture. The source uses the analogy of replacing a policeman directing traffic at an intersection with a roundabout. The traditional environment is slower and more centralized because movement is controlled directly. The cloud introduces something closer to the roundabout: greater autonomy and speed combined with predefined lanes and guardrails. The infrastructure may be objectively better, but the infrastructure itself does not teach anyone how to behave inside it. Drivers still need to understand when to yield, how to enter, and how to leave safely. Microsoft 365 creates the same challenge. Teams, SharePoint, OneDrive, Copilot, identity services, security controls, retention capabilities, and governance tooling create an environment in which organizations can operate very differently from the traditional world of email, file servers, departmental applications, and manually controlled access. However, providing the environment does not automatically create the behavior required to use it effectively. The framework establishes the roads and guardrails, but the organization still needs to establish the traffic rules. WHY TECHNICALLY SUCCESSFUL DEPLOYMENTS CAN STILL FAIL A Microsoft 365 project can reach every conventional technical milestone and still fail as a transformation initiative. Mailboxes can be migrated successfully, identities synchronized, Teams enabled, SharePoint sites provisioned, policies configured, and Copilot licenses assigned without changing how employees think about collaboration or information. This happens partly because different groups define completion differently. IT naturally concentrates on technical readiness and may consider the project substantially complete once the environment is stable and users can access the required services. Employees experience the same event as a change in the tools available to perform their jobs. Leadership may interpret completion through budget, timeline, and project-status reporting. All three perspectives can be reasonable while still failing to describe whether adoption actually occurred. The critical gap exists between access to technology and changed behavior. License activation proves that an employee is technically capable of using a service. It does not prove that the employee understands why the service matters, which existing behavior it should replace, or how it should fit into a real business process. That distinction becomes increasingly important as Microsoft 365 expands beyond productivity applications into AI. Assigning a Copilot license can happen in minutes. Changing the way an employee prepares a report, analyzes information, documents a decision, evaluates AI-generated content, or collaborates with colleagues can take months. WHY MORE MICROSOFT 365 ACTIVITY DOES NOT NECESSARILY MEAN MORE ADOPTION Traditional adoption reporting tends to favor metrics that are easy for the platform to observe. Monthly active users, Teams messages, meetings, SharePoint edits, OneDrive activity, and Copilot prompts all provide useful information about what is happening inside the tenant, but none of these measurements independently establishes that the organization has improved. A rise in Teams messages could indicate that employees have successfully moved collaborative conversations into transparent team spaces. The same increase could indicate that communication has become fragmented across channels and employees are sending more messages simply to locate information. Increased SharePoint activity could represent successful co-authoring, or it could represent employees repeatedly moving and duplicating documents because nobody understands the information architecture. The source makes this distinction particularly important by arguing that confusion itself generates activity. A dashboard can therefore move upward while the quality of collaboration moves downward. Activity tells administrators that something is happening; it does not explain whether the behavior producing that activity represents the desired transformation. This is why Microsoft 365 success cannot be reduced to an adoption percentage derived exclusively from platform telemetry. Usage is evidence, but it requires context before it becomes evidence of success. STRATEGY HAS TO EXIST BEFORE TECHNOLOGY BECOMES THE STRATEGY One of the earliest problems appears when organizations begin with technology rather than with the business reason for change. A Microsoft 365 license agreement already exists, servers are approaching end of support, a merger creates pressure to consolidate environments, or executives decide that Copilot needs to be introduced quickly. Because the technology and deadline are already visible, the organization begins implementing before clearly defining what should become different as a result. The source distinguishes migration triggers from innovation triggers. Migration can be driven by cost, complexity, aging infrastructure, or operational risk, while innovation is driven by opportunities to create capabilities, enter new markets, increase scale, automate work, or introduce technologies such as AI. The distinction matters because the architecture, budget, timeline, and measurement model should change according to the objective. An organization trying to escape unsupported infrastructure may reasonably prioritize speed and risk reduction. An organization trying to redesign knowledge work around Copilot requires a very different program involving experimentation, process analysis, training, governance, and measurement. When these motivations are not explicit, organizations can become extremely efficient at implementing the wrong thing. A DEADLINE CAN CREATE MOVEMENT WITHOUT CREATING DIRECTION Urgency frequently disguises itself as strategy. Hardware reaches end of life, contracts expire, security requirements change, or executives commit publicly to an AI initiative, and suddenly the organization has a transformation program. The project has a deadline, a budget, and a list of deliverables, but it may still lack a destination. The source describes this effectively as a deadline wearing the clothes of strategy: the organization knows why it must leave the current state but has not clearly defined what the future state is supposed to achieve. This distinction becomes critical when costs begin increasing. Leadership can defend an investment when the expected business outcome is understood. It becomes considerably more difficult to defend additional spending when nobody can clearly explain whether the objective was cost reduction, improved collaboration, reduced risk, faster decision-making, AI-enabled productivity, or simply completing a migration before something stopped being supported. Strategy therefore needs to provide more than momentum. It needs to establish the criteria by which the organization will later decide whether the transformation was worthwhile. Become a supporter of this podcast: https://www.spreaker.com/podcast/m365-fm-microsoft-365-azure-cloud-power-platform-ai--6704921/support.
Apple Podcasts · Spotify · YouTube · Deezer
Host: Mirko Peters
Related articles
- Why Your M365 Framework is a Map, Not a Transformation
- Why Your M365 Framework Is a Map, Not the Destination
Transcript
Read the full transcript
Before we look at why your adoption framework is failing, hit subscribe on M365FM, we track this stuff every day. Most companies think their co-pilot rollout failed because of change management. It didn't. It failed because of the model underneath it. Here is the tension nobody wants to name out loud. The cloud adoption framework and the M365 adoption guide both promise to eliminate common failure points. That is the actual language they use. And yet, most organizations still hit the exact same wall, the same governance mess, the same stall team's rollout, the same co-pilot licenses sitting unused by the end of this episode, you are going to understand the difference between deploying M365 and actually integrating it into how your business works. You will see why 73% of deployments make the exact same governance mistake. Over and over, regardless of company size or industry, here are the stakes. If you do not fix the model underneath your rollout, co-pilot cannot fix it for you. It just runs the same dysfunction faster. The promise. Nobody reads past the headline. Go read the Microsoft documentation right now and you will find this line. "Proven guidance to be successful in Azure." It sounds solid, it feels battle tested, thousands of deployments, best practices baked in, and it is not wrong exactly, but it is also not the whole story because being successful in Azure and being successful as a business are two completely different outcomes. The framework assumes you will figure out the gap yourself. Barbara Forbes is an Azure MVP who has watched a lot of these rollouts go sideways. She uses a specific comparison for this. On-prem used to work like a policeman standing in an intersection. Every request went through a person that person said yes or no, and it was slow. But it was controlled. The cloud replaced that policeman with a roundabout. No one is stopping you at a light anymore. You get freedom, you get speed, you get delegated responsibility, but there are still guardrails, still lanes, still a structure you are supposed to follow, but here is the problem. Just because you build a roundabout does not mean people know how to drive through one. You can put up the signs, you can paint the lines, you can follow every design spec in the documentation and you will still end up with cars stuck in the middle because nobody taught the drivers what a yield actually means. The structure existed, but the behavior never changed to match it. That is exactly what happens with M365. Microsoft hands you the roundabout, teams, sharepoint, copilot. A whole stack of governance tools are sitting there ready to go. And the assumption baked into the rollout is that people will just know they will know where files go, they will know which tool to use for which conversation, they will know that share with anyone is a decision, not a default, nobody forces anyone to learn the traffic rules. So people drive through, however, they used to drive through the old intersection. Now you have the same bad habits, just running on a new platform with better branding. This is the core idea of this channel. I'm going to keep coming back to it all episode. The model don't not the framework, the model the framework, KF the M365 adoption guide, none of that is what is breaking. What is breaking is the assumption sitting underneath the framework. It is the quiet belief that structure alone changes behavior. It does not. A roundabout does not teach anyone to yield. A landing zone does not teach anyone what data belongs where. A license does not teach anyone why they should change how they have worked for the last 10 years. So if the framework is not the problem, and the tools are not the problem, what exactly is everyone getting wrong? That is section two. Why adoption fails? It's never the technology. Here's the finding that shows up in every piece of research on this topic. It isn't subtle. M365 rarely fails because of the tools, not once in the data does, SharePoint is confusing or teams is buggy, show up as the root cause of a failed rollout. The tools work, they have always worked. That is not where the breakdown happens. Microsoft's own adoption guidance admits this directly, and it is worth sitting with that for a second. Their documentation says, "Adoption projects fail when people do not understand why they need to change their behavior." Read that again. Not when people don't understand the interface. Not when training is insufficient. When they don't understand why. That is Microsoft, the company selling you the tools, telling you the tools were never the bottleneck. So if it is not the tools, where is the gap? It is in how differently everyone inside the organization interprets the same rollout. IT treats go live as a deployment event. Boxes checked, tenant configured, licenses assigned, done. Employees experience the exact same rollout as a UI update, new buttons, new logos, same job. Executives see it as a line item, money spent, checked off in a board deck, three groups, three completely different definitions of finished. And none of the match what adoption actually requires, the real failure sits in the space between license activated and behavior changed. That gap is invisible on a dashboard. You can have 100% license activation and 0% behavior change, and from the license report everything looks perfect. This is the gap where entire transformation budgets quietly disappear. And here is a number that should change how you read every rollout report you have ever received. Unmanaged rollouts, the kind where IT flips the switch and hopes for the best plateau around 30% effective adoption, structured change programs, the ones that actually address behavior instead of access, hit 70% or higher, same tools, same licenses, same company size. The only variable that moves the needle that much is whether anyone designed for behavior change on purpose. Now here is the moment that should actually break something in how you think about this. Usage numbers going up can still mean adoption is failing. Say that sits wrong with you for a second because it should. You can watch Teams messages climb, watch SharePoint edits climb and watch every chart in your reporting toolpoint up and to the right and still be looking at a failed adoption. Because rising activity does not tell you whether people changed how they work. It just tells you they are doing something inside the tool. Confusion generates activity too. So does duplicated effort. So does five people recreating the same file because nobody agreed on where it should live in the first place. This is the belief most leaders walk into these rollouts holding and it is wrong. The belief that activity is the finish line. It is not. Activity is just noise until you know what it is actually measuring. So if the tools are not the problem and activity is not proof of success, you are probably wondering what Microsoft's own framework actually tells you to do about any of this. Strategy the step everyone skips or fakes. So here is what the framework actually says to do first before you touch a single as your resource before you provision the single tenant setting. You are supposed to answer one question why are we moving at all that is it that is step one and here is the part that should bother you half the company is going through this skip it completely. Not because they are careless but because they already have the technology sitting in front of them and we have the technology starts feeling like a reason on its own. It is not. It is just an excuse dressed up as momentum. Barbara Forbes calls this out with a pattern she has seen over and over. A company's hardware is running out of support in three months so suddenly everyone is scrambling to migrate and the whole thing gets framed as strategy. It is not strategy it is a deadline wearing a strategies clothes nobody sat down and asked what they wanted the business to look like on the other side they just knew the old servers were about to become a liability and moving fast felt like the only option that is not direction that is panic with a project plan attached. The framework actually gives you a real vocabulary for this and it is worth using instead of guessing. There are migration triggers these are about cost complexity and agility. Basically getting out from under something that is slowing you down and there are innovation triggers. These are about scale new markets and capability you cannot build on your own like AI features you would never develop in house. Neither one is better but you have to know which one you are actually chasing because the plan looks completely different depending on the answer. A migration trigger once you moving fast and cutting cost and innovation trigger once you experimenting and building new capability. Confuse the two and you will build the wrong thing efficiently and here is where it gets expensive if you skip this step. If leadership does not know why you are doing this somebody with budget authority is going to ask that question halfway through the project. Usually right when costs start climbing past the first estimate and if there is no answer sitting ready funding gets pulled. Not because the project failed technically but because nobody upstairs ever agreed on what success was supposed to look like. You cannot defend a number nobody understands the purpose of this is why business justification is not optional paperwork. It is the thing that ties the whole strategy together you are supposed to build an actual financial model here not a guess tools like the tco calculator let you compare what your current infrastructure actually costs against what the cloud would cost side by side with real numbers. The pricing calculator gives you a monthly estimate before you commit to anything and once you're actually running cost management gives you live visibility into what you are spending versus what you projected. None of this is decoration it is the thing that turns we think this will save money into here is the model showing exactly how. So if you take nothing else from this section take this strategy was never about the cloud it is not about which tools you pick or how fast you can deploy them strategy is direction a destination that everyone in the room it finance the business site actually agrees on before anyone starts building anything once you know why you are doing this you still have not answered who is actually going to carry it. Planning centralized shared or total chaos now you're actually planning and the first decision on the table is who runs this thing the framework gives you three models to pick from centralized means one team controls everything every deployment every policy every approval it's that policeman standing in the intersection again shared management is the roundabout model you delegate responsibility. But you do it inside guard rails everyone agreed on ahead of time then there's decentralized this is basically where everyone gets a piece of Azure and figures it out on their own but here's the thing about decentralized that surprises people it's not automatically the wrong choice if you're a startup with 10 people and no legacy baggage decentralized can actually make sense the problem isn't the model itself the problem is that almost nobody picks it on purpose it's not a decision it's what happens when nobody makes a decision at all. The team needed resources nobody said no and six months later that's just how the company operates that's not planning that's an accident with a name attached after the fact once you've picked a model you have to figure out what happens to your applications this is where the six hours come in and they're worth understanding by what they actually do not just as a list of words rehost means you move it as is no code changes same setup just running somewhere new re platform means smaller adjustments you move into a managed database or a web app service without touching much code refactor goes further you make actual code changes so you can take advantage of platform features re architect means redesigning the whole thing maybe you break it into microservices maybe you move it to containers rebuild means starting over from scratch because the existing code isn't worth saving and retain or replace means you either leave it alone or you drop it for something that already does the job but here's a bias worth correcting rehost the lift and shift option gets treated like the embarrassing choice people think you only pick it if you didn't have time to do it properly that reputation isn't fair if your hardware is failing and you only have three months lift and shift isn't lazy it's the correct call for the constraints you're actually working under you don't get the full benefit of the platform right away but you get out of danger you can modernize later once you aren't in crisis mode none of this technical planning matters if the people side gets ignored this is where skills readiness plans come in they aren't a nice to have they are part of the plan itself you need to know who needs to understand what and at what level before anyone starts touching as your resources skipping this doesn't save time it just moves the confusion from the planning phase into production where it's much more expensive to fix this is where most organizations think they're ready they're not because there's a stage nobody plans enough time for the ready the landing zone isn't the finish line so you're finally at the stage where you build something real and this is where most technical teams feel like they've arrived you haven't what you're building here is called a landing zone the name tells you exactly what it is if you listen to it it's the structure everything else lands on it's not the goal it's not the win it's the ground floor you build so the actual workloads have some way safe to go but here's where teams get this wrong because a landing zone gives you access to management groups and policies there's a pull to what building every single piece just because it's available you can create 10 management groups you can write 40 policies that doesn't mean you should every extra layer you build because you can is one more thing someone has to understand later it's one more piece of structure that has to make sense to a person who wasn't in the room when you built it overbuilding doesn't make you safer it makes the whole thing harder to reason about and confusion at this level costs you later usually right when you can least afford it one of the more useful distinctions here is the split between corporate and online landing zones it comes down to a single question for every resource you place does this thing need to talk to everything else or does it just need a path outside that's the whole decision a resource that only needs external access doesn't need to be wired into your entire internal network giving it that access anyway isn't generous its exposure you didn't need to create and here's the principle underneath all of it the safest connection is no connection at all if something doesn't need to talk to your core network don't connect it every connection you add is a door and every door you don't need is a door someone eventually walks through by accident or worse on purpose the instinct to connect everything just in case is exactly what this phase is supposed to train you out of now here's where perfectionism quietly kills momentum there's a trap in the stage where teams ask are we ever really ready if you let that question run unchecked the honest answer is no you will never have perfect governance you will never close every policy gap before shipping something if you wait for that state you don't launch slower you don't launch at all teams sit in this exact phase for months they refine a structure nobody has actually used yet because ready kept moving further away the more they looked at it the fix isn't complicated even if it feels uncomfortable launch small learn fast keep improving you don't need flawless governance before workload one goes live you need enough governance that workload one is safe then you adjust as you learn what workload one actually needed perfect is not a prerequisite for shipping it's usually the excuse for not shipping and this is the part almost everyone gets backwards. The sequencing mistake that breaks everything. Most teams building in the Cloud start with a floor assumption, they assume there is a correct order, build the platform first, get it solid, get it clean, then hand it off to the people who actually build things, that assumption is the mistake. Barbara Forbes has watched these rollouts for years, and her insight is blunt, platform and workload have to move together, not one after the other. Not platform, then a pause, then the workload at the same time, that is the part nobody wants to hear. It sounds messier than a clean handoff, because in reality it is messier. But messy and working beats clean and empty every single time. Here's what the sequential version looks like in practice. A company decides they are finally serious about the Cloud. Their first move is standing up a Cloud Centre of Excellence that sounds responsible. You get the experts in a room, you define the standards, you build the governance model, you do it properly before anyone starts deploying real work. But here's the problem, nobody in that room has actually run a workload through that environment yet. They are designing rules for a game they haven't played. And the experts building it usually treat the moment the landing zone ships as the finish line. So what actually happens is teams end up stuck. You have a landing zone with gorgeous documentation. Every policy is defined, every management group is in place, it is a genuinely impressive piece of architecture, and it has zero applications running through it. Nobody has touched it because nobody built it with a real workloads actual needs in mind. It is a beautiful empty building, all structure, no tenants. The model that actually works looks different, it is supposed to look overlapping. You build the landing zone, but you don't stop there to admire it. You immediately push a first workload through, that is the only way you find out what the landing zone actually got wrong. Then you figure out how to connect that workload to what it needs. Then you bring in the next 10 workloads, not because 10 is a magic number, but because at that scale you start seeing patterns the first one couldn't reveal. Then you secure what you have built based on what you now know. Instead of what you guessed, only then do you call something a production workload. Every one of those steps bleeds into the next. That overlap isn't slopping as it is the design. And here is the part that breaks most governance work. One size fits none. If your center of excellence hands every team the exact same standard, you haven't created consistency, you have created friction. The whole reason the cloud was worth adopting was flexibility. Treating every workload identically is how you quietly kill the thing you were trying to gain. And this is exactly where M365 rollouts fall into the same trap, it just has a different name. The M365 version of the same failure, take that same sequencing mistake and translate it into M365 language, you will recognize it immediately. I'd lead the teams and SharePoint migration. They move the mailboxes, they provision the sites, they point the old file shares at new locations. Then somebody sends the email that says, "Cut over complete." As far as the project plan is concerned, that is the finish line. Everyone gets a badge for shipping on time. Except cut over isn't adoption, cut over is just the technical move. Nobody's behavior has changed yet. Treating that email as the finish line is the same mistake as calling a landing zone "Done" the day it ships. The research pattern here is consistent enough that it is almost boring. Adoption gets treated as a technical project from the start. Success is defined as "Everyone has an account." That is the bar, not "Everyone changed how they store a document." Not "Everyone knows where a decision should live." Just "Account exists?" license assigned? Box checked. It is the same trap as license activated from earlier. Except now it is dressed up as a completed migration instead of a completed deployment. And here is what is missing every single time. There is no adoption workstream running next to the technical rollout. Not a smaller one, not a rushed one, none at all. There is no behavioral reinforcement built into the plan. No champions network seated before go live to carry momentum into teams that IT will never reach. The technical team does its job. The migration succeeds by every metric they are tracking. And then everyone assumes behavior will follow the tools on its own. It won't, it never has. So what actually happens is predictable. Users take their old file share habits and rebuild them inside SharePoint, same folder structures, same final V2 really final naming conventions, same permissions chaos. Just a different logo on the sharing dialogue. Nothing about how people manage information actually improved. You spent real money moving the mess into a nicer container. The shell changed, the behavior didn't. And because nobody was watching for that specific failure, it goes unnoticed for months, sometimes years. Until someone stumbles into a governance nightmare during an audit and asks how it got this bad, I made this point on LinkedIn recently and it is worth repeating. Most M365 deployments fail before anyone even starts measuring activity, not during the measurement before it. The failure is baked in at the design stage. The plan only accounts for the technical migration. It never builds in a way to track whether behavior is actually shifting. By the time someone opens a usage dashboard, the failure already happened. The dashboard just hasn't caught up yet. Co-pilot makes this exact failure worse and it makes it faster. Here is the pattern showing up right now in real rollouts. Licenses get enabled across the organization before anyone has defined the use cases. Nobody has decided which workflows co-pilot is supposed to touch first. Nobody knows which teams need it most. Nobody knows what a good outcome even looks like. That isn't one failure. That is two failures stacked on top of each other. It is a governance failure because nobody decided what data co-pilot should touch. And it isn't adoption failure because nobody told anyone what problem this is supposed to solve. Enable first, figure it out later, isn't a rollout strategy. It is the lift and shift instinct applied to AI. Minus the lucky part where lift and shift at least gets your working server. So if activity isn't the signal, what is? Let's talk about measurement. Structural adoption versus feature usage. Research draws a hard line here. Most reporting tools completely blur it. Structural adoption measures if your organization is built to sustain a new way of working. Feature usage measures if people are clicking buttons, those are not the same thing. If you treat them as the same, you end up celebrating a rollout that is quietly falling apart underneath the surface. Feature usage is what every dashboard shows you. Monthly active users, teams messages sent, sharepoint edits logged, co-pilot prompts fired off, it is real data, it is easy to pull, but it cannot prove transformation on its own. These numbers never tell you why someone opened teams. Maybe they collaborated brilliantly on a project, or maybe they just could not find a file and send four messages asking where it went. The number looks identical either way. Structural metrics ask a different question entirely. They are harder to pull because most organizations never bother setting them up. Training completion is a big one. Not just did we offer it, but did people actually finish it? Survey sentiment matters. Do people feel confident using the system? Or are they quietly working around it because it is too hard? Champion participation is another signal. Are the people meant to carry momentum into their teams actually showing up and doing that job? Then there is governance clarity. Can someone explain who owns a specific site or channel without having to guess? Support ticket trends tell the real story. Are the same confused questions still coming in six months after launch? Or did they taper off because people actually learned the system? These numbers move slower. They are less flattering in a slide deck. And that is exactly why so many organizations skip them and go straight to the feature usage numbers instead. But here is the problem. Rising usage numbers can mean confusion just as easily as they can mean success. More teams messages does not automatically mean better collaboration. It might mean communication got more fragmented and scattered across channels. It might mean more people are asking the same question five different ways because there is no clear place to get an answer. A chart going up and to the right feels like proof. It isn't. It is just proof that something is happening. Not that the something is good. I want to be honest about adoption score here. It gets treated like a verdict in reality. It is just a signal. Adoption score is a useful benchmark for comparing your usage to similar organizations. That comparison has value. But it is not proof of business value. It is a usage number wearing a success costume. It is dressed up to look like an outcome when it is actually just an activity count with better branding. Leaning on it alone is the same mistake as leaning on team's messages alone. Just with a friendly name attached. So here is the fix. It is not complicated. It is just rarely done. Pay usage telemetry with surveys and actual business KPIs. Never trust one metric family by itself. Usage tells you what is happening. Surveys tell you how people feel about what is happening. Business KPIs tell you if any of it moved the outcomes leadership cares about. You need all three in the room together. If you use them in isolation. They will lie to you in different directions. Usage alone over-states activity as success. Surveys alone cannot prove behavior actually changed. And KPIs alone will not tell you why the number moved. Or why it stayed flat. Now let's talk about the part nobody wants to own. Governance. Governance bolted on its governance that fails. Here is the number that ties everything back together. 73% of Microsoft 365 deployments make the exact same governance mistake. Not similar mistakes. The same one. It happens across companies that have nothing else in common. Different industries. Different sizes. Different budgets. The mistake is this. They govern the tools. Instead of governing the platform as a system. Tool-centric governance is easy to miss from the inside. Permissions get configured app by app. Teams gets one set of rules. SharePoint gets another. One drive gets whatever the default happened to be the day it rolled out. There is no unified identity model tying it together. Because of that, the same person can end up with completely different access logic depending on which app they opened that morning. Ownership of individual teams and sites. Turns ambiguous fast. Someone spins up a team for a project. That project ends six months later. The team just sits there. It stays active. It holds whatever got shared inside it. This happens because nobody was ever assigned to close it out. When you multiply that by a few hundred sites. You get a sprawling mess with no single person accountable for any piece of it. System-level governance treats this completely differently. Identity. Life cycle. Automation. And policy. All of it gets handled as one connected model that spans every workload. It is not four separate decisions made by four separate teams on four separate timelines. The team gets created with a life cycle attached to it from day one. An owner is assigned. An expiration policy is set to trigger. Identity rules apply the same way whether someone is in teams. SharePoint or Outlook. It is not glamorous work. But it is the difference between a platform you can understand. And one way every question requires digging through a different admin panel to get an answer. If you get this wrong, the consequences are not abstract. They show up as real exposure. Data gets overexposed because sharing defaults never got locked down. Anyone with the link becomes the path of least resistance for people who just want to get their work done without asking IT for permission first. Compliance gaps sit there quietly until someone finds them during an audit. And an audit is exactly the wrong moment to discover a problem. By then, it is not a fix. It is a disclosure. This connects back to the conversation we had about Azure. Remember the network engineer who said the safest connection is no connection at all. That logic does not stay inside the network layer. It applies just as hard to sharing an access inside Microsoft 365. Every link said to anyone is a connection you did not need to create. Every guest account with standing access to more than they are using is a door left open. It stays open because closing it felt like extra work nobody signed up for. The instinct that protects a network, which is to default to the minimum necessary, is the exact same instinct that protects a tenant. So what does good actually look like here? Baseline policies get defined before the rollout. They are not retrofitted after the fact once something has already gone wrong, sharing defaults, retention rules, identity requirements. All of it is decided while the tenant is still empty. You do not want to patch these in after 300 sites already exist within consistent settings. Governance built this way is not a reaction to a problem. It is the thing that prevents the problem from having a chance to start. This is where the accountability question comes in. And it is uglier than most leaders admit. Accountability gaps when everyone owns nothing. Research keeps surfacing a specific pattern. It is an uncomfortable one to sit with if you are the person who signed off on the budget. Sponsors exist to fund the project. They don't exist to own the behavior change that project was supposed to produce. What typically happens is simple. Someone in finance or leadership approves the spend. They get the project moving, they show up for the kickoff, and then, functionally, they disappear. They leave the part of the work that actually determines whether anything changes. Because budget approval isn't the same as accountability. Treating it that way is how a rollout ends up fully paid for and half adopted. Once that gap opens up at the top, it spreads through the rest of the organization fast. IT assumes collaboration design and data protection belong to security. Security assumes it belongs to whoever is managing the Microsoft 365 tenant day to day. HR assumes it's an IT function because it lives inside software. Operations assumes someone already decided this month ago, and they just never got the memo. Every single group has a reasonable sounding excuse for why it's not their job. And every one of those excuses is technically true from where they're standing. Nobody is lying. They're just all looking at each other, waiting for the person who's supposed to own this to step forward. But that person doesn't exist yet. This is exactly where the center of excellence quietly fails. It's a subtler failure than most people expect. On paper, the COE is supposed to be the group that owns this. In practice, it exists as documentation, a wiki page, a set of slides from the kickoff, a folder full of standards nobody is required to follow. It was never built as an enforced control plane. It has no actual authority to approve, block, or redirect decisions. It's a reference, not a rule book, and reference material doesn't stop anyone from doing something risky. It just sits there so people can point to it after the fact and say the guidance existed. This is the Gaparassi model is built to close. It's worth being plain about what those letters actually mean, instead of treating it like jargon. Responsible is the person doing the work. Accountable is the person who answers for whether it got done right. There should only ever be one of those per decision. Consulted is everyone whose input matters before a call gets made. Informed is everyone who just needs to know once it has. If you skip this structure, you don't get flexibility. You get paralysis. Decisions stall because three different people think they're the one who's supposed to approve something. Or worse, none of them think it's them. Instructions conflict because two different teams gave two different answers to the same question. Nobody above them noticed until a user got caught in the middle. You can see this play out in real time with co-pilot. Rollout stole constantly for exactly this reason. A team wants to use it for a new workflow that is genuinely useful, but the request just sits there. It isn't because the technology can't support it. It's because nobody can say with confidence who's allowed to approve a new AI use case. Is it securities call? Legal's it's the business unit's own. In an organization without clear accountability, the answer is often, let's set up a meeting to figure out who decides. And that meeting takes three weeks to schedule. So let's go back to the model that actually works when this is done right. What good actually looks like the adopt loop. The path barbre forbs lays out when things go right is worth stating plainly. It's simpler than the failure mode we just walk through. Landing zone, first workload, connect, first 10 workloads, secure, first production workload, six steps. And none of them wait politely for the one before it to be finished. Why does this loop actually work when the sequential version doesn't? Because it forces platform teams and workload teams to keep talking to each other the whole way through. They don't just meet once it kick off and then again at the post mortem. When a workload goes through the connect phase, the platform team learns something real about what their landing zone got wrong. Now there's an actual application sending actual traffic through it. That's better than a policy document describing traffic in the abstract. That feedback has nowhere to go if the platform team already packed up and moved on. The loop only works if both sides are still in the room. And here's exactly what happens when they're not. Platform engineers ship the landing zone, call it done, and shift their attention elsewhere. From there side, the job is complete. The structure exists, the policies are attached, box checked. Except nobody has actually run a workload through it yet. So nobody has found the gaps or the awkward permission boundaries. Nobody found the policy that blocks a legitimate use case because nobody thought to test for it. Six months later, a workload team hits that wall. And there's no one left who considers it their problem to fix. The workload team didn't build the landing zone so they don't feel empowered to change it. The platform team already moved on, so they don't feel responsible for touching it again. That's not a technical gap. That's an ownership gap. It's the same shape as the accountability problem we just looked at. It's just showing up one layer down. The fix isn't complicated to describe even if it takes discipline to hold on to. Shared responsibility. Designs get built together. Platform and workload people stay in the same conversation. You stop one side from finishing their piece and lobbing it over a wall for the other side to deal with. When a workload team pushes back on a policy that isn't friction to root around. That is the exact signal the landing zone needs to actually improve. You have to treat it as data, not as a complaint. This maps directly onto Microsoft 365. The shape is identical even though the players have different job titles. Instead of platform and workload teams, you've got a champions network, IT and business ownership. The principle applies word for word. These groups need to work the loop continuously. They cannot hand off to each other in sequence. I can't build the tenant, declare the cutover complete and hand a stack of documentation to champions. They can't expect the champions to carry it from there. Champions can't operate in isolation from business ownership either. They need real workflows to anchor training around. They don't need generic modules built for nobody in particular. All three groups have to stay in the same ongoing conversation. It's the same way platform and workload teams do in the Azure version of this loop. The moment any one of them checks out early, you get the exact same empty landing zone problem. It's just wearing a share point site instead of a subscription. None of this works without training that actually changes behavior. It can't just be about awareness. Training is not awareness, it's behavior change. Let's be direct about something most companies fudge on their rollout slides. A luncheon learn is not training. Getting 40 people into a room for 30 minutes to watch a co-pilot demo while they eat a sandwich is just an announcement with catering. It builds awareness that a tool exists. But it does not build the skill to use it inside a real workflow. Those are two completely different outcomes. And yet, they keep getting reported as the same line item. Here is the pattern showing up across co-pilot rollouts right now. Licenses get pushed out to an entire department at once. Then the training gets reduced to a vendor demo. Someone from Microsoft or a partner walks through a polished set of slides and shows a few canned examples. They say some version of this will save you time. But there are no concrete examples tied to what that specific team actually does all day. There is no walkthrough using their real documents. They are real emails or real meeting notes. It is just a general promise that time will be saved once people figure it out on their own. The fix is almost embarrassingly simple. You have to define 5 to 7 high value use cases per business unit before you deploy. Don't say co-pilot can help with a lot of things. Instead, say, here are the 5 things it does for finance or here are the 5 things it does for legal. These must be concrete tasks that someone already does every single week. That is the difference between a demo and training. A demo shows you what is possible in general. Training shows you exactly what to do with the work you are already stuck doing on Tuesday afternoon. And here is a detail that changes how adoption actually spreads. Deploy co-pilot to teams, not individuals. When you hand out licenses one person at a time across an org chart, you leave everyone to figure it out alone at their desk. But when you deploy it to an intact team, social learning kicks in. Someone finds a prompt that works for a weekly report and the person sitting three seats over copies it. Peer validation drives real adoption better than any training deck ever will. People trust what they see their co-workers doing more than they trust a slide that says it should work. There is one more piece that has to be built in as policy. It is what the research calls the review habit. Nobody should trust AI output blindly. This is not a nice to have you get to if you have extra time. It is a structural requirement. Just like MFA is a structural requirement and not an optional security tip. Every piece of co-pilot output must be checked by a human before it goes anywhere that matters. Every time. No exceptions for being in a hurry. If you skip that habit, you don't have an adoption problem. You have a governance failure with an AI logo on it. Now, here is where culture eats every framework alive if you let it. Culture and mental models. The layer frameworks ignore. Microsoft makes an admission in its own adoption guidance that is more honest than most companies are willing to be. Adoption fails when organizations focus on visible events and ignore culture and mental models. It doesn't fail because the tool is broken. It doesn't fail because training was skipped. It fails because leadership spends all its energy on the launch and the announcement. But never touches the actual thing sitting underneath it. They never touch how people think work is supposed to happen. Let's make that concrete. Mental models sounds abstract until you watch it play out in a real inbox. People have spent decades thinking about work in terms of email and shared drives. If someone needs a decision, they email the person who can make it. If someone finishes a document, they save it to a drive and email a link. At this point, that is not a habit. It is an instinct. So when teams shows up, it does not replace that instinct. It just gets absorbed into it. Teams becomes chat. A slightly faster way to ping someone instead of emailing them. Meanwhile, the actual decision still happens in someone's inbox. Nothing about where authority lives or how information moves has actually changed. You have a new interface sitting on top of an old assumption. And the old assumption always wins if nobody challenges it directly. This is why quick wins and cherry-pick pilots don't fix the actual problem. You can run a pilot with one enthusiastic team and get them using teams channels beautifully. You can show a slide with a nice usage chart and call it proof. But a pilot like that does not touch how the rest of the organization thinks about ownership. It does not change the assumption about transparency or where information is supposed to live by default. It is just one team performing well inside a system that everyone else is still quietly ignoring. Cherry picking a good result is not the same as changing the underlying belief that produced the bad ones everywhere else. This is the moment where the model earns its place as the core idea of this episode. You can install every single tool correctly. You can activate the licenses, provision the sites, and configure the permissions. You can schedule the training and name the champions. And you can still fail completely because the underlying assumption about how people actually work never got challenged. The tools were never the obstacle. The obstacle was always the belief sitting underneath them and beliefs do not update just because the software around them did. Think back to the roundabout one last time. The structure was never the problem. Roundabouts work. They are a genuinely better system than a traffic light with someone standing in the middle, directing every car by hand. The problem was the missing instructions. It was the assumption that people would just look at the new structure and understand it without being taught how. M365 is the same shape. The platform works. Teams works. SharePoint works. Co-pilot works. What is missing? Every single time this fails is someone actually teaching the organization the new rules for how information is supposed to move. You cannot assume the interface will explain itself. So does that mean we scrapped the framework? No. Here is what it is actually for. The framework still works, but only as a guide. Let's be honest about what CAF and the M365 adoption guide actually are. Everything we've walked through so far could sound like an argument to throw them both out. But that's not the point. These are proven, battle-tested pieces of guidance. Built from thousands of real deployments across companies of every size. They aren't wrong, but they aren't a single truth either. And that distinction matters more than it sounds. The right posture to what all of it is the same phrase we used for landing zones. One size fits none. That isn't a criticism of the framework. It's an instruction for how to use it. You take the structure Microsoft built, and you adapt it hard to your own org's actual size and actual maturity. Not the maturity you wish you had. Or the one a CAF study assumed you'd have. Applied is written. Without adjustment. It fits almost nobody perfectly. Adjusted with intention. It fits almost everybody well enough. But here's the problem. A small company with 30 employees does not need the full enterprise-scale landing zone. With every management group and policy tier, the framework describes for a 5,000 person organization building all of that anyway isn't thoroughness. It's over-engineering, wearing the costume of best practice. And it costs that small company real-time and real confusion for protection it doesn't need yet. Meanwhile, a large enterprise that skips that same rigor because it seems like overkill is skipping the exact governance that keeps the company at size from quietly falling apart. What looks suffocating at 30 people is basic hygiene at 5,000. The framework doesn't fail either company. Applying it without adjusting for scale does. There's a smaller detail worth sitting with here. Because it says something about the framework's own trajectory. The documentation itself used to run about 3,600 pages, but it's roughly 1,300 now. That isn't because the guidance got worse or thinner in substance. It's because the people maintaining it got more disciplined about what actually needed to be said. And even at 1,300 pages, nobody's realistically reading that cover to cover before they touch a single resource nobody's expected to. So here's the honest use case stated plainly. Use it as a map for direction. Not a rulebook you follow line by line expecting a perfect outcome if you just comply closely enough. A map tells you where north is. It doesn't walk every step of the road for you. And it definitely doesn't know your specific terrain better than you do once you're standing on it. So if you're starting from scratch or you're fixing a rollout that's already broken. Here's the sequence that actually holds up. M&A and systemic integration. Where this gets tested hardest. There's one place where everything we've talked about stops being theoretical and starts showing up directly on a balance sheet. Mergers and acquisitions. When two companies combine and their M365 environments have to become one. Every structural weakness we've walked through gets tested at the same time. Under a deadline with money attached to the outcome. Post-merger integration is where structural adoption failure stops being a slow, quiet drag on productivity. And turns into a number someone in finance has to explain. The research on this breaks measurement into three domains. It's worth naming all three. Because most integration teams only track one. First, there's technical integration health. Did the tenants, the identities and the data actually merge cleanly? Second, there's user adoption and behavior change. Are people from both companies actually working the new way? Or are they still quietly running two separate systems side-by-side because nobody forced the decision? And third, there's business synergies and risk. Is any of this technical and behavioral work translating into the financial outcome the deal was actually built to produce track only the first one? And you'll have a beautifully merged tenant that nobody's using correctly. Track only the second. And you'll have happy users with no idea whether the merger is actually paying for itself. Here's a detail from that research that deserves to be said plainly. It's a gut check for anyone who assumes a migration when fine, just because nobody complained. 20 to 30% of migrated records typically need some kind of remediation after the fact. That isn't a failure, that's the expected range. Duplicate entries, broken metadata, permissions that didn't map cleanly from one system to the other. This is just the normal friction of moving real data between real environments. But once that number climbs above 40%, you're not looking at normal friction anymore. You're looking at a migration that got rushed, where corners got cut to hit a deadline. And the cleanup bill is going to land on someone's desk eventually. And this is where the financial expectations get set wrong almost every time. Revenue synergies, the actual new value the combined company is supposed to generate like costs synergies by 6 to 12 months. Cost savings show up fast. Cutting duplicate licenses and shutting down redundant systems is mechanical work. But revenue growth from better collaboration. Faster deal cycles. And shared customer data actually being used well. That takes people time to build into their daily behavior. So if leadership is only measuring results in the first 100 days, they're measuring the part of the story that was always going to look good. And they are completely missing the part that actually proves the deal worked. This is the lesson worth carrying past M&A entirely. It applies to any org running any kind of structural integration, merger or not. This kind of change takes longer to show real value than leadership wants to admit. And that isn't a problem to solve. That's just the honest timeline. The fix isn't rushing the number. It's setting the expectation correctly upfront. It's telling the people funding this that month three will look different from month 12. Judging the whole effort by the early numbers alone is how good integrations get killed before they had a chance to prove themselves. Let's pull this together into what you actually do Monday morning. The governance first sequence that actually prevents failure. So here's what you actually do. It is a sequence. And the order matters because it has to hold up under pressure. Governance ordered first. Not after the rollout, not as a cleanup project six months later when the sprawl becomes impossible to ignore. You need to answer four unglamorous questions before you build a single workload. First, where does identity come from? Is it one clean source or five systems stitched together with duct tape? Second, who holds admin roles right now? And can anyone actually explain why they have that access? Third, what is your default sharing posture? Is it locked down or is it wide open because nobody changed the Microsoft default settings? Fourth, what are your retention assumptions? Are they written down or are they just vibes and hope? If you answer those four questions honestly, you avoid the mistake that catches most companies from there. Security requirements are not negotiable. They are not complicated either. Which is why skipping them is hard to excuse. MFA everywhere. No carve-outs for the executive who finds it annoying. Conditional access rules that check device health and location. Not just a password. Roll separation. The person who approves the policy should not be the same person that policy is supposed to constrain. And classification tied to actual record categories. Your labels need to match real data your company handles. Not a generic template nobody customized. This is the floor. Not the ambition. The floor. Once that is solid, build the operating model before you scale. Who owns what? Spelled out by name. Not by department. Which group actually approves a new service request? You need this so it doesn't turn into a three week scheduling nightmare where use cases just stall out. What is the escalation path look like when something breaks? And who is empowered to say yes or no on the spot? Instead of promising to circle back? Only after all of that is sitting on solid ground, do you move to the part everyone wants to start with? Define use cases. Assign champions. Build a training curriculum around the workflows people actually run every day. The ordering matters more than it looks like on paper. Because skipping straight to use cases without the governance underneath is how you end up with enthusiastic pilot teams sitting on top of an ungoverned mess. And this is worth tying back to something Barbara Forbes said about policy. It applies just as hard here. Policies are not a set it and forget it task. Most companies land in one of two failure modes. Two few policies so there is no structure or too many policies. Layered on top of each other until nobody knows what is actually enforced. Either way, the maintenance stops. Someone writes the policy. Feels good about it and never opens that document again. Governance that isn't revisited isn't governance. It's an artifact. And once governance holds, here is how you know if adoption is actually working. Building your actual scorecard. Here is the scorecard. It is laid out in three layers. And none of them work alone. That is the whole point of building it this way. The structural layer comes first. It tells you if the foundation can actually hold weight. Training completion. The real number. Not training was offered. But what percentage of people actually finished it? Survey sentiment, pulled it intervals. Not just once at launch when everyone is still excited. Champion activity. Are the people assigned to carry this into their teams actually showing up? Or did that title stop meaning anything after week two? And ticket trends are the same confused questions landing in the queue six months out? Or have they tapered off because people actually learned the system? The usage layer sits on top of that. This is where most companies start and stop. Which is exactly the mistake we spent the last several sections dismantling. MAU by workload do not lump teams. SharePoint. And one drive into one number. A spike in one can hide a total collapse in another. FeatureDepth matters more than log-in counts. Someone opening teams once a day to check a notification is not the same as someone actually running meetings and co-authoring documents. And co-pilot prompt frequency. Paired with satisfaction. Do not report these alone. A high prompt count from someone who hates the output isn't adoption. It's frustration with extra steps. The outcome layer is the one almost nobody builds. And it is the one that actually matters to the people funding this. Cycle time reduction is a process that used to take four days now taking two times saved, measured against a real baseline, not a vendor's estimate of what should be possible. Resolution speed for support tickets, customer requests, or internal approvals. Every single one of these has to tie back to a real business KPI. Something leadership already tracks and already cares about. Not a vanity metric invented to make the rollout look good on a slide. Here is the rule that ties all three layers together. It is the one thing worth writing down if you remember nothing else. Never trust one layer alone. A structural layer that looks great. With a usage layer that is flat. Means people are trained and happy and still not using the thing. That is its own kind of failure. A usage layer that is climbing with an outcome layer that is flat is the most dangerous combination of all. It looks like success everywhere except in the place that actually counts. Rising usage with flat outcomes is not a win. It is a warning sign. It is dressed up in a chart that goes up and to the right. And it is exactly the kind of number that gets celebrated in a leadership meeting while the actual problem sits there unnoticed. Let's bring this back to the one sentence that matters most. The real transformation. Nobody puts on a slide. Strip away the framework diagrams. Forget the governance checklists. Here is the one sentence that actually matters. The framework was never the point. The model behind how your organization assumes people work. That is the point. It has been the point this entire episode. Even when we were deep in the weeds talking about landing zones and russy charts. Let's take one last pass at the roundabout. This time it's not a metaphor. It's the reality of your environment. The structure works. Roundabouts move more traffic with less waiting than a cop standing in an intersection. Ever could. Teams, SharePoint and Copilot are built on that same logic. Freedom with guardrails. Instead of someone manually approving every single move. But that structure only works for people who were actually taught how to enter it. They have to know how to yield. They have to know how to merge without causing a pile-up. Nobody is born knowing how to use a roundabout. And nobody is born knowing that a team needs an owner and an expiration date. Both of those things have to be taught deliberately. Or the structure just becomes a more elegant way to create the exact same confusion. Here is why this matters more right now than it did two years ago. Copilot does not fix a broken model. It just moves faster through whatever model already exists. If your organization has clear ownership, Copilot multiplies the good version of how you work. But if ownership is already fuzzy, if nobody can tell you who owns a site or why a workload move to the cloud, Copilot does not slow down to wait for you. It just runs the dysfunction at a higher speed. Bad hand-off skates are automated. Unclear approvals get skipped instead of clarified. Whatever gap existed before AI finds it and drives straight through it. That is the stake. State it as plain as I can put it. The organizations that fix the model now are the ones who will survive. They are the ones who actually assign ownership, who actually build the operating model. And who actually teach people the new rules instead of assuming the interface will explain itself. Those companies will absorb the next wave of AI change without living through another failed rollout. Everyone else is going to keep doing the same exercise every 18 months. New tool, same governance gaps, same accountability confusion, just a different logo on the announcement email. So what do you actually do with this on Monday? Here is what you are walking away with. You now know why adoption fails structurally, not just technically. You know what actually predicts success in the data. Governance built before rollout. Accountability that is named instead of assumed. Matrix that measure all three layers instead of just the one that looks best on a slide. So here is the actual homework. This week, ordered one workload's governance model, just one. Pick something running in your tenant right now and ask two questions. Who owns this? And could anyone in your organization actually explain why it moved to the cloud in the first place? If the answer to either one is silence, you have found where to start. If this changed how you think about your own rollout, follow me, Mirko Peters, on LinkedIn, send me your messiest adoption story. The one you would never put in a case study, it might be the next episode. And if you want more of this, leave a review, it helps more people find it.