 EN
 Deutsch
 Español
 Français
 Italiano
 Português
 Nederlands
 Polski
 Bahasa Indonesia
 Русский
 Українська
 العربية
 עברית
 हिन्दी
 日本語
 한국어
2026-09-16 · Season 4
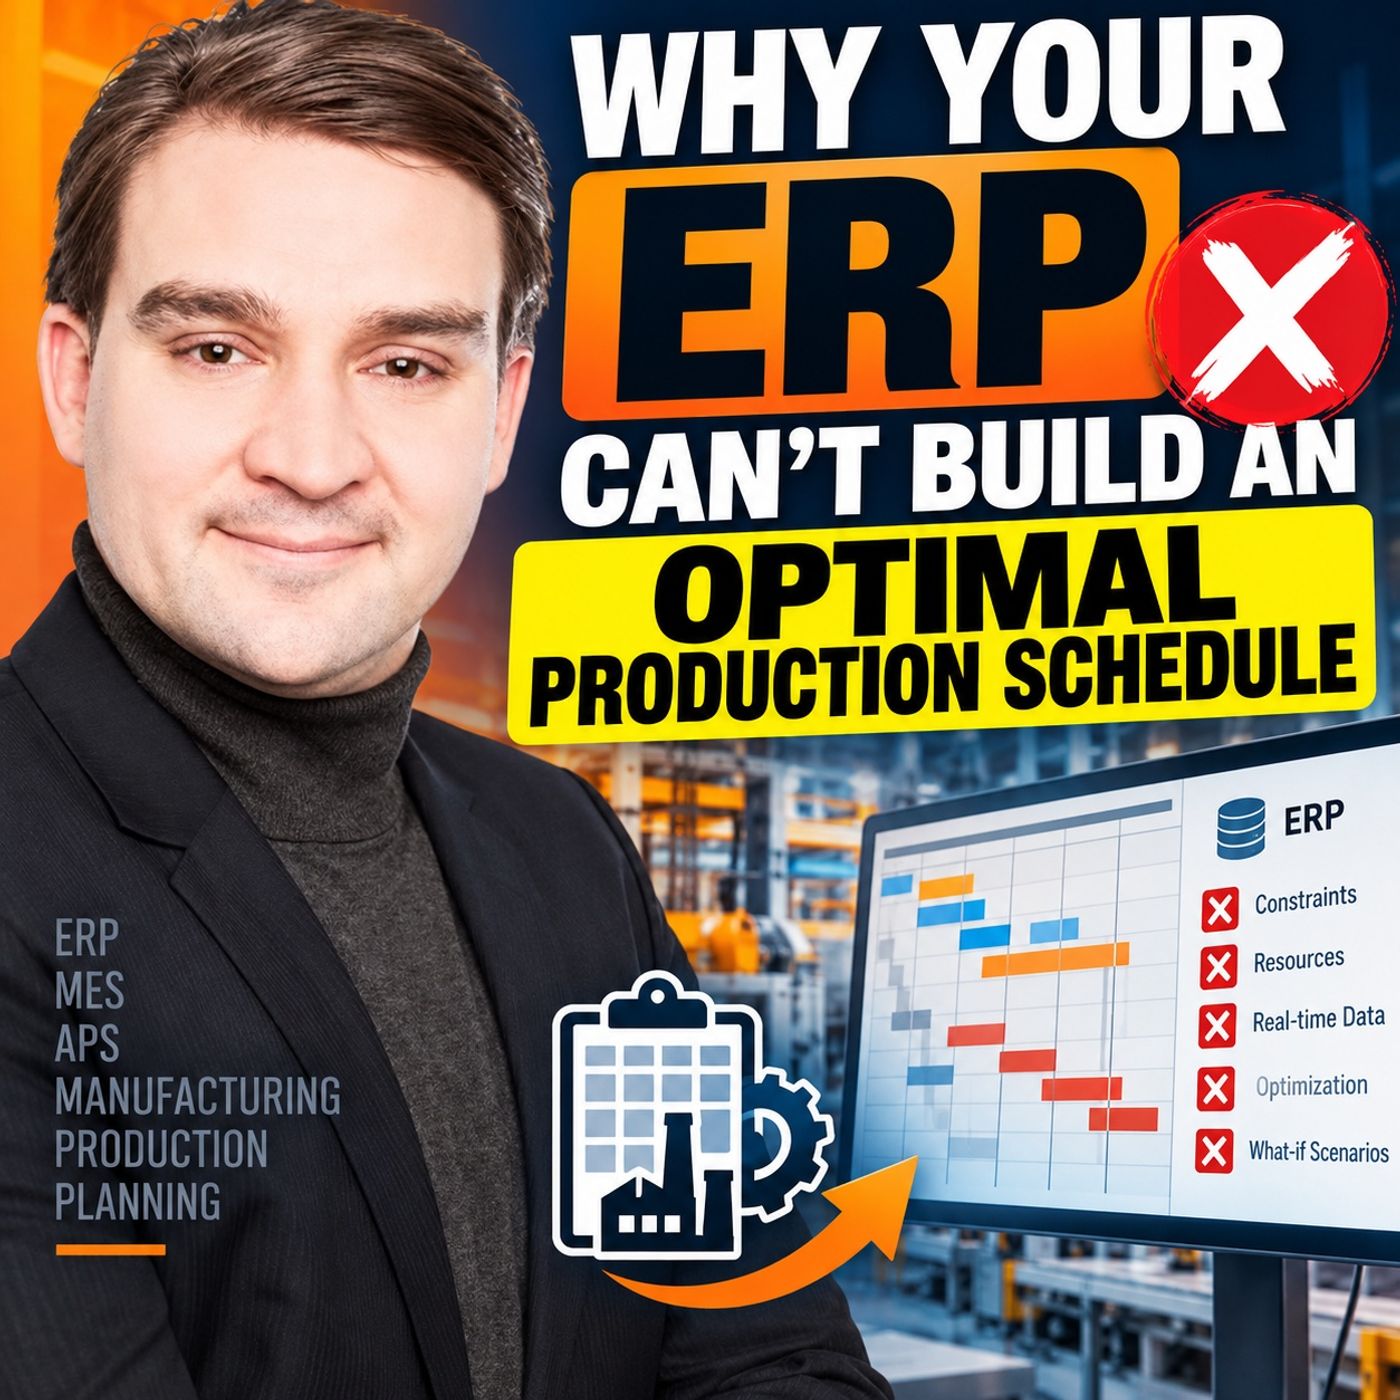
Why Your ERP Can't Build an Optimal Production Schedule
Show notes
Your ERP can calculate production dates, explode demand through MRP, manage routings, inventory, purchase orders, and production orders. But that does not automatically mean it can create a production schedule that your factory can actually execute. In this episode, we break down the gap between ERP planning and finite production scheduling — and explain why a schedule can look perfectly reasonable in the ERP while multiple orders are competing for the same machine at the same time. THE INFINITE-CAPACITY PROBLEM Traditional ERP planning can place demand against resources without reserving finite blocks of actual machine time. This “infinite capacity” assumption is useful for demand and material planning, but it becomes a problem when planned dates are treated as executable shop-floor commitments. A capacity report may show that a machining centre has 40 hours of demand against only 16 available hours. It identifies the overload — but it does not decide which orders should run first, which should move, or how those decisions affect downstream operations. CAPACITY IS MORE THAN MACHINE HOURS Real production capacity depends on much more than a work-centre calendar. Machines have downtime. Operators have qualifications and shift patterns. Fixtures and tooling may already be occupied. Quality inspections consume resources. Maintenance removes capacity. And an eight-hour shift rarely provides eight hours of usable production time. A feasible schedule therefore has to consider the combination of machines, people, tooling, fixtures, calendars, maintenance, and process rules. WHY SEQUENCE MATTERS Production sequence can dramatically change the result. Running similar product families together might require only one major setup. Alternating between families can create repeated tool changes, cleaning, inspections, or fixture changes. The same orders on the same machine can therefore consume very different amounts of capacity depending on their sequence. THE BOTTLENECK SETS THE PACE When many orders depend on one constrained resource, keeping every upstream machine busy can actually make performance worse. More work enters the system, queues grow, WIP increases, and priorities become harder to see. Effective scheduling instead protects bottleneck capacity and controls when work is released into production. MATERIAL AVAILABLE DOESN’T MEAN READY TO RUN MRP may show that material exists, but that material could be under quality hold, reserved for another order, waiting for inspection, or incompatible with a specific batch requirement. Finite scheduling needs to combine material readiness with resource availability. A component arriving Wednesday only helps if the required machine also has a legal production slot when the material becomes usable. ROUTINGS DON’T RESERVE CAPACITY A routing tells you what comes before what. It can define cutting → machining → inspection → assembly. But a routing does not necessarily reserve the actual resource time required to execute those operations. Several orders can follow perfectly valid routings and still collide at the same machine or work centre. WHY EXCEL KEEPS SURVIVING This gap explains why planners continue using spreadsheets, whiteboards, notes, and local priority lists. They are combining information from ERP, MES, maintenance, quality, production, and their own shop-floor knowledge to create the schedule the factory actually follows. Excel is often not the root problem — it is the workaround for scheduling logic that exists outside the ERP. WHAT FINITE SCHEDULING CHANGES Finite scheduling treats production time as something that must actually be reserved. If an operation needs four hours on a machining centre, those four hours occupy a real slot. Another job cannot use the same resource during that period. The same logic can include operators, tooling, fixtures, and other required resources. When there is no legal slot, the system has to expose the conflict instead of hiding it behind another planned date. FROM FINITE SCHEDULING TO OPTIMISATION Once several feasible schedules exist, constraint-based optimisation can compare them. Should the plant minimise late orders? Reduce setup time? Protect bottleneck throughput? Avoid overtime? Reduce WIP? Keep the near-term schedule stable? There is rarely one universally “optimal” production schedule. The best schedule depends on the constraints the factory cannot violate and the business objectives it chooses to prioritise. ERP VS. MES VS. APS ERP remains essential for demand, orders, inventory, purchasing, bills of material, and transactional planning. MES provides execution truth from the shop floor. APS adds the decision layer: combining demand, materials, routings, resource availability, constraints, and current production status to create a finite, constraint-aware schedule and test alternative scenarios. IN THIS EPISODE You’ll learn why ERP schedules become overloaded, what infinite capacity really means, why bottlenecks and sequence-dependent setups matter, how material availability differs from production readiness, why planners fall back to Excel, and how finite scheduling and constraint-based optimisation turn production dates into an executable plan. The key idea is simple: ERP tells you what needs to happen. A production schedule has to prove when and where it can actually happen. Become a supporter of this podcast: https://www.spreaker.com/podcast/m365-fm-microsoft-365-azure-cloud-power-platform-ai--6704921/support.
Apple Podcasts · Spotify · YouTube · Deezer
Host: Mirko Peters
Related articles
Transcript
Read the full transcript
Picture this, a customer calls about an order promised for Friday. Your planner opens the ERP schedule and it looks fine. Every operation has a date, every work order is released, but one machining work center is carrying more load than any real shift could ever process. The schedule looks complete, but production just can't run it. That's the contradiction every manufacturer hits eventually. Your ERP can place work against a date, but the machine has finite hours, real downtime, and a physical limit. So why can't ERP just build an optimal schedule? Let's start with what the ERP schedule actually does and where it stops being useful. What ERP planning is built to do. ERP has a big job and it does it well when the data is maintained properly. It's the system of record for customer demand, sales orders, purchase orders, inventory, bills of material, production orders, and the financial trail around all of it. Think of the ERP as the place where the business agrees on what it needs to make, what it has bought, what it has promised, and what it still needs. That matters because without that shared record planning becomes a pile of local files, phone calls, and people trying to remember which version of an order is actually real. When a customer order arrives, the ERP connects that demand to a product structure. The bill of material tells it which components the product needs. The routing tells it which production steps the product should follow. Inventory records show what stock is on hand, and purchasing data shows what still do from suppliers. Now material requirements planning? MRP does the work it was designed for. MRP takes that demand and translates it into supply needs. It can propose a purchase order for a missing component, suggest a production order for an assembly and work backward through several levels of a bill of material. That logic solves the real problem. If you need a finished product in six weeks, MRP helps you figure out which parts must arrive first, which subassemblies need production, and when planning should release those orders to the floor. This is demand and supply coordination, not a minute by minute plan for the shop floor. Keep that distinction in mind, because it matters. Now let's talk about how dates enter the picture. A customer requests delivery on a certain day, or your sales team commits to one. The ERP works backward from that date through the routing. If final assembly takes one day, that operation needs to finish before shipment. If machining feeds assembly, machining needs to finish first. If raw material needs lead time, purchasing needs to act even earlier. That's backward scheduling. It starts with the required completion date and calculates earlier dates for each operation, based on standard durations, lead times, and calendars. At first that sounds exactly like scheduling, and it is scheduling in one sense. The ERP gives every operation a plan start and a plan finish. It accounts for a work center calendar, normal working days, shifts, weekends, and public holidays. It uses standard setup time, runtime, queue time, and move time from the routing. Those dates have a purpose. They tell purchasing when material demand appears, help production control see what should be coming, support rough capacity conversations, and give customer service a planning basis when someone asks whether a requested date looks possible. But a planned date isn't the same thing as a physically executable slot on a real resource. Here's where the trouble starts. That distinction disappears because the date looks precise. A work order that says machining starts Tuesday at 8 in the morning creates a false sense of certainty, even when five other orders point to the same machine at the same time. The ERP hasn't necessarily done anything wrong. It followed the planning rules and master data you gave it. It calculated dates through a routing. It exploded demand through the bill of material. It created proposals and transactions that keep purchasing, inventory, production, and finance connected. That's a large part of what a manufacturer needs. But detailed shop flow scheduling asks a different question entirely. Detailed scheduling asks whether a specific machine can run a specific job at a specific time while other jobs compete for that same time. It asks whether the resource calendar is realistic, whether the order can actually start when planned and whether the sequence of jobs changes the result. ERP planning coordinates what the business needs to supply. Detailed scheduling coordinates how the factory can actually execute that demand. You need both and one doesn't replace the other. So let's follow one order through the ERP logic because that's where the gap becomes easy to hear. A simple factory order scenario. Let's walk through a plant that builds industrial pump assemblies. Customer orders come in mixed. Some are standard units. Others need a different impeller, a special seal, or a tougher material grade for a harsher environment. All of them pass through a shared machining center before they hit final assembly. That machining center sits right in the middle of the flow. Parts arrive as raw stock or semi-finished blanks, machining shapes them, inspection checks them, and downstream assembly puts the finished pump together. The plant might own several machines, but this particular center handles a critical operation that many orders need and almost no other resource can perform. Now imagine a customer places an order and asks for delivery on Friday. The ERP pulls up the product routing. It sees final assembly, inspection, machining, and the material steps upstream. It starts from the requested delivery date and works backward. Shipment Friday means final assembly has to finish before that. Machined components need to reach assembly before assembly starts and raw material must be available before machining can begin. On paper that logic looks clean say the ERP creates a production order for the pump housing. It schedules machining for Tuesday, inspection for Wednesday morning, and assembly for Thursday. It also sees the required material needs to arrive before Tuesday so purchasing or inventory planning gets the right signal. So far nothing unusual. Then another order hits the system. This one also needs that same machining center and its due date drives its machining operation into Tuesday as well. A third order already set in the plan also needing the same machined during that same period. Each order gets its own set of dates. Each routing looks internally correct. Each customer promise might seem reasonable when you view orders one at a time. But you can't run all three machining operations on the same physical machine simultaneously. That's where plan is start seeing the difference between a date calculation and a real schedule. The ERP might place order A on the machining center from 8 until noon on Tuesday, order B from 9 until 2 and order C from 1 until the end of the shift. The individual order plans don't know how to negotiate with each other. A person looking at the plan spots the conflict immediately. One spindle, one work area, one actual clock and a limited number of usable hours. Yet the schedule contains overlapping demands because every order calculated backward from its own target date. The ERP can still show all three as planned. It can still show material requirements, tell you that raw stock for order A arrives on Monday and material for order B is in inventory and create purchase proposals and inventory reservations that keep the supply plan moving. The material picture might even look sensible. For order A, the raw material arrives before the planned machining date. For order B, material sits in stock. For order C, a supplier delivery lands just before its plan start. From a material planning view, the system has connected demand, supply and dates in a way that seems consistent. But the physical plan cannot exist. There's only enough time for one job at a time on that machining centre. And the rooting dates don't force a choice between competing orders. Someone still needs to decide which job runs first, which job waits, and whether a customer date has to move. That decision ripples downstream. If order B shifts from Tuesday morning to Tuesday afternoon, inspection moves. If inspection moves, assembly may lose its planned slot. If assembly loses that slot, the Friday shipment might no longer hold. A small conflict at one shared machine travels through the whole order. This is why a planner can open an ERP schedule on Monday morning and already know it won't survive the week. The issue isn't that the orders lack dates, they have plenty. The issue is that those dates describe demand against a resource. Without proving the resource can actually perform all that work when the dates claim it will. And here's another uncomfortable detail. The ERP plan looks more believable as you add more master data, standard runtimes, Q times, shift calendars, planned lead times. Those inputs improve the planning picture, but they don't automatically force the system to resolve two jobs claiming the same moment on the same machine. So let's unpack the assumption, sitting underneath those dates. The infinite capacity assumption. That assumption is usually called infinite capacity. The name sounds ridiculous when you say it out loud because nobody believes a machining center can work forever. But it doesn't mean the ERP thinks the machine has unlimited physical power. It means the planning calculation can place demand on a resource without first reserving a finite block of its actual available time against all the other orders competing for it. That choice exists for a reason. ERP planning needs to process a lot of demand, supply, product structures, lead times, inventory positions, and purchasing signals across a whole business. It needs to answer broad planning questions quickly. What should we buy? What should we produce? And when must those actions begin if we want a chance of meeting demand? Backward scheduling gives the business a useful target date for those questions. It doesn't have to solve every conflict between every operation on every machine while it creates that target. If it tried to do all that across an entire plant with every change in demand and supply, the job becomes a much harder scheduling problem. So infinite capacity isn't a defect and it isn't an attempt to mislead anyone. It's a boundary around what the planning logic is trying to do. The problem starts when people treat the output as more than it is. A work order date can look like a commitment from production. When it may only mean if capacity exists at this point, this operation needs to happen around this time. That word, if carries most of the risk, take Tuesday in our pump factory. The ERP can assign several machining operations to Tuesday because each order needs machining complete before its own downstream dates. It calculates those dates through each routing, but it doesn't enforce one shared clock across every order at that work center. The work orders land on the day. They may even land in the same shift. Nothing in the date itself proves the required machine hours exist. Some ERP systems include capacity requirements planning, CRP, that can aggregate the load against the work center calendar and show that Tuesday carries say far more planned hours than the work center can provide. That view helps. It moves the problem out of someone's memory and into a shared planning conversation. But detecting an overload and resolving an overload are different jobs. A capacity report might tell the planner that a machining center has 40 hours of demand against 16 usable hours. That report has done its job. It exposed the gap. But it hasn't selected which orders should run, which order should move, whether another resource can process the work, or how a change will affect all the operations that follow. It counted the collision. It hasn't untangled it. That distinction matters because people often respond to an overload report as though the report itself created a plan. It didn't. The same 40 hours still compete for the same 16 hours. Printing the report twice doesn't produce another shift, another operator, or another machine. An overloaded Tuesday cannot become feasible through a dashboard, a color code, or a more detailed spreadsheet extract. Somebody needs to take work out of that period, move it to a legal slot, and test the consequences of that move. Maybe one order can shift to Wednesday without harming its customer date. Maybe another has a firm delivery promise and must stay. Perhaps the third order could run elsewhere, but only if that alternative resource can actually perform the operation. Or maybe none of those choices work. And the business needs to decide between overtime, subcontracting, a change promise date, or a different commercial decision. Those are real choices. Infinite capacity planning can reveal where the choices sit, but it doesn't evaluate them as a connected schedule. There's also a human side to this. When planners see overload after overload, they often build their own workaround. A private priority list, manual moves, calls to supervisors, mental notes about which customer will accept the delay and which product tends to create trouble. That knowledge keeps factories moving. It also shows that the actual scheduling logic lives somewhere outside the ERP date calculation. None of this means ERP dates are useless. They remain useful signals for material planning, demand coordination, and rough load awareness. The mistake is asking those dates to carry a decision they were never built to make. And finite machine time is only the first constraint. Capacity is physical, not a field in a table. Most planners never stop to consider something basic. A work center calendar can tell you a machine runs two shifts Monday through Friday. That's genuinely useful planning data. But it's not the same as knowing how much production time that machine can actually give you this week. Start with the machine itself. A calendar may show 16 available hours in a day, but the real shift includes handover, warm-up, plan checks, breaks, cleaning, and all those small interruptions that never appear as a neat block in a master data record. Think about what maintenance takes, too. Sometimes it's a planned service window everyone expects. Other times, a technician needs the machine for a short inspection after recurring alarm and production can't pretend that slots still exists just because the ERP calendar says the machine is open. That isn't poor discipline. It's factory life. Take a CNC machine with a nominal eight hour shift. The machine may need a start-up routine. The operator may need to verify the first part. A tool could hit its replacement limit halfway through and quality might require an inspection after a defined batch. Once you account for all those conditions, the usable time can differ quite a lot from the rated time. Rate capacity is the number you plug into a table. Usable capacity is what actually remains after the plant applies every condition needed to run safely, correctly, and predictably. That gap between rated and usable changes planning decisions. If a planner assumes an eight hour shift produces eight hours of machining, every order will look slightly more achievable than it really is. Add that error across several days and the schedule starts with hidden delay baked in from the beginning. A finite schedule needs to work with the capacity you can actually use, not the capacity you wish you had. Here's another basic rule that systems sometimes blur. A machine usually runs one job at a time and one milling center cannot machine two housings at once simply because two orders have the same date. A heat treatment furnace may process many parts in a batch but that's a real process rule with a defined load limit, temperature cycle and batch duration. Parallel work has to come from the process itself, not from the planning system trying to force dates to fit. You also need to ask what else the operation actually requires. The machine may sit empty, but the qualified operator could be assigned elsewhere. The tool package might still be at another machine. A fixture could be in use or waiting for inspection and the gauge needed for first off approval may not be available until later in the shift. In practical terms, a machining operation doesn't just consume machine time. It consumes a machine, a person with the right skill, a fixture, a tool set and sometimes a quality resource. If any one of those is unavailable, the operation cannot start. That's why a resource calendar alone only gets you part of the way. It can describe scheduled opening hours, planned holidays, and maybe a maintenance block, but it usually can't express every condition that turns a free hour into a productive hour without much deeper modeling and scheduling logic. Even when the data exists, someone needs to apply it altogether. The schedule has to reserve the machine for the operation duration, confirm the operator qualification, check that the fixture doesn't conflict with another order, and leave room for the inspection rule that production actually follows. Otherwise, the system creates a slot that looks available only because it sees one part of the job. I've seen planning discussions get stuck on whether a work center calendar is accurate, that matters, but it's the wrong place to stop. The better question is whether the planning model describes the real conditions that decide if this operation can begin and finish in that time window. If the answer is no, the calendar is still useful. It just isn't enough to build a schedule, people can execute without manual repair. So when someone tells you a machine has capacity on Wednesday afternoon, pause for a second, capacity for which job, with which operator using which tooling, after which maintenance activity, under what production rules. A free machine may still not be ready for the next job. Sequence changes the result. Even when the machine, operator, and fixture are already, another question remains, what should run first? That question sounds simple until you actually look at the work itself. The time between jobs can change based on product-family material-grade color, coating, toolset, or the cleaning standard that applies before the next part can enter the machine. A routing might tell you that a job needs 20 minutes of setup and that's often a useful average, but an average can hide the part planners care about most. The setup cost from which job to which next job, let's make this concrete. Say the machining center runs stainless steel parts in the morning, then changes to a softer alloy in the afternoon. That change may need a different tool pack, program checks, and a first piece inspection. Now imagine the next job requires a material that must not pick up residue from the previous one. The change over includes cleaning, a fresh fixture, and an extra approval step. These jobs don't carry the same transition cost the same pattern shows up everywhere. A paint line may need flushing between colors, a food or chemical process may need cleaning between recipes and a press line may need a die change. In heat treatment, a batch may need a different temperature profile and the furnace cannot simply switch because in order to do dates as it should. Production people know all this without a theory lesson, they call it common sense. The trouble begins when the plan treats every job as though it enters a resource from a neutral state. It doesn't. Every job leaves the resource in some state and the next job inherits that state. It either benefits from it or pays to change it, run five orders from the same product family together and the machine may need one major setup. Alternate between families because the ERP sorts everything by due date alone and those same five orders can trigger several setups, same demand, same machine, very different use of time. Here's a practical example. Suppose four pump components all need the same machining center, two belong to family A and two belong to family B. Each order has a customer date, but none of them need shipment today. One sequence runs A, A, B, B and the team completes two campaigns with one change between them. Another sequence runs A, B, A, B and the machine changes state three times. Those extra changes consume time, create more chances for error and push productive machining later into the shift. The second sequence may look fair from an order date view and it may even look more responsive because each customer sees some work begin early. But the plant completes less work when extra change over the eat the hours meant for processing parts. Due date results can shift in ways that aren't obvious at first. Grouping jobs by family may protect capacity and bring more total orders through yet one order with an earlier customer promise may need to interrupt that campaign. The planner has to weigh the cost of breaking the sequence against the cost of delivering that order late. That's a real production choice and a date field can't decide it by itself. Most rootings don't capture every relationship that drives setup time. They may record a standard setup duration for an operation which helps with rough planning, but the routing often doesn't state that changing from family A to family B takes longer than changing within family A. It also doesn't say that one material transition needs cleaning while another only needs a tool offset check. Sometimes those rules sit in work instructions. More often, they live in the head of the person who has run that machine for years. The schedule needs a way to express them. It can use rules like do not run this grade after that grade without cleaning or group jobs with the same coating where possible. It can also use cost-based logic where the model assigns a penalty to a costly changeover and lets the scheduling process compare that against the risk of a late order. That doesn't remove judgment. It makes the trade-off visible. A planner can then ask a useful question. Are we accepting an extra setup because this customer date truly requires it or are we doing it because the sequence came from a list that knows nothing about changeovers? Keep that in mind as we return to the shared machining center. Once one resource limits the flow for many orders, its sequence stops being a local efficiency choice. The bottleneck turns sequence into a business decision. The bottleneck decides the pace. Here's what a bottleneck really is. It's the resource that limits how much work the plant can get through over a given period. Whether that's a single machining center, a paint booth, a furnace, a test station, or even an inspection step, only a handful of people are qualified to do. Where it sits in the flow matters more than what you call it. Think about the pump factory again. Several orders move through cutting, preparation, and assembly at different speeds but if most of them have to pass through one machining center, that center sets the pace for everything else. No amount of upstream hustle can get finished parts out faster than that one resource can process them. So here's where the planning question shifts entirely. Instead of asking whether every machine stays busy, you should ask whether the constraint is spending its time on the work that best protects customer commitments and overall plant flow. A non-bottle neck can sit idle for a while without hurting total output but the bottle neck can't lose an hour without the plant losing an hour of potential flow. And here's where local efficiency can mislead you. A supervisor might keep an upstream machine running because an idle machine feels wrong. The operator has work, the machine runs, and the local utilization number looks great. But those parts may just end up in a growing queue in front of the constraint machining center so you end up with more work in progress, not more finished orders. Meanwhile, the bottle neck might be waiting because the next priority job doesn't have material, the program isn't ready, the right fixture is somewhere else, or someone picked a sequence that caused an avoidable change over. Those lost minutes hurt way more than an idle upstream resource because the constraint determines what the whole system can actually ship. So the schedule needs to protect bottle neck time, which means planning the work that comes before it carefully. The next job should have material, tooling, paperwork, quality requirements, and operator support ready before the current job finishes. And if there's a maintenance window, the plan needs to account for it. If a sequence can reduce cleaning or tool changes without breaking an urgent customer promise, the planner should be able to see that option clearly. This isn't about treating one machine is more important than people or quality. It's about respecting the resource that controls the plant's output. When the bottle neck runs the wrong work, waits for missing inputs or spends too much time on changeovers, the cost spreads through the whole order book. There's a simple way to think about this called drum buffer rope. The drum is the paste set by the constrained resource. In our case, the machining center sets the beat, telling the rest of the plant how fast work can realistically flow. The buffer protects that pace. It's a planned amount of ready work before the bottle neck, not just a pile of parts. The buffer gives the plant some protection when an upstream step runs late or a small disruption hits, but it needs control. Two little buffer risks starving the bottle neck, too much creates confusion and hides problems. The rope controls release upstream, stopping the plant from launching work just because material exists or an earlier machine has free time, so work enters the flow to support the bottle neck's plant sequence and capacity. In practical terms, the bottle neck tells upstream teams what to prepare and when. Upstream production doesn't decide the flow just by keeping itself busy. That can feel counterintuitive in a factory built around utilization targets where people are often pressured to keep every resource running. But if every department optimizes its own local workload, they can overwhelm the one place that controls finished output. A finite schedule makes this visible by starting with the constrained resource and asking which jobs must occupy its limited slots, then working outward to check that the work arriving before it supports that sequence and that downstream operations can absorb the output. ERP planning dates usually don't carry that live view of constrained flow. They can tell you when an order should need machining based on its due date and rooting and they can show load against the work centre, but those dates don't automatically protect the bottle neck from a missing kit and unnecessary setup or a queue full of lower priority work. A planner with deep shop flow knowledge often does this mentally. They know which jobs must stay close to the bottle neck, which ones can wait, and which upstream orders should not yet enter production. And that knowledge is part of the real scheduling process, even if the ERP only shows a long list of released orders. And that leads to a problem that seems helpful at first, releasing work early because when upstream release ignores the bottle neck, more activity can actually create more delay. Why releasing everything early creates more delay? When the plan feels uncertain, many factories respond in a very human way, they release work early, push it onto the floor and tell each department to keep machines busy. It feels safer than waiting. If the order starts early, surely it has a better chance of shipping on time, right? Sometimes that works for a simple order with spare capacity everywhere, but once workflows through a constrained area, early release can do the opposite. You haven't created more capacity, you've just moved more unfinished work into a system that already has a limit. Picture a set of orders released several days before the constrained machining operation can take them. Raw parts get cut, components get prepared, paper work travels with them, and then the jobs reach the area before the bottle neck and weight. That growing pile is work in progress, WIP. It represents labor, material, and time already committed, but it doesn't represent a finished order that can ship. And when too much WIP sits in front of the constraint, people lose sight of what should run next. The queue starts to become its own planning system. A supervisor walks past and sees an urgent job near the back, and operator starts the job closest to the machine because it's easy to pick up. A planner calls asking for a different order, and someone from sales shows up with another escalation. Before long, priority comes from whoever asks the loudest, who's physically present, or which job happens to sit on top of the pile. None of that means people are careless. They're reacting to a system where the release process has created more choices than the bottle neck can handle, and the visible queue hides the actual priority because every job looks late, urgent, or already started. Feedback slows down, too. If an order waits in a queue for two days, a problem discovered at the bottle neck takes two days to reach the upstream team, and by then, more material may have been cut, more labor spent, and more orders released behind it. So the factory keeps producing work that can't move forward while the real constraint stays overloaded. That's why high utilization at every resource can be a trap. A non-bottle neck machine can run at full speed all day, and still hurt total flow if it feeds work faster than the constraint can absorb it. The local team sees activity, but the plant sees more WIP, longer queues, more searching, and more expediting. Busy isn't the same as productive. This is one of the harder conversations in manufacturing because nobody likes to tell an operator or supervisor that a machine should sometimes wait, but an upstream resource waiting for the right release signal may protect the flow far better than producing another batch that joins a queue. The objective isn't idle time for its own sake. It's controlled flow. Work should arrive early enough to protect the bottleneck, but not so early that the shop floor becomes a warehouse of half finished orders. ERP due dates can make this harder because they often become dispatch lists. The system shows a list of orders with plant dates, and people assume every released order should move through production as soon as possible. But a due date tells you when an order needs completion. It doesn't always tell you when the first operation should physically start. Those are different decisions, and a release rule connects them by asking whether releasing a job now supports the planned flow through the constrained resource or just adds to the queue. The rule might consider the expected slot at the bottleneck, the time needed upstream, and a controlled buffer before that slot. The exact method differs by factory, but the principle stays simple. Release work based on the system's ability to absorb it. Without that rule, ERP dates become a long list of instructions that all means start now, and no shop floor can treat every order as first priority, so the result is usually a mix of manual sorting, hidden local rules, and avoidable noise. There's another dependency sitting inside this problem. A job might reach the right point in the flow at the right time, but still lack what it needs to run, and material readiness adds another layer to the scheduling decision. Material availability is necessary, not enough. Let's start here because ERP genuinely earns its place in this part of the problem. When demand shows up, material requirements planning breaks a finished product into every purchased part. Raw material and subassembly it needs. It checks stock, nets demand against supply, and creates purchase or production proposals early enough to respect the planned lead time. That's difficult work, and it matters more than most people realize. Take a pump assembly. The ERP tells planning that the housing blank seal kit bearings, fasteners, and impeller all need to exist before final assembly can finish. It traces those requirements through several levels of the bill of material, so a missing bought-in component doesn't stay hidden until someone reaches the assembly bench, but here's the catch that trips up almost every plant. In stock, doesn't mean ready to run. Picture a machining order where the raw material record shows plenty of quantity in the warehouse. The planner sees green status and assumes the job can take its plan slot. Then production checks the actual material and finds part of the stock under quality hold. Another part reserved for a different customer allocation, and the remaining quantity sitting in a batch, the job can't legally use. The quantity exists on paper. The usable material doesn't exist in reality, and this happens for completely sensible reasons. Quality hold stop suspect material from moving into production, batch rules protect traceability, some material simply expire, especially chemicals, adhesives, coatings, or items with controlled storage conditions. A substitute might look equivalent in a planning record, but still needs engineering or quality approval before it can enter a specific product. None of those rules are administrative noise. They protect the product, the customer, and sometimes the operator running the machine. Partial kits create a different kind of headache, say a job needs 10 components and 9 are available. The missing item might cost a few euros, but without it the order can't complete. If production starts anyway, the plant burns machine time and labour, then leaves semi finished work waiting for that final part. That choice can make sense in a few specific cases, but it needs to be deliberate, because partial completion uses capacity that another fully ready order could have used to ship on time. The harder situation appears when a material delivery and a capacity slot collide on the same day. The ERP shows a supplier delivery due Tuesday morning and a machining operation plan for Tuesday afternoon. On paper that fits perfectly. In practice, receiving needs time to unload the material, check quantity, post the receipt, and maybe complete incoming inspection. If the material arrives late, or inspection flags an issue, that machining slot goes empty. When the slot belongs to a heavily loaded resource, recovering that lost time later in the week often isn't possible. This is exactly why material planning and finite scheduling need to talk to each other. Material availability determines which jobs can occupy a real production slot and limited slots change how much value an on-time material delivery actually creates. A component arriving Wednesday might still support the customer promise if the required machine has space Thursday. The same component arriving Wednesday causes a late order if the only qualified machine has no free slot until the following week. Material date and capacity date have to meet inside the same plan. And material alone still doesn't define readiness. The operation might need a specific fixture that's tied up elsewhere, cutting tools might lack enough remaining life. A qualified operator might only work a certain shift. Some products need a quality technician available for first off approval before the machine can keep running, planning each condition in a separate system produces a familiar result. Every team reports its own part, looks fine, while the jobs still can't start. A workable schedule brings those conditions together at the moment of execution. It asks, is the approved material available? Is the machine eligible and free? Are the tools and fixture ready? And can the required people support the job in that time window? That's a much stricter question than whether the inventory balance looks positive. ERP remains the source for most of this supply information. It holds the bill of material, the inventory position, supply of commitments, and the purchase transaction trail. But a constraint-based planning process needs usable material status, not just a quantity field, and it needs to test that status against real resource time. Once you add those checks, another form of dependency enters the schedule. A job doesn't only need the right inputs, it also needs to follow the required production path with one operation handing work to the next. Routing logic does not create a feasible schedule. A routing describes the planned path in order should take through production. It tells the system that this component moves from cutting to machining, then inspection, then assembly. For planning and costing, that structure matters a lot. But here's the distinction people miss. A routing describes a path. It doesn't reserve the road. Each operation usually has a predecessor and a successor. Machining can't start until cutting produces the required part, assembly can't begin until the machined components pass inspection. That gives the order a logical flow, and ERP can calculate dates that respect that flow. Still, factories rarely move whole orders as one solid block. A transfer batch might let the first 50 pieces from a larger lot move to the next operation before the rest of the lot finishes. That shortens lead time in many cases. In another process, the full batch must finish and pass a check before anything moves downstream. Overlapped rules handle the same question differently. One operation may start after a defined percentage of the prior operation completes or only after a formal release. Those rules shape the timing of an order and they can be perfectly reasonable in an ERP routing. The issue appears when those calculated operation dates reach shared resources. Take an order where cutting finishes at 10 in the morning and the routing permits machining to begin at 10 because the transfer batch is ready. The ERP respects the predecessor link. It followed the defined logic. Yet, the machining resource might already run another order until late afternoon. The routing told you when the job becomes eligible to run. It hasn't proven the job can actually run then. Duration adds another layer of uncertainty. Many routing's use fixed and variable time. Fixed time might cover setup, loading, preparation, or first piece approval. Variable time changes with the order quantity, so producing more units takes more machine time. That model gives planning a reasonable starting point. But actual duration can differ for legitimate reasons. One batch needs more tool changes. A part requires an extra measurement. Material condition changes cutting speed. A machine runs slower for a difficult geometry. Sometimes standard time is close enough. Sometimes it's only a useful average. A schedule that treats every duration as fixed. When production knows it varies, we'll always look far cleaner than the shift it's trying to control. Then there are routes that don't behave like a straight line. Rework can send a part back to an earlier step after inspection finds a problem. That loop consumes capacity again, but it might not appear until execution confirms the issue. Alternative operations add another choice. A component normally runs on one machine, while a second machine can process it under certain conditions, perhaps with a different tool, program, quality check, or longer duration. Outside processing creates another dependency. An order may leave the plant for coating heat treatment, calibration, or a specialist process, then return before the next internal operation can begin. The routing includes plant lead time for that step. But the schedule still needs to handle what happens when the outside service date changes, or when the return part misses the internal resource window everyone expected. That's why a routing needs more than dates to become a working production plan. It needs the rules that govern movement between operations, the time assumptions behind each operation, and the resource choices that remain legal for that job. Then it needs a scheduling process that tests all of those conditions against actual slots across the factory. ERP can calculate an order flow that makes sense on its own terms. It can say cutting precedes, machining, machining precedes inspection and inspection precedes assembly. That's useful. Yet several orders can all follow their correct routing logic and still collide at the same machine, tool, test station, or outside supplier window. Order flow answers, what comes before what? A feasible schedule answers a harder question. Where does it run? Exactly when, and what gives way if two orders need the same slot? Keep that distinction in mind because the plan faces one more problem. Even if all the routing logic and resource rules are correct when the schedule is created, a real factory changes while the work is underway. The factory does not follow the plan. By 9.15, that schedule that looked solid at 8 in the morning is already wrong, and that's not a planning failure. Production deals with physical work and physical work changes constantly. Take a typical morning. A machine throws an alarm that needs maintenance, the one operator qualified for a control process calls and sick, quality rejects a batch creating scrap and forcing a replacement order into the flow, and then sales calls with an urgent request because a customer's line just stopped. Each one of those events changes more than just that single order. Here's what unplanned downtime really means. If a machine stops for 30 minutes, the first question isn't just when maintenance restarts it, you also need to know which operation was running, how much good quantity you have, whether material is still set up, whether the tool is damaged, and which later jobs just lost their planned time. The schedule needs facts, not guesses. Now this is where the MES and machine data enter the picture. The MES reports whether an operation started, paused, completed, or only produced part of its planned quantity. Machine signals give you a stop, an alarm state, a cycle count, or a change in runtime condition. But here's the catch. Raw signals don't automatically justify a schedule change. A machine alarm might clear in two minutes, a status feed might arrive late, or an operator records a temporary stop before a supervisor confirms the cause. If every incoming signal triggers a full reschedule, the plan becomes noise. People stop trusting it, because the next instruction changes before they can act on the previous one. So you need three separate stages to handle this properly. The process starts with a signal. An alarm, a delayed material receipt, a quality hold, or a direct message from the shop floor. It tells you something may need attention. Then the confirmed event arrives. Someone, or a trusted system rule, determines that the machine will be down for the rest of the shift, the material can't be released, or the operator absence changes available skill coverage. Now the event has enough meaning to affect planning. Only at that point does it make sense to decide whether the schedule actually changes. That step sounds obvious, but it gets skipped all the time. A disruption happens and someone moves several orders, and the factory spends the rest of the day chasing a plan that changed for no clear reason. A controlled process asks what the confirmed event effects, which commitments face risk, and whether moving work actually improves the outcome. And sometimes the right decision is no change at all. If the delay fits inside a protected buffer, leave the sequence alone. If a machine returns shortly, and the next job is ready, changing the schedule creates more disruption than the stop itself, people on the floor need stable instructions, especially when execution is close. But other events do justify a change. A confirmed machine outage, that removes the resource for the shift, scrap that means an order no longer has enough good quantity, or an urgent customer request with a commercial reason strong enough to displace planned work. Even then you need to think through the consequences, which order moves, which delivery promise now faces risk. Does the new sequence introduce extra setup or quality work? Is the material ready? Can the affected team actually act on the new instruction? A schedule change without those answers is just a new version of the same wish list. Static plans lose relevance quickly. They describe the factory as it existed at calculation time, while execution data describes the factory as it is right now. Good re-planning connects those two views without treating every small variation as a reason to rebuild the entire day. That requires discipline, thresholds, ownership, and a shared understanding of which events demand action, otherwise the loudest message wins, and the schedule becomes a record of interruptions rather than a guide for production, which is exactly why experienced planners keep local tools close by. They need somewhere to combine the ERP plan with the calls, events, and practical facts that arrive after the plan meets the shop floor. And that explains why Excel survives. Why Excel survives on the shop floor? This is where Excel shows up. It rolls their eyes, but the planner just gets on with it because they have to get work through the plant by Friday. The planner opens the ERP order list and keeps a spreadsheet beside it, taking a call from production about a machine that can't run a certain part today, reading a note about a tool still at maintenance and remembering that one operator can handle a difficult setup on the late shift while another can't? None of that fits neatly into a standard order date, so the spreadsheet becomes the working schedule. Sometimes it's a detailed file with tabs, color codes, filters, and formulas, only one person fully understands. Other times, it's simpler. A printed list, handwritten notes, a whiteboard near the production office, and the format changes, but the reason rarely does, the planner needs to connect facts that live in different places. ERP knows the order, routing, requested date, and material record. The MES may know current operation status, maintenance, knows plan work on the machine, production knows which setup causes trouble, quality knows a customer specific inspection is due. The planner pulls those fragments together into an instruction people can use. That manual board solves a context problem, it puts an order beside the machine that can run it the job before it, the person who supports it, and the practical condition that changes the sequence. An ERP screen may contain all the raw data, but it rarely brings those relationships together in a way that lets someone decide the next job under pressure. So I'd be careful when people call Excel the problem. It survives because it lets a planner shape a local model around the factory they know, adding a column for a constraint nobody modeled, moving an order in seconds, leaving a note that says, "Wait for first article approval" or "Run after the current batch if the tool returns." It's flexible because it doesn't insist the real world fit a rigid transaction form. Apparently Excel remains one of the most successful planning platforms Microsoft never intended to build, but flexibility has a cost. A local spreadsheet can carry business critical decisions without clear ownership, access control, version history, or a reliable trail of why someone moved an order. Two planners may work from different copies, a supervisor follows an old printout, "Someone changes a formula or overrides a date and nobody sees the effect until a customer order slips." The issue isn't that spreadsheets are bad, it's that the schedule can become private. If the person who maintains the file takes a holiday, leaves the company, or works a different shift, others inherit a plan without the reasoning behind it. They see a sequence of jobs, but they don't know which choices came from hard limits and which came from a personal preference or a phone call from sales. That creates a person dependent scheduling process. You might have an excellent planner who keeps the plant moving through experience, memory, and calm judgment, doing real engineering work, even if the tools make it look informal. Replacing their spreadsheet with a system that ignores their knowledge won't help. It just pushes real decisions back into messages, calls, and side conversations. A better approach captures the rules they use repeatedly while leaving room for them to judge the exceptions that no model can predict clearly. Ask the planner why a job moved, what must be true before that machine can run the order which changes over as they avoid, which customer dates can't move, and which resource causes the most trouble when its plan changes. Those answers describe the real scheduling logic far better than a generic template ever will. Some of that logic belongs in master data, some infinite scheduling rules, and some should remain a planner decision because the factory occasionally faces choices that need commercial judgment or direct discussion with operations. The aim isn't to eliminate the planner's board, it's to stop the board from becoming the only place where the factory's real constraints exist. And once you see that, the missing capability needs a clearer definition. What an optimal schedule actually means, people use the word optimal pretty casually when they talk about production planning, it sounds like there's one perfect schedule hidden somewhere in the system, just waiting for the right software to dig it out, but here's the truth. They usually isn't. What counts as optimal depends entirely on what the business is trying to improve, which rules it absolutely won't bend, and what trade-offs it's willing to make when those goals pull in different directions. If you haven't defined that part, optimal just means someone likes the answer. So let's start with something more concrete, a schedule that can actually run, that means every planned job respects the conditions the plant has agreed are non-negotiable. The job has a legal resource, the timing lines up, the order follows its required process path, and the necessary inputs are ready when the operation needs them. No resource gets more work than it can handle in the time assigned, that's feasibility right there, but a feasible schedule can still be a terrible business decision. You can build a plan that follows every physical rule perfectly yet delivers an urgent customer order late. Or you can build one that protects every customer date but forces constant setup changes and leaves too much work sitting idle between operations. Both plans will run, but neither one automatically serves the business. So once the schedule clears that feasibility test, you need a clear objective, sometimes the main goal is due date performance. The factory needs to protect a short list of customer commitments where a late shipment creates a real commercial problem. In another period, the goal might shift to throughput where moving as much finished work as possible through a constrained area determines what the plant can even ship. Here's where it gets tricky. Those goals can point in completely different directions. Think about an order that's due soon but needs a difficult change over at a busy resource. Running it next might protect the customer promise but it could also break a productive campaign, burn extra setup time and push several other orders later. Neither choice is automatically wrong if the business hasn't said which priority wins. The planner needs to see the real cost of each option if the urgent order goes first, which orders move, how much setup time gets added, and what happens to the work already queued. If the campaign continues instead, which customer date faces risk and does the business actually accept that risk, that's the heart of planning, not just sorting a list by date. Setup reduction matters because every avoidable change steals time from production. Lower work in progress matters because large queues hide priority and inflate lead time. Cost matters when overtime, subcontracting, premium freight, or a costly alternative resource enters the picture. And stability matters too, a schedule that reshuffles every hour might find a slightly better answer on paper but it creates a worst day for operators, supervisors, material handlers and quality teams. People need enough confidence in the near term plan to prepare work, stage material, and finish the job without chasing a new instruction halfway through the shift. So an optimal schedule often includes a preference for fewer unnecessary changes. Not because the plan should ignore disruption but because change itself has a real cost. The system should know when a new plan improves the result enough to justify that cost. This brings us back to the planner's private spreadsheet, a good planner already carries an objective in their head. They know customer X needs protection, they know a long run of similar parts saves time, and they know which orders are safe to move versus which ones will trigger a phone call before lunch. But if those priorities stay unspoken, the schedule can't explain itself. Two planners can look at the same order list and make completely different calls because they value different outcomes. One might protect customer dates at almost any cost while another might preserve the production sequence unless a customer commitment faces immediate risk. Both might have sound reasons but the business needs to decide which rule actually applies. That means constraints and priorities need clear names. A hard constraint means the schedule cannot break it. A machine may not run a certain material, a qualified person needs to approve an operation or a customer delivery is locked because of a contract or a shutdown on their end. A preference is different. Grouping similar work to save setup time, keeping the plan stable to reduce confusion or choosing the lower cost route to protect margin, these all matter, but the business can override them when something more urgent comes up. Once those rules sit openly in the planning process, people can challenge them. They can ask whether a customer date is truly fixed, whether a setup rule still applies or whether an assumed priority has actually changed, that's far better than letting hidden habits decide which order wins. So optimal doesn't mean perfect. It means the best feasible schedule against goals the business has actually stated with the reasons visible when one goal gives way to another. And before any system can start hunting for the best schedule, it needs to answer a simpler question first. Can this plan physically run at all? Finite scheduling in plain terms. Finite scheduling starts with one simple rule. Each resource only has the time it can actually provide. That sounds obvious, but it completely changes how planning works. Instead of placing every operation on the date it would ideally need, the schedule checks the real time slots available on the resources required to do the work. Take an operation that needs four hours on a machining center. In a finite schedule those four hours occupy a real slot on that machine. And during that same period, no other job can claim it. The schedule treats time as something that must be reserved, not assumed. And here's what people often miss. The machine might not be the only resource the job consumes. A job can need a specific machine, a fixture, a trained operator, and a work area for loading or inspection. The schedule checks those requirements against the same time window. If the machine is free, but the fixture is already committed elsewhere, that isn't a valid slot. If the operator with the required approval starts on the late shift, the job can't just begin on the early shift because the date looks right. The plan has to deal with real duration too. A job doesn't just appear to resource and disappear once the system creates an operation record. It occupies time for setup, processing, and whatever defined production time belongs in the planning rule. When it finishes, the resource becomes available for the next legal operation. That gives you a schedule people can actually test against the shift. A supervisor can ask, what should this machine run after the current job? The schedule should answer with an order that has an available slot, the required inputs, and the place in the sequence. It should not answer with three orders all planned for the same hour and leave the supervisor to pick one. When no legal slot exists, the finite schedule has to move something. It might push an operation later, pull work forward if an earlier slot opens up, or select another eligible resource where the rules allow it. What it can't do is quietly place two conflicting jobs on the same resource at the same time and call that a plan. And that limitation is actually useful. It forces the conflict into the open. If no slot exists before a customer date, the schedule shows that the date faces risk under the rules and capacity currently available. Someone can then decide whether to add overtime, use an approved alternative, change the delivery commitment, or accept the consequence. The system doesn't create capacity through optimistic dates. Now, there are different ways to place work in a finite schedule. Forward scheduling starts from a known point. The moment material becomes usable, the end of a prior operation, or the start of the planning horizon. The schedule moves forward through the routing and places each operation into the first suitable slots it can find. This works well when you want a practical answer to a direct question. Given what's ready now, when can we realistically finish this work? Backward scheduling starts from a due date and works in reverse. It asks when the final operation must end, then searches backward for legal resource time for each earlier operation. When capacity exists, the schedule protects the promise while avoiding work that starts earlier than needed. But backward scheduling gets honest in a finite model. If the necessary time no longer exists before the due date, the schedule can't just keep assigning earlier dates and hope the shop floor absorbs the overload, it identifies the conflict. Many factories end up using a hybrid approach. Near-term work may schedule forward from actual shop floor status because execution has already started and physical conditions control the next steps. Further out, the plan may work backward from delivery promises, then test those promises against available finite capacity, the exact split depends on the process, but the point stays the same. The schedule works from real boundaries, not dates alone. This doesn't mean the schedule becomes fixed forever. It can change when a confirmed production event changes the available options. But every change needs to fit within the same finite model of resources in time. So finite scheduling gives you a feasible plan, a working plan, not a dated wish list. Still, feasibility alone doesn't choose the best answer. Once several legal schedules exist, the harder question becomes which one the factory should actually pick. Constraint-based optimization. So you've got a few workable schedules on the table and the scheduling engine now has choices to make. Constraint-based optimization is how it searches through those choices while obeying the rules production cannot break. This search isn't about finding a need order list. It's searching for a schedule where each decision ripples into the next one because moving one job shifts machine time, setup time, material timing, and the finished dates of several other orders. Think about the decisions inside a normal planning day. You decide which job runs first, which eligible machine should process it, when it starts, and whether the order can split into smaller lots or must stay together until the operation finishes. Those are your decision variables. The parts of the schedule, the optimizer can change. In a simple factory, sequence might be the biggest choice. Put job A before job B and the next setup takes 10 minutes. Reverse that and it could take an hour or it might force a cleaning step. In a more flexible plan, resource choice matters too. One operation might run on either of two machines, but one runs faster while the other protects capacity for an order with no alternative. Start time matters for the same reason. An order could begin as soon as it's ready or it could wait. Starting it later protects a more urgent job, avoids a conflict or keeps related work together. Lots splitting adds another decision where the process allows it. A large production order can move through in smaller batches, which helps a downstream operation start earlier, but also creates more handling, more checks, and more complexity. The optimizer needs boundaries before it can make those choices. Some rules are hard constraints that the schedule must obey. A job may only run on approved resources. A heat cycle must finish before inspection begins. A tool cannot support two operations at once. A regulated product requires a qualified operator. If the schedule breaks one of those rules, it's not a clever solution. It's simply wrong. Other rules are preferences. You might prefer to keep jobs from the same family together. You might want to minimize late orders, avoid overtime, keep work moving, or avoid changing instructions already issued to the shop floor. Those preferences can conflict, so the model applies penalties. A late customer order might carry a high penalty. An extra setup might carry a smaller one. Moving a job inside the near term planning window might carry another because change creates work for people. The exact values aren't universal. They express how your plan chooses between imperfect options when capacity cannot satisfy every requested ones. This is what people mean by an objective function, though the phrase sounds more mysterious than it needs to. An objective function is the scoring rules the optimizer uses to compare legal schedules. It converts production priorities into a form the scheduling engine can evaluate. One schedule might protect more due dates, but create extra setups. Another might run cleaner campaigns, but delay and order the business considers urgent. The score helps the engine compare those outcomes using rules that planning and operations have agreed on. You don't need to pretend the score captures every human concern. It won't, but it does mean the same conditions lead to a repeatable planning process rather than a different answer, depending on who works that shift. And when someone asks why the schedule selected one order before another, the planner has a basis for the answer. This job protected a higher priority commitment, avoided an illegal resource conflict, or prevented a costly sequence change. Planner judgment still belongs in the process. A planner might know a customer can accept a one-day change, even though the system treats the due date as firm, they might know a maintenance team expects to release a machine earlier than planned, but hasn't confirmed it yet. They might see a commercial reason to make an exception, the model cannot infer on its own. The point isn't to hand control to a solver and walk away. The point is to give the planner a schedule build from explicit rules, then let them review and approve exceptions with the consequences visible. That also makes improvement possible. If planners override the same rule every week, the team can ask whether the rule needs adjustment, whether the master data is wrong, or whether the factory has a condition nobody has modeled. Let's return to that shared machining center and see how this approach handles competing orders when the schedule has to choose. Replanning the same factory scenario. Let's go back to the pump factory. This time, the machining center has a finite plan rather than a stack of overlapping dates. Three orders need that same resource. Order alpha has a customer due date tomorrow. Order bravo ships two days later. Order Charlie has more time, but it belongs to the same product family as alpha. So running those two together avoids a long tool and fixture change. There's also work already in progress. The machine is halfway through a job that cannot be interrupted without creating scrap risk and extra inspection. That job is locked. The scheduling engine doesn't treat it as a free slot just because a higher priority order appears in the order list. That's how a real schedule begins with what the factory can still change. Now add two more conditions. Material for alpha arrives this afternoon and incoming inspection has confirmed the delivery time. The machining center also has planned maintenance tomorrow morning. Maintenance needs the machine for a defined window so that time disappears from available capacity. A normal date calculation might still place all three jobs before their customer dates, but the finite model sees the actual problem. There are fewer available hours than the orders need and the sequence between those orders changes how many of those hours remain for machining. Suppose the current job belongs to Family A. Alpha also belongs to Family A. Bravo belongs to Family B. Moving from A to B needs a full fixture change, a tool swap and first piece approval. Charlie belongs to Family A as well. The schedule can use a sequence set up matrix. That sounds technical, but it's just a table of transition rules. It records how long it takes and what conditions apply when one product family follows another. Within Family A, the next set up might take a few minutes. From Family A to Family B, the plant needs a much longer change. From Family B back to Family A, it might need another one. The direction matters because a machine doesn't begin the day in a neutral state. It begins from the state left by the previous job. So the engine test possible sequences, it could run Alpha next, then Charlie, then Bravo. That protects Alpha's due date, groups the Family A work, and delays the expensive change over until later. But because maintenance removes capacity tomorrow morning, Bravo may no longer finish in time. It could run Alpha then Bravo then Charlie. Bravo receives more protection, but the plant pays for an extra change back into Family A. Charlie then moves later and the bottleneck loses time that could have gone into productive work. And there may be another option, Charlie might qualify for an alternative machine, not because every machine can run every part, but because engineering has approved a second routing under defined conditions. That alternative machine runs slower, and it may require a different fixture. Still, if the fixture and operator support are available, moving Charlie there could free the constraint machining center for Alpha and Bravo. That's a real trade off. The schedule doesn't pretend the alternative machine is identical. It includes the longer processing time, the eligible routing, and the fact that using that resource might affect other work, it compares that cost with the consequence of leaving Charlie on the main machining center. In one feasible answer, Alpha runs directly after the locked work. Charlie moves to the alternative machine. Bravo stays on the main machining center after the plant maintenance window with the family be setup performed once at a time that doesn't interrupt the earlier work. One order moves, but the move has a reason. The plan I can see that Charlie moved because it's due date carried less risk, it had an approved alternative route and keeping it on the bottleneck would force either a late Bravo order or an extra setup that consumed capacity the plant didn't have. That explanation matters as much as the proposed sequence. Without it, production sees another order changed by software. With it, the team sees a decision. Protect the orders without alternatives, use qualified flexibility where it exists and spend bottleneck time where it has the most effect. The planner may still reject the result. Perhaps the alternative machine has an issue nobody has confirmed in the system. Perhaps the customer behind Charlie cannot accept movement despite the recorded date. That's fine. The plan gives the planner a visible choice and visible consequences rather than hiding the conflict in a date list. But the quality of that choice depends entirely on the facts behind it. The schedule can only respect the machine, rooting, material and setup rules that the factory has described. The data model behind a schedule you can trust. Here's the problem with most production schedules. They only know the version of the factory you give them. If the model treats every order as just a date, every machine as a generic work center and every material as an available quantity that's exactly what it'll output just formatted nicely, that's where the data model starts, not where it ends. Think about what a planner actually pulls together before a tough call. You've got products with their own specs, processes that describe the operations needed and resources like machines, work areas, test equipment and people. Then, layer in orders, materials, tools, skills and calendars. All of that has to come together. None of those things mean much on their own. A product record tells you what you sell, a routing names and operation, but they don't connect the dots between what you have and what you need. A working schedule needs the relationships between those things. Which process applies to which product, which resource can actually perform that process and under what conditions. That's the product process resource relationship and it's the foundation everything else sits on, take a machine pump housing. The model should connect that housing to its specific machining operation, which connects to the machines approved for running it and each machine should then connect to the fixture, tool set, program inspection requirement and operator skill that the job actually needs. Now, the schedule has something useful to test against. It can ask whether machine one can technically run the part, handle the current material grade, whether the fixture is free and whether the right person is available during that slot. That's a lot more useful than assigning work to a generic machining center and hoping someone sorts it out when the shift starts. Now, here's where resource capability needs detail, but not fantasy. A machine might process several product families but only up to a certain size or tolerance. Another resource could handle the same operation but at a slower rate or with different quality rules. A tool might fit several machines while a specialist fixture only fits one. These are eligibility rules. They define what the schedule can actually choose, they also stop false flexibility from creeping in. A generic planning record might treat five machines as interchangeable just because they sit in the same department but production knows better. One has the right spindle speed and another has a program that still needs approval and a third is reserved for a product with no alternative route. If those differences stay outside the model, the scheduler creates choices that look sensible on paper until the shift actually starts. Sequence needs its own data too and this is where most models fall short. The system should describe setup families not just setup time as one fixed number. A job might follow another with almost no change if both use the same material, tool state or coating but a different transition could require cleaning, fixture replacement, warm up and a first piece check before it's ready to go. Batch size also changes the plan in ways the model needs to understand. Some work can move in small transfer batches while other work has to stay together for traceability, quality, heat treatment or just practical handling. A campaign might need a minimum run length before a costly cleanout makes financial sense but a customer priority can sometimes justify breaking that campaign. Those rules belong where the schedule can use them. Not just in someone's memory or on a sticky note taped to the planning board. Calendar's matter for the same reason. A calendar does more than show whether a plant works Monday through Friday. It can describe a machine's maintenance time, an operator groups shift pattern, a two rooms availability or a planned engineering trial that takes a resource out of normal production. That brings us to the real challenge, no single team owns all of this data. Engineering owns product and process definitions. Planning owns order priorities, planning horizons and dispatch rules, maintenance owns planned availability, production knows the practical capability limits and changing shop floor conditions. Quality controls approve rules that decide whether a material, route or resource remains eligible. That split is completely normal but the problem starts when nobody agrees who changes what when the change becomes effective and which system is the trusted source for that fact. A finite schedule doesn't need perfect data but every corner of the plant. It needs trusted data about the conditions that drive the decisions you're trying to improve. So start with the resource where conflicts keep appearing then model the products, processes, capabilities, setups and calendars that shape those conflicts. That sounds manageable and honestly it often is once you start with what's actually causing the pain but this is also where many APS projects run into trouble long before the optimizer even receives its first schedule. Why APS projects fail before the optimizer runs? Most APS projects don't fail because the optimizer can't solve the problem. They fail because the model gets a sketch of the factory that nobody would trust at 7am on a Monday morning. The software can only work with the data it receives. If rooting times describe an ideal process from three years ago generic work centers hide real differences between machines and calendars still show capacity during planned maintenance. The resulting schedule looks precise but sends people in the wrong direction. That creates a trust problem fast and trust is hard to rebuild once it's gone. A rooting might say an operation takes two hours but excludes setup, inspection, loading or normal delays everyone already knows about. The planning team might use one work center called machining for six machines even though only two can produce a certain product family and one of those two regularly runs a controlled customer order. The model sees six choices but productions sees two and sometimes only one when you factor in everything else. Outdated calendars cause the same damage and they're harder to spot. A planning calendar can show a full shift while the machine is scheduled for maintenance the operator group is short staffed or a tool room shutdown blocks preparation work. None of this means the master data team did a bad job. It usually means facts change in different parts of the business while the planning model receives updates too late or not at all. Then there's the knowledge that lives in the planners head and this is where most systems break down. Experience planners know which machine struggles with a certain alloy which tool tends to fail after a long batch and which root works only when a particular operator is present. They might also know that a nominally approved alternative machine creates so much rework that it should only be used in a true delivery emergency. If that knowledge never enters the model the APS system would suggest plans that break practical rules. After a few bad recommendations people stop opening it entirely and go back to the spreadsheet because the spreadsheet at least contains the notes that keep the factory moving. You don't solve that by asking planners to dump every thought they have into a system that approach never works. Some rules are stable enough to model while others depend on a temporary condition, commercial judgment or information that hasn't reached a formal system yet. The real job is identifying the repeatable rules that shape most decisions then giving the planner a clean way to handle exceptions when they come up. Data ownership often causes more trouble than the solver itself and here's why. You need clear answers. Who owns order status? Which system tells planning that an operation has started or completed? Who owns the machine calendar? And where does an approved routing change actually begin? If each system holds its own version the schedule calculates against stale or conflicting information every time. You need a clear answer for each planning fact where it's created, who can change it and which source the scheduling process trusts that doesn't require one giant database just agreed responsibility and integration that actually works end to end. Another common mistake comes from good intentions. The project team tries to capture every exception before anyone has scheduled a single day of work. They model rare quality rules every possible alternate route unusual custom instructions, temporary layouts and years of local habits. The scope expands, the model becomes difficult to test and maintain and meanwhile the daily conflict that started the project remains completely unsolved. So start where the pain is visible, pick a known bottleneck. Choose a product range with repeatable routing and a planning decision people make every single day. Model the actual machine eligibility usable capacity setup rules and the few material or tool conditions that determine whether work can actually run then compare the proposed schedule with the planner's real decision when the system gets the same answer ask why? When it gets a different answer, ask whether it missed a real constraint or exposed a rule nobody had questioned before. That's how confidence grows. Through repeated tests against production facts, not through a big launch announcement, an APS system doesn't need to replace ERP to do this work. ERP stays where demand orders, inventory and purchasing transactions belong. APS works beside it, taking the planning inputs it needs and returning a constraint aware production plan that people can review, debate and act on when Monday morning rolls around. ERP, MES and APS each have different jobs. Here's the problem. Once your planning model starts matching the factory you actually run, ownership becomes the real headache, not legal ownership. I mean, who owns each planning fact, who gets to change it and which system people trust when the numbers don't agree? ERP, MES and APS can cooperate, but trouble shows up the moment each system tries to act like the master schedule. Let's talk about what your ERP actually owns, the commercial and transactional side of production. It holds customer demand, sales orders, production orders, builds of material, inventory, purchase orders and the whole financial trail behind all of it. When the business promises a customer an order, that commitment needs a home and ERP is usually that home. It also drives the material plan. MRP turns demand into proposals for what to buy, what to produce and when supply should arrive linking an order to the components, subassemblies, suppliers and internal work required to fulfill it. That role doesn't disappear when you bring in finite scheduling. You still need ERP to answer questions like, what demand exists, what's been promised, which materials are planned and what transaction needs to post when work completes. MES owns a different kind of truth. It owns what happens during execution. When an operator starts an operation, records good quantity, reports scrap, pauses a job or completes a quality check, the MES captures that activity along with batch genealogy, serial traceability, electronic work instructions and quality events that can stop work from moving forward. That matters because a schedule starts as an intention, but production creates facts. The plan might expect a hundred parts to finish by noon, but the MES reports that 85 good parts finished, 10 need review and five became scrap. Those aren't planning opinions, they're execution facts and the schedule needs them if it's going to stay connected to the shop floor. APS, advance planning and scheduling, owns the decision layer between demand and execution. It pulls together order demand, material conditions, routing rules, available resources and current status, then builds a finite schedule that tests whether the work actually fits. Its job isn't to replace the ERP order or become the accounting record for stock movement. APS asks a different question. Given the conditions we have right now, what sequence gives the best workable plan? That includes scenario analysis where a planner tests the impact of a machine outage, a late supplier delivery, overtime on a constrained resource or a new urgent order, comparing options before releasing a decision rather than changing the live plan and hoping it works. The APS output should be a recommendation with reasons. It can show that moving a job protects a higher priority delivery, avoids an illegal setup sequence or uses an approved alternative resource while also showing the trade-off. Another order moves later, a setup increases or overtime becomes necessary. People can disagree with the choice, but they shouldn't have to guess what the choice does. Clear hand-offs matter more than the product names. ERP sends demand order details approved routing's material plans and customer commitments into the planning process. MES sends back actual progress, confirmed quantities, quality status and execution events. APS returns a feasible schedule with dispatch priorities or proposed changes for review, but only one place should hold schedule authority for any given decision. If ERP sends dates, APS sends a different sequence, MES exposes its own dispatch list and a planner maintains another order in Excel, the shop floor gets four versions of the plan. And nobody benefits from that. The supervisor will follow the source they trust most, which might be correct, but the architecture has already failed them. You need a clear rule. For detailed finite scheduling, APS becomes the planning authority. ERP stays the authority for customer orders, material transactions and formal commitments. MES stays the authority for what physically happened. The boundary needs to be plain enough that production knows where to ask when a priority changes. And the planner still owns the decision to release work. A scheduling engine can calculate options faster than any person can, but it can't carry accountability for a late customer call, a safety concern, an informal agreement with a supplier or a production risk people haven't confirmed yet. The planner reviews exceptions, approves changes that affect execution and decides when a recommendation should become a shop floor instruction. That isn't a weakness in the system. It's the operating model. Once those responsibilities are clear, the technical architecture becomes much easier to discuss. And that's where Microsoft comes in, not as a replacement for ERP, MES or APS, but as the data and integration layer that helps those systems exchange trusted facts. Microsoft architecture without the product pitch. So once you've decided which system owns which fact, Microsoft technology can help connect the planning loop without pretending it replaces the scheduling engine itself. The starting point is data moving both ways. ERP provides the planning inputs, production orders, due dates, approved rootings, bills of material, purchase status, customer commitments, MES sends back what production has confirmed. Operation start and finish times, good quantity, scrap, holds, machine status, work that no longer follows the original plan, that flow needs care. You don't want every system polling, every other system, copying records around, then arguing over which timestamp is right. In practical terms, the integration should move the facts each decision needs at the speed that decision requires. A long range capacity review may only need refreshed data at planned intervals, but a confirmed machine stoppage that threatens today's bottleneck plan may need to reach the scheduling process much sooner. Those are different integration patterns and treating them as one giant data feed usually creates more noise than help as you're fits naturally into this part of the architecture. It supports secure connections between ERP, MES, planning tools, machine data sources, and enterprise services, handling APIs, messages, events, transformation rules, and identity controls while keeping the shop floor separate from systems that don't need direct access to it. That separation matters because OT, operational technology, has different needs from enterprise IT. The machine network should not depend on a cloud planning request before it can continue running and production control stays close to production. As you can collect approved operational events and make them available to planning and analytics without turning the cloud into a new point of failure for the machine. Picture a confirmed event moving through the architecture. The MES records that a machining operation stopped. A maintenance or production rule confirms the resource won't return during the current shift. That event passes through the integration layer to the planning process where the scheduling engine can test the impact against current orders and available resources. At the same time, the event becomes part of the operational record for analysis, not as a vague alarm in a log file, but as an event tied to a machine and order, a planned slot, and the eventual planning decision. Microsoft, Fabric, becomes useful when you need a governed place to bring planning and execution data together for analysis. ERP data, MES events, maintenance records, and schedule versions often sit in separate systems for good reasons, but Fabric can bring approved copies into a shared analytical environment with common controls around access, lineage, and refresh. That doesn't mean Fabric becomes the scheduler. A scheduling engine needs to evaluate resource conflicts and generate planning choices. ERP needs to post transactions. MES needs to record execution. Fabric can help people analyze what happened across those systems, ask where the plan drifted from execution, and see whether the planning rules match the way the factory performs. Power BI then becomes the reporting layer for people who need to see schedule health without digging through order tables. A production manager may need to know where bottleneck load exceeds the time available. A customer service team may need a view of promise risk with a clear distinction between orders that remain feasible and orders that need a decision. A planner may need to compare the released schedule with what actually ran to review why the order changed. Those are decision views, not decoration. A colorful report that shows late orders after they ship doesn't improve the schedule. A useful view exposes pressure early enough for someone to decide whether to move work, approve overtime, protect the customer order, or revise a promise. The same applies to plan versus actual analysis. If an operation repeatedly takes longer than planned, the team should be able to trace that gap back to the root resource, product family, or shift condition involved. If the schedule changes every day, people should see whether confirmed disruptions cause those changes or whether the model keeps producing plans that operations can't follow. As a Microsoft MVP, I spend a lot of time looking at where Azure, Fabric, and Power BI fit in manufacturing architectures. They can connect the dots between IT and OT, provide real-time visibility where it helps, and support an architecture that actually scales. But they don't remove the need for scheduling logic. No integration platform decides which job should consume the last available hour on a bottleneck. And no analytics report knows whether a sequence rule is hard, flexible, or simply outdated. Those decisions depend on the planning model, the rules, the factory accepts, and the specialist scheduling capability used to test them. Microsoft can support the flow of trusted data and the decisions around it. The finite scheduling or APS layer still needs to solve the actual constraint problem. And even when the data reaches the right place, systems can still disagree about what a machine operation order status or resource qualification actually means, which is where a semantic layer helps give those facts a shared meaning. Context, digital twin and knowledge graph. Let's cut through the hype for a second. A shared meaning layer can take several forms and in manufacturing, two terms always come up. Digital twin and knowledge graph. They both help with planning, but they describe different parts of the same problem. Here's the practical view. A digital twin models an operational asset and its current state. For a machine that means whether it's running, stopped, under maintenance, available for planning or restricted to certain work, think of it as the current operational identity of that asset. It links the physical machine on the floor to a managed digital record that planning systems can use directly. That record can carry more than just a status signal. It can hold the machine's identity, its current setup family, plant maintenance windows, operating limits, and the approved data that tells other systems whether the machine can accept more work. Here's why that matters. Machine 12 is available is rarely enough information. You need to know available for which operation with which tool under what product restrictions for which shift and whether it's actually available, or just not reporting a fault at that moment. A digital twin gives you a way to model that current operational context without building a huge virtual factory. First, that idea has kept plenty of useful projects, stuck in PowerPoint for far too long. You can start with the assets that actually shape the planning decision. A knowledge graph handles a related but different job. It models relationships across things that live in separate systems, products, processes, resources, orders, material batches, tools, skills, and maintenance activities. The word graph can sound abstract, so keep it practical. It just means the model can record that a product requires an operation. The operation can run on specific machines. Each machine requires a tool for that operation, and a given operator needs an approved skill to run it. Those links are the planning context. Take a machining order that calls for a pump housing, following a routing. One routing step needs a milling operation that can run on two approved machines. But one machine needs a fixture currently assigned elsewhere, while the other enters a maintenance window later that day. A schedule that only sees works and a capacity misses that decision entirely. A schedule that sees those relationships can test real options. It can ask whether the operation is eligible on that machine at that time, check that the fixture is free, test operator skill coverage, and avoid maintenance collisions all at once. That's what context does. It turns separate facts into conditions that can be checked together. You don't need to call this a digital twin or a knowledge graph for it to work. Those labels aren't mandatory, and sometimes they create more debate than the planning problem deserves. The scheduling engine needs a trusted model of the same relationships, whether they sit in relational tables, a specialist APS data model, a graph database, or a mix. The format matters less than the clarity of the rules and the reliability of the data. Graph thinking becomes useful as relationships grow. A traditional table can store that an operation needs a resource, but factories often need to express more. A resource supports an operation only for certain product grades, with a certain fixture, after a qualification date, outside a maintenance period, and when the previous job leaves the machine in an allowed state. Those are connected conditions, not isolated fields. When you model them clearly, you reduce the need for planners to remember every exception. They can spend more time judging the situation and less time rebuilding the factory in their head before moving one order. This is where the architecture gets practical. The digital twin keeps operational asset state current. The relationship model explains how that asset connects to products, processes, orders, tools, and people. And the planning engine tests the proposed schedule against both current state and approved rules. No model removes uncertainty. A maintenance window can change, a tool can fail, or a person can spot a condition the system doesn't yet know. But clean context means the system can tell the difference between a resource that looks free and one that can legally and practically do the work. But that's a much stronger basis for any planning decision. It also changes what AI can safely do. AI has a role, but it shouldn't schedule by guessing. Let's cut through the AI hype for a second. AI can help planners, but it needs a defined job. Asking a generative AI tool to create the best production schedule from a pile of order data sounds modern, yet it skips the rules that make a schedule safe to run. A language model can explain information well. It can answer a planner's question in plain language like, why did order bravo move? Or it can retrieve the approved setup procedure for a product family, pull together the known conditions behind an exception, or help someone find the maintenance instruction linked to a resource. That's useful support. Picture a planner seeing an order moved outside its original promise window. Instead of opening five systems and chasing messages, they ask a copilot style assistant to show the confirmed events and constraints that affected that order. The assistant retrieves approved schedule changes, the related maintenance event, the root rules, and the current material status. It helps the planner understand the situation faster, but it should not invent the decision. There's another AI role that fits manufacturing much better. Prediction. A predictive model can estimate how long an operation is likely to take based on approved historical signals. It can estimate failure risk for a machine, quality risk for a product and process combination, or the chance that a supplier delivery will arrive later than planned. Those predictions can improve the inputs to planning. If a model estimates that an operation often needs more time under a certain material condition, the scheduling process can use that estimate as a planning duration with proper review and controls. If maintenance data suggests a higher risk of failure during a planned run, the planner can test scenarios before committing the bottleneck to that work, but prediction and scheduling remain different problems. A prediction says this job may take longer, but a scheduling engine asks, given that risk, which legal sequence best meets the goals we've set? That second question needs deterministic optimization, meaning the engine applies stated rules and chooses between options in a repeatable way. The schedule must obey the constraints you define. It needs to respect machine eligibility, approved routes, setup rules, current availability, material conditions, and whatever policy controls the plan, then it can score possible schedules against the business goals, like protecting a due date or reducing avoidable setup time. Generative AI doesn't replace that logic. It can describe the result, help a planner query the model, draft an explanation for a production meeting, and find the work instruction that applies when an exception occurs. But natural language fluency doesn't prove that a proposed sequence respects finite resource time or every production rule. A confident answer can still be wrong. In fact, trees tend to notice. So if you introduce co-pilot into this process, start with approved data and a narrow scope. The assistant needs permission or way access to the records it can retrieve. A planner may see customer commitments and schedule risk that an operator should not see. Maintenance may own notes that need controlled access. Quality records can carry their own restrictions. The assistant also needs clear action limits, reading and explaining our one level of risk. Drafting a proposed schedule change for review is another, releasing a change priority directly to the shop floor, changing a customer promise or bypassing a quality condition crosses into a decision that can affect delivery, safety and compliance. That boundary should stay explicit. A good design might let the assistant answer, which release jobs will be affected if this machine remains unavailable until the end of shift or let it prepare a scenario for the planner. It should not quietly rewrite dispatch instructions because it inferred that one order sounded urgent in an email. Humans need to approve schedule changes with operational impact. That doesn't mean planners must calculate every option by hand. The scheduling engine can test options, predictive models can improve assumptions and a generative assistant can bring the reasoning together in a form people can discuss. But the person accountable for production still decides whether that recommendation becomes a commitment, keep that distinction clear, a system can calculate a schedule that scores well against today's rules. But the plan still needs a schedule people can prepare for, understand and follow without receiving a new version every few hours. The cost of constant rescheduling, a schedule can respect capacity and still cause chaos if it changes too often. You've probably heard this called a nervous schedule and that's exactly how it feels on the floor. The plan keeps moving, priorities keep shifting and nobody is sure whether the instruction they got an hour ago still applies. That creates work that never shows up in any ERP transaction. A supervisor stops a team to redirect them, material handlers pull one kit back and bring another forward. Tooling gets ready for a setup only to find the job moved and customer service calls a supplier because an urgent order suddenly needs a missing component sooner. The machine pays for it too. Every late priority change breaks a sensible sequence. A job that would have followed a similar product now needs a clean-out, a tool change, a fresh inspection or a new fixture. The schedule may look more responsive because it moved the urgent job to the top but the plant loses time in the very change it created. You can't optimize only for today's urgent request. You need to include the cost of disturbing the work already prepared. Here's where freeze windows help. A freeze window is a period near the current time where the release plan stays stable unless a real exception justifies a change. It gives production enough certainty to stage material, prepare tools, assign people and execute the work without checking a new priority list every few minutes. The length depends on the process. A short cycle assembly line may only need a brief freeze window while a process with long setups, specialist tooling or complex material preparation needs more protection. The point isn't to make the schedule rigid. It's to stop low-quality changes from reaching the shop floor. Behind the freeze window sits a broader time fence, think of the schedule as having different levels of commitment as you move further into the future. Work already running is fixed, apart from safety or major production issues. Work plan for the immediate period may be released and protected by the freeze window. Further out, the plan remains flexible because customer demand, material dates, capacity and maintenance conditions can still change. That distinction gives planning room to react without constantly disrupting execution. Without time fences, every new sales order or forecast update can pull work forward and push other work back, turning the schedule into a live argument between demand and capacity. With time fences, the business can ask a more useful question. Does this new request justify breaking the firm plan or should replace it into the next flexible window? Not every event should trigger a full re-optimization either. A machine status signal might flicker for a few seconds and operator may pause a job to check a measurement or a supplier may send an early warning that still needs confirmation. If every signal causes the planning engine to rebuild the schedule, the system creates noise faster than people can review it. So planning needs event thresholds. For example, a short interruption may only require local recovery on the shop floor while a confirmed outage beyond an agreed duration may trigger a new scenario. A delayed material delivery matters only if it threatens a released job or consumes the buffer before a constrained resource. The threshold should reflect operational impact, not just the existence of an event. This also protects trust. People accept a schedule change more easily when they understand why it happened, who approved it and what it affects. Priority changed isn't enough. The explanation should state the reason in production terms. A confirmed machine outage removed available time, a material hold blocked the original job or a customer escalation received approval to enter the frozen period. The planner should approve changes that cross the agreed boundary that approval doesn't need to slow every normal adjustment. It creates a clear decision point when a change disrupts released work, affects a customer commitment or forces people to prepare a different job. It also creates a record that teams can review later, but to blame someone, but to learn whether the rules produce sensible decisions. A schedule earns trust when it changes for visible reasons and stays still when it should. Optimization needs rules people can live with because the best mathematical answer has little use if the people who run the factory stop believing it. Planning rules need shop floor ownership, a constrained based schedule only works when its rules come from the people who live with the consequences. Planning can't define the whole model alone. Planning sees demand and priorities while production sees the conditions that decide whether a job can actually run. Maintenance needs a voice because it knows when a machine is technically available when it is fragile and when a planned intervention can't move without creating a bigger risk. Quality needs a voice because an approved route, a batch release or an inspection rule can decide whether an order is allowed to proceed. Logistics knows whether the material, packaging, forklift capacity or staging space supports the planned sequence. Production brings the practical test. A routing may claim that two machines can perform the same work, but the supervisor knows one machine can only do it reliably with a certain fixture and operator combination. That isn't resistance to a new planning tool. It's a production rule that needs a proper place in the model. Planning still owns priorities and customer commitments, but it needs those other teams to define the physical boundaries around its choices. Otherwise, the system turns undocumented shop floor knowledge into avoidable exceptions. The first useful conversation separates hard rules from preferences. A hard rule means the schedule must never break it. A product may require a certified operator, a machine may need a safety check before a certain material runs, a quality hold may block release or a fixture may only exist once. The scheduling engine should treat those conditions as non-negotiable. Preferences work differently. You might prefer to group product families into a campaign because the change overtakes time. You might prefer to keep a certain customer or the stable once material has been staged or you might usually avoid overtime. Those are real concerns, but there may be circumstances where the business chooses to accept the cost. Then there are informal habits. Some deserve to become formal rules while others exist because a past problem created a workaround that nobody revisited. If the system copies every habit without question, it can preserve waste with impressive mathematical discipline, which isn't much of an improvement. This needs open testing, especially when rules conflict. Picture an urgent order arriving while the bottleneck runs a campaign that avoids a difficult clean-out. Sales wants the urgent job at the front, production wants to keep the campaign together and the bottleneck plan may show that inserting the order consumes enough time to put several other deliveries at risk. Nobody needs a solver lecture in that meeting. The discussion should sound like this. If we insert this order now, we lose this amount of usable bottleneck time to the changeover and these release jobs move. If we keep the campaign intact, the urgent order finishes later. If we approve overtime or an alternative route, the result changes again. That gives people a decision they can own. The scheduling engine can calculate the options, but it shouldn't hide the trade-off behind a score or a technical label. Terms like penalty weight, heuristic, or constrained violation may help the technical team build the model, but they don't help a shift leader decide whether to stage the next job. Explain recommendations and operations language. Say the order moved because the required tool is booked until the next shift, the job stayed in sequence because breaking the campaign creates a cleaning step and consumes the remaining protected time on the bottleneck or the plan selected another machine because that route is approved and keeps the constraint machine available for work with no alternative. People can challenge clear reasoning. That's healthy. They can't challenge a black box that tells them the schedule is optimized. In manufacturing, that word usually lasts right up until somebody asks which machine will actually run the order. This also needs governance, although that doesn't need to mean another committee meeting with slides nobody requested. An override should record who changed the plan, what rule or condition justified it and what impact the planner accepted. That protects the planner as much as the system. If an urgent order displaces several jobs, the decision becomes visible instead of looking like a scheduling error the next morning. Master data changes need similar discipline. When engineering adds an approved alternative resource, when maintenance changes a calendar or when quality changes an eligibility rule, the scheduling model needs to know when that change takes effect and who approved it. Otherwise, the schedule mixes yesterday's process rules with today's operating conditions. Review the overrides and recurring conflicts over time. If the same override keeps appearing, either the model missed a real rule or the plan keeps working around a constraint that deserves a different decision. So don't judge the scheduling process by how many people log into it, measure whether it helps people make better decisions when the factory can't satisfy every request. Measuring the right scheduling outcomes, if you want to know whether scheduling is actually improving, start with delivery performance. Don't stop there though, because due date adherence matters for a simple reason. It connects the plan to the promise you made a customer. But a schedule that hits dates by changing every few hours creates a different problem. Production might meet the current promise, but supervisors, operators, material handlers and tool room staff end up spending the whole day reacting to a moving target. So you need to measure schedule stability right alongside due date adherence. Ask how often release jobs move, how close to execution those moves happen, and whether the changes came from confirmed factory events or from planning noise. You don't need to treat every schedule change as bad,