 EN
 Deutsch
 Español
 Français
 Italiano
 Português
 Nederlands
 Polski
 Bahasa Indonesia
 Русский
 Українська
 العربية
 עברית
 हिन्दी
 日本語
 한국어
2026-07-25 · Season 2
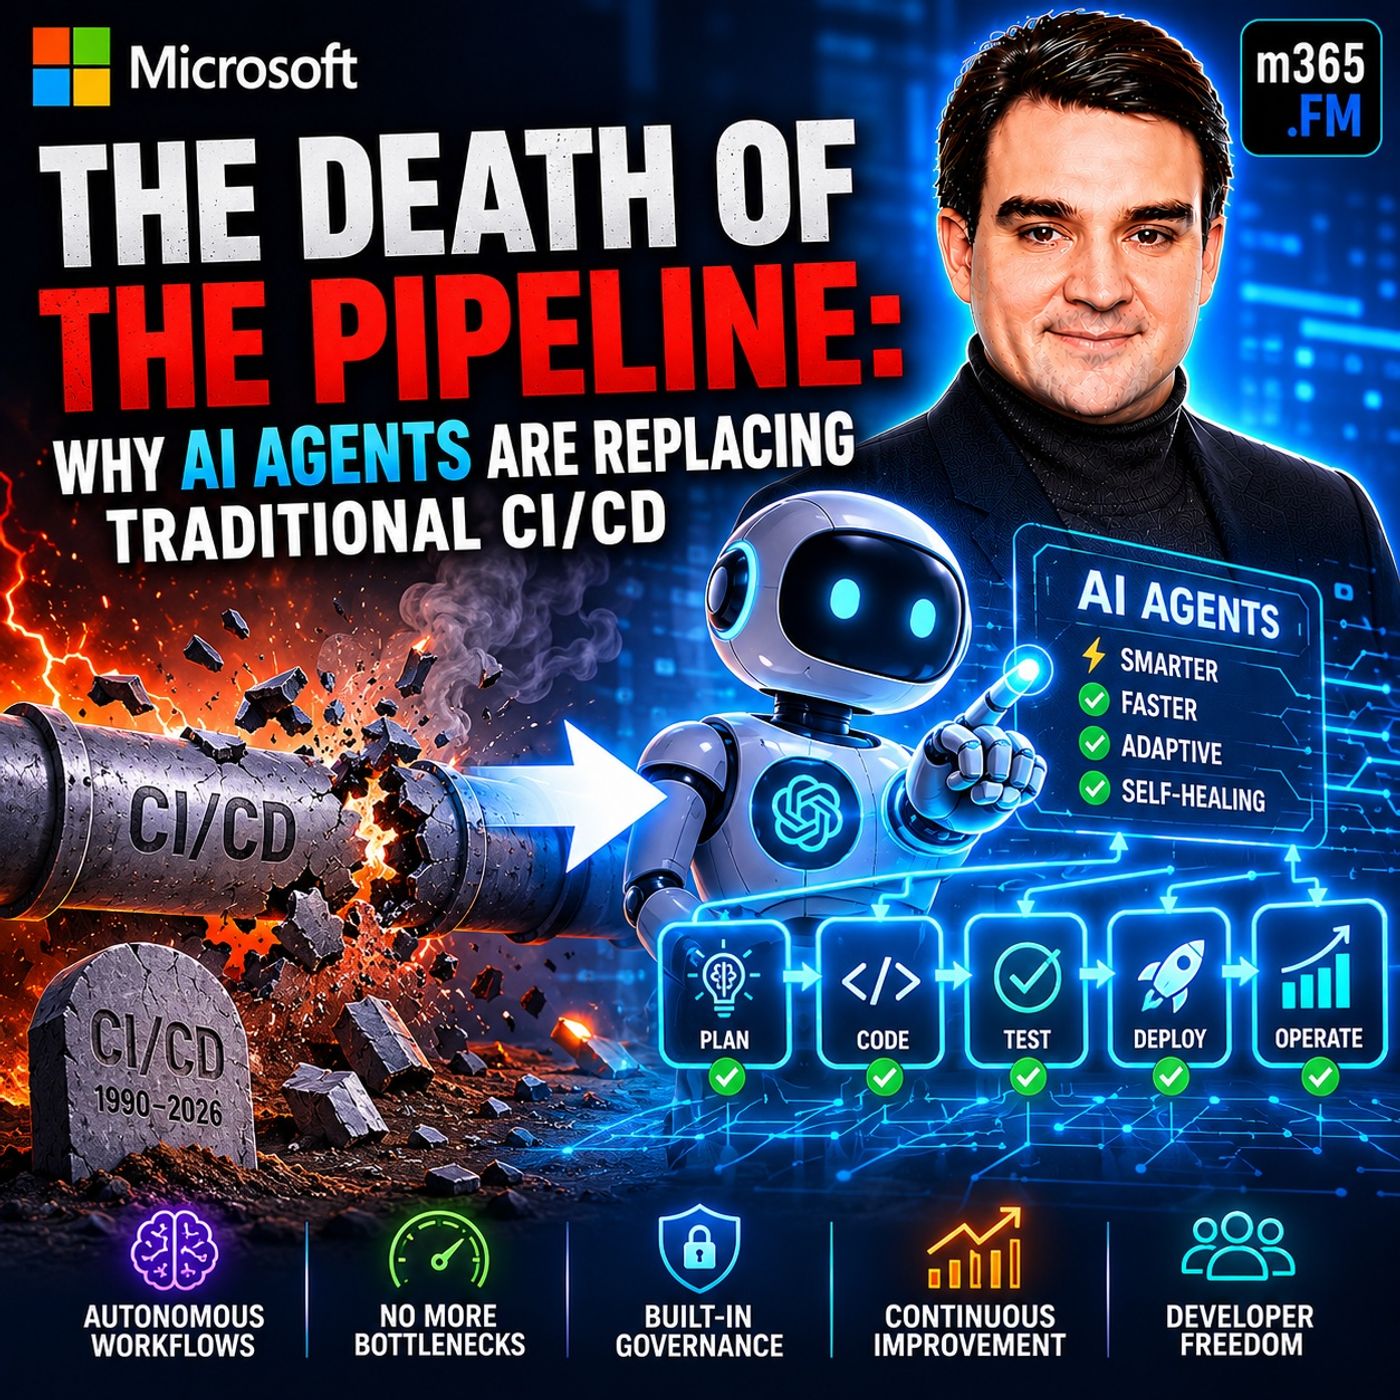
The Death of the Pipeline: Why AI Agents are Replacing Traditional
Show notes
For more than two decades, CI/CD pipelines have been the backbone of modern software delivery. Developers commit code, automated builds run, tests execute, security scans complete, someone approves the deployment, and production is updated. This model transformed software engineering and enabled DevOps to become the industry standard. But the world has changed. Cloud-native applications, Kubernetes, AI, multi-cloud architectures, and thousands of daily deployments have pushed traditional pipelines beyond what they were designed to handle. The real bottleneck is no longer automation—it's the fact that automation still revolves around human decision-making and linear workflows. This episode explores a radical shift: replacing sequential CI/CD pipelines with intelligent, autonomous AI agents that reason, collaborate, and adapt in real time. We'll examine why traditional pipelines are reaching their limits, how agentic systems fundamentally change software delivery, and why governance—not autonomy—is becoming the defining architectural challenge of the next generation of DevOps. WHY THE TRADITIONAL PIPELINE IS BREAKING Traditional CI/CD pipelines were designed around a simple assumption: Humans make the important decisions. A developer commits code. The pipeline builds. Tests execute. Security scans run. Then someone reviews. Someone approves. Someone decides whether deployment should continue. Every approval introduces waiting. Every handoff introduces latency. Every manual decision becomes another bottleneck. This worked perfectly when organizations deployed once every few weeks. Today's cloud-native organizations deploy hundreds or even thousands of times every day. At that scale, human approval is no longer primarily a safety mechanism. It becomes the slowest component in the entire delivery system. The pipeline itself isn't broken. Its underlying operating model is. AUTOMATION ISN'T THE SAME AS INTELLIGENCE Many organizations tried solving pipeline bottlenecks through automation. They built scripts. They created runbooks. They automated approvals. Initially this improved delivery speed. Eventually another problem appeared. Scripts only work inside predefined conditions. Whenever infrastructure changes, scripts begin failing. New Kubernetes versions... Changed APIs... Different deployment strategies... Updated security requirements... Every infrastructure evolution requires maintaining automation itself. Traditional automation has no understanding of context. It executes procedures. It doesn't reason. Organizations eventually spend enormous effort maintaining automation instead of benefiting from it. The presentation argues that static automation reaches a ceiling because modern infrastructure changes faster than rule-based systems can keep up. AI AGENTS CHANGE THE MODEL An AI agent is fundamentally different from a script. Scripts execute instructions. Agents reason. Instead of simply matching predefined rules, an agent continuously:
- Observes system state
- Understands context
- Evaluates possible actions
- Chooses the safest strategy
- Learns from previous outcomes
Imagine a degraded service. A script simply restarts it. An AI agent first investigates. Is this really a service failure? Is memory leaking? Is traffic unusually high? Would a canary rollout be safer than a restart? Could restarting actually make the situation worse? Rather than following procedures, AI agents operate using policies and objectives. That distinction fundamentally changes software delivery because the system adapts instead of merely executing instructions. FROM PIPELINES TO AGENT FABRICS Perhaps the biggest concept introduced in this session is that the future isn't a faster pipeline—it isn't a pipeline at all. Traditional delivery is sequential. Commit. Build. Test. Deploy. Each stage waits for the previous one. Agentic systems replace this with an AI fabric. Multiple specialized agents operate simultaneously. One analyzes security. Another writes tests. Another validates performance. Another evaluates deployment strategy. Instead of waiting for sequential stages, agents continuously exchange information while reasoning together. Researchers increasingly describe this model as Continuous Agentic Continuous Deployment (CA/CD) where reasoning replaces stage gates. The result isn't simply faster deployment. It's an entirely different operating model built around collaboration rather than sequence. THE SUPERVISOR-WORKER ARCHITECTURE Production AI systems don't consist of one giant intelligent agent. Instead, they increasingly adopt the Supervisor-Worker architecture. A supervisor agent owns the business objective. Specialized worker agents focus on individual domains:
- Security
- Testing
- Performance
- Deployment
- Compliance
Workers analyze their specific area. The supervisor coordinates the work, combines expert recommendations, and makes the final decision. This architecture provides several advantages:
- Clear accountability
- Easier auditing
- Better scalability
- Independent specialization
- Easier maintenance
Rather than creating one enormous AI system responsible for everything, organizations compose smaller expert agents that collaborate through orchestration. Companies adopting this architecture are reporting significantly faster delivery cycles while maintaining stronger governance. AUTONOMY ISN'T THE GOAL One of the most important lessons throughout the presentation is that full autonomy is neither realistic nor desirable. Current AI agents still require frequent human correction. Rather than viewing this as failure, organizations should treat it as a natural safety mechanism. The goal becomes appropriate autonomy. Low-risk activities may execute completely automatically. Medium-risk actions require human confirmation. High-risk production deployments remain supervised. Authority expands gradually based on measured performance. Autonomy is earned—not assumed. Successful organizations build tiered governance where AI gains additional responsibility only after consistently demonstrating reliable decision quality. GOVERNANCE BECOMES ARCHITECTURE Traditional governance relied on documents and policies. Agentic systems require something much stronger. Governance becomes architecture. Instead of saying: "Agents should only deploy approved services." Organizations technically prevent any other deployment from happening. Every agent receives:
- Cryptographic identity
- Scoped permissions
- Short-lived credentials
- Policy validation
- Continuous authorization
- Complete audit logging
Every action is validated immediately before execution. Agents don't merely promise to follow policy. The architecture prevents them from violating it. This represents one of the largest architectural shifts introduced by autonomous software delivery- MULTI-AGENT COMMITTEES Some decisions are too complex for a single agent. The presentation introduces another emerging architectural pattern: The Multi-Agent Committee. Rather than relying on one AI model, multiple specialist agents independently evaluate the same decision. For example:
- Security Agent
- Performance Agent
- Code Review Agent
- Compliance Agent
Each produces an independent recommendation. The supervisor synthesizes their conclusions before approving deployment. This dramatically improves decision quality because multiple expert perspectives identify different classes of problems. When disagreement occurs, the system naturally escalates to a human instead of forcing artificial certainty. Collective reasoning becomes safer than relying on any individual model. Become a supporter of this podcast: https://www.spreaker.com/podcast/m365-fm-microsoft-365-azure-cloud-power-platform-ai--6704921/support.
Apple Podcasts · Spotify · YouTube · Deezer
Host: Mirko Peters
Related articles
Transcript
Read the full transcript
You think your CICD pipeline is the peak of automation. In reality, it's the single biggest bottleneck in your system. It was designed for human speed. Here is the thing most organizations miss. When they adopt AI and DevOps, they treat it like a faster keyboard. GitHub co-pilot speeds up the coding. Intelligent monitoring reduces the alert noise. But the real structural shift isn't about velocity at all. It's about the model. Most DevOps leaders are still optimizing the wrong thing. They're asking how to make the pipeline faster. When they should be asking why a pipeline is the right model at all. Over the next 100 minutes, we are going to diagnose why traditional pipelines are failing at scale. We will look at how autonomous agents are rewriting the rules of delivery and what your organization actually needs to do in the next 18 months to stay relevant. We aren't talking about incremental improvements. We are talking about a structural shift from linear processes to adaptive systems. This is for the architects and the decision makers who are tired of vendor hype. And want to understand the real architecture underneath the headlines. The pipeline was built for humans. The traditional CICD pipeline is a brilliant design for its time. But it assumes one fundamental thing. Humans own the critical decisions. Think about what that actually means in practice. A developer commits code and the pipeline builds it. Tests run, security scan happens, and then here's the bottleneck. A human reviews it, another human approves the deployment. If something goes wrong, another human decides whether to roll back. The pipeline is just a sequence of gates. Build, test, security, approval, deploy. Each gate introduces a handoff and every handoff introduces latency. This model worked when deployment frequency was measured in weeks. You would batch up changes and review them carefully before deploying on a Tuesday. That made sense when the cost of deployment was high and the cost of waiting was low. But that is not how modern systems work anymore. Today organizations that move fast are deploying hundreds of times per day. Netflix deploys thousands of times daily and striped handles thousands of deployments every single week. In that context, a human approval gate isn't a safety mechanism. It's a friction point. It is where speed goes to die. Every gate in the pipeline is a friction point. Every approval is a weight. Every manual step is a potential failure. This isn't because the humans are slow. It's because the system is designed around human decision making speed, which is fundamentally constrained by human attention. A human can review one pull request in 30 minutes. They can evaluate one deployment decision. They can make one judgment call. When you scale that across hundreds of teams and thousands of repositories, you get a system that is not just slow. It's brittle. Here is what happens at scale. The pipeline becomes a bottleneck, so organizations hire more reviewers. They add more approvals. They create change advisory boards, and each of those humans becomes a single point of failure. One reviewer is sick and the pipeline backs up. A security team member is in a meeting, and your production incident sits in a queue waiting for approval. The pipeline also optimizes for the wrong things. It is designed for predictability and auditability. It is designed to catch errors after they happen. And in a system moving at the speed of modern infrastructure, catching errors after they happen isn't good enough. You need to prevent them. You need context. You need reasoning. When a deployment fails, a traditional pipeline logs the error and rolls back. Then a human gets paged. They read the logs, figure out what went wrong, and make a decision about whether to redeploy or investigate further. That is hours of latency built into the recovery process. And here is the deeper issue. Modern infrastructure moves faster than humans can reason about it. A Kubernetes cluster with hundreds of services and multiple cloud providers creates networking that is constantly changing. A human cannot hold all that context in the head anymore. They cannot reason about whether it is safe to deploy when the system state is changing by the second. The pipeline was designed for humans. It made sense when humans were the fastest part of the system. It breaks down when the infrastructure is the fastest part. And humans are the bottleneck. That is where we are right now. Why linear automation hits a wall? Organizations did exactly what you'd expect. They automated the pipeline. They built the scripts. They wrote the runbooks. The logic was simple. If we automate the approval process, we solved the bottleneck. And for a while, it worked. You could take a manual approval that used to take 30 minutes and turn it into an automated check that took 30 seconds. You reduced the human toil. You increased how often you could deploy. But here's the problem. Scripts and rule-based automation are brittle. They work perfectly in the specific conditions they were designed for. They fail the moment those conditions change. Think about a runbook that restarts a service. The script checks if the service is down. If it is, it sends a restart command. It waits for the service to come back up, confirms it's healthy, and then it's done. For months, this works beautifully. The script saves hours of manual work and clearly delivers value, then your infrastructure evolves. You migrate that service to Kubernetes. The restart mechanism changes. The health check endpoint moves. The dependencies shift. And suddenly your runbook doesn't just fail. It fails silently. Or worse, it succeeds at the wrong thing. It restarts a service in a way that cascades to five other services. And now you have a partial outage that the automation actually created. Traditional automation has a fundamental limitation. It has no context. It doesn't understand why something failed. It just knows that the failure mode matches a pattern in a rule set. It doesn't know if the fix is safe in the current state of the system, and it has no idea what dependencies have changed since the script was written. It just executes. The result is a maintenance burden that becomes crushing. Every time your infrastructure changes, and in modern systems it's always changing, you have to update the scripts. You have to test them, deploy them, and monitor them just to make sure they still work. The correction rate for traditional automation is surprisingly high. Teams estimate they spend between 30 and 40% of their time just maintaining their automation. They're fixing broken scripts, updating runbooks, and patching rules that no longer apply. You've built a system that creates as much work as it saves. Rule-based systems can't handle exceptions because they're binary. Either the condition matches the rule or it doesn't. If you have a rule to restart a service when it's down, but the service is down because it's consuming excessive memory, the rule fires anyway. You've restarted a service that had a completely different problem, and you've masked the symptom without addressing the cause. So you add more rules. A rule for high memory, a rule for high CPU, a rule for slow response times. Each new rule requires a new review cycle, and each one adds complexity. Eventually you increase the chance that two rules will conflict. This is where most organizations are stuck right now. They've invested in automation scripts and rules. They have monitoring that triggers workflows, but the automation is too fragile to trust for high-stakes decisions. It's too rigid to adapt when conditions change, and it's too expensive to maintain as the system evolves. The cost of maintaining automation grows faster than the benefited delivers. What started as a productivity gain becomes a liability. You've created a system that's harder to change than the original manual process. You can't modify the infrastructure because the automation might break, and you can't optimize the system because every optimization requires updating the rules. But here's the thing, you need context to solve this. You need a system that understands not just what happened, but why it happened. It needs to know if the fix is appropriate for the current state, and if there are side effects you need to consider. That's not what scripts do. Scripts are procedures. They execute sequences of steps, and procedures are the wrong model for dealing with systems that are constantly changing. You need something different. You need reasoning. Enter the agent. A different kind of actor. An agent is fundamentally different from a script. It's not just better at the same task. It's doing something entirely different. A script executes. An agent reasons. In practice, that distinction changes everything. But when you run a script, you're saying, if this condition is true, do that action. The script checks the condition it's either true or false and the action runs. There's no judgment, no understanding, and no adaptation. An agent is a system that perceives context, reasons about options, decides on an action, and learns from the outcome. Those are four capabilities that a script simply doesn't have. Perception means the agent can read logs and understand the system state. It correlates signals from multiple sources to build a mental model of what's happening. It isn't just matching a pattern it's actually understanding. A script sees error code 503. An agent sees an error code in the payment service that correlates with a spike in database connection time. It sees a recent deployment to the user service that increased the load and it knows where currently in peak traffic hours. Reasoning means the agent can analyze that context and think through options. It asks what the possible causes are and which one is most likely. It weighs the side effects of different remediation strategies to find the safest approach given the current state. Decision making means the agent doesn't just follow a predetermined path. It evaluates the situation and chooses an action. Crucially, it can choose actions that weren't explicitly programmed into a rule set. It can reason about novel situations within defined boundaries. Learning means the agent gets better over time. It remembers past incidents and builds a model of what works. When it encounters a similar situation, it applies what it learned last time. If an action doesn't produce the expected result, it updates its understanding. Let's make this concrete. Imagine your service is degraded. A script sees the degradation, checks the rule set, and restarts the service because that's what the rule says to do. It's the rules that works, but sometimes it makes things worse. An agent in that same situation reasons differently. It sees the service is degraded and identifies a memory leak based on the trend line. It decides the safe action is a canary rollout rather than a full deployment because we're in peak traffic. It plans to restart one instance at a time, monitor the error rates and roll back if errors spike. The agent evaluated the state of the system, chose a strategy, and planned a safety mechanism. The script can't do any of that. And this is the shift. Agents operate under policy, not under procedure. A procedure is a fixed sequence of steps. Do this then that, then that procedures are brittle because the world changes. A policy is a constraint or a principle that says deployments must be rolled back if error rates exceed 5% within 5 minutes. It says all changes to payment processing require a security review. It says never restart all instances of a service simultaneously. Policies are flexible. They apply across different contexts. An agent can apply a policy in a situation that's never encountered before, while a script can only execute the specific procedure it was written for. This is where autonomy becomes scalable. You can't write a procedure for every situation and you can't anticipate every edge case. You certainly can't update every script every time your infrastructure changes. But you can write policies. You can give an agent a set of constraints and a set of tools. You tell it what you're trying to accomplish. The rules it must follow and the tools it can use. Then you let it figure out what to do. The agent will handle novel situations within those boundaries. It will adapt when conditions change and reason about complexity that would make a script choke. This is what moves us from automation that breaks when the world changes to systems that adapt to the world as it changes. That's the fundamental shift. The shift from pipeline to fabric. Everything we know about delivery is about to change. We've spent years trying to make the pipeline faster, trying to make automation smarter and trying to cut down on bottlenecks. But the real shift isn't about making the pipeline better. It's about getting rid of the pipeline entirely. Traditional CI/CD is linear by design. You commit, you build, you test, you deploy. It's one path and one sequence where work moves through stages. Make a factory line from 100 years ago. When one stage finishes, the next one starts. The agent-based model works differently. It isn't a pipeline. It's a fabric. In a fabric multiple agents work at the same time. They reason together, they coordinate. They share context in real time instead of waiting for a handoff. There is no waiting for the previous stage because there is no stage gate latency. Think about how this looks in practice. In a normal pipeline, a tool writes code and then that code sits there waiting for a human to look at it. Once it's approved, a test agent finally starts its run. It's slow, it's sequential. In a fabric, the code generation agent and the test agent work together. The second the generator writes a line, the test agent starts analyzing it. At the same time, a security agent looks for vulnerabilities while a performance agent checks for lag. A compliance agent verifies the rules while all of this happens at once. This isn't just a little bit faster. It's a different category of speed. You aren't just running the same steps quicker. You're removing the need for steps to happen one after another. Researchers call this CI/CD. This agent continues deployment. It moves us away from simple integration into what continues reasoning. The system doesn't wait for a green light. It resins and adapts every second. The fabric is also driven by events rather than schedules. A traditional pipeline waits for a trigger like a manual click or a timed webhook. Things happen on a calendar. But the fabric reacts to what is happening right now. A change occurs and the agents respond immediately. They don't wait for a human to notice. When a service starts to fail the monitoring system sends out an event, the triage agent sees it instantly and connects it to other signals to find the cause. Before you even know there's a problem the agent has already diagnosed it and started the fix. This is a departure from how we operate today. Right now when something breaks a human gets paged. That person has to wake up, gather context and figure out what's going on before they can even act. You're just stacking human delay on top of system delay. In a fabric the system has already made progress before you even get the alert. The results are massive. You get faster feedback and better decisions because the agents have the full picture. You have less busy work because routine choices happen automatically. Most importantly you have lower risk because the system sees everything. Not just one local corner. Look at what this does for your team. In a pipeline every stage is a silo. The test agent doesn't know what the security agent found and the deployment agent is blind to the infrastructure. You lose data at every single handoff. In a fabric information flows in every direction. Agents learn from each other. If the security agent finds a bug the test agent writes a new test to make sure it's gone. If the infrastructure agent sees the system is stressed the deployment agent automatically slows down the rollout. This is systems thinking. It's not a pile of tools. It's a coordinated system that thinks about the hold. The old pipeline is a process you have to follow. The fabric is a system that just operates. You set the goals and the rules and the system figures out the best way to get there. This distinction is the most important part of the conversation. If you're still trying to optimize your CI/CD process you're looking at the wrong problem. The question isn't how to make the pipeline faster. The question is why we still have a pipeline at all. The future isn't a faster sequence. It's a system that reasons, coordinates and adapts. The architecture. Supervisor worker pattern. We've looked at how agents differ from scripts and how we're moving toward fabrics. Now we need to look at the actual architecture that makes this work in production. The winning design isn't a messy web where every agent talks to everyone else. It isn't some chaotic negotiation where they all try to reach a consensus. It's actually much simpler. It's called the supervisor worker pattern. This is becoming the gold standard for how these systems are built. Here is how it works. You have one supervisor agent that handles the overall goal. It understands the intent, like, deploy this safely or fix this incident. The supervisor owns the outcome and knows what success looks like. Then you have specialized workers. You have a tester, a security expert, a deployment strategist and a performance analyst. Each one is a master of its specific domain. The supervisor takes the big goal and breaks it into small tasks for the workers. It coordinates the effort, brings the results together and makes the final call. The workers stay focused. A test agent doesn't decide when to deploy because that isn't its job. A security agent doesn't write the code. Each worker does one thing perfectly. This setup is much easier to manage than a flat mesh. You have a single point of decision. You know exactly where the high stakes thinking happens. If something goes wrong, you can look at the supervisor and ask why it made that choice. In a mesh where everyone talks to everyone, you can't see who is responsible. You don't know which agent influenced the outcome. But with the supervisor accountability is clear. The supervisor is in charge. The supervisor also enforces your policies. It can set a rule that no change happens without a security pass and a rollback plan. It becomes the gatekeeper. Before it acts, it checks with the security worker and the deployment agent to make sure everything is ready. The workers stay in their lanes. They have clear boundaries. A test agent can flag a failure, but it can't decide to ignore that failure and push to production anyway. Only the supervisor can make that call and the supervisor is bound by the rules you set. This separation is what makes the system reliable. Each worker is simple and easy to audit. You can test them one by one. If a worker starts making mistakes, you can fix just that one part without breaking the whole system. Companies are seeing 30 to 60% faster cycle times using this pattern. That isn't just because the tech is fast. That's because decisions happen instantly with better context. You aren't waiting for people to sign off or losing data between steps. The supervisor takes all that expert input and decides in seconds. This pattern also scales better than old school automation because it handles the weird stuff naturally. A script breaks when it hits something new. A supervisor worker system reasons through it. If the security worker sees something strange, the supervisor can escalate it to a human, get an answer, and learn for next time. You can also add new workers whenever you want. If you have a new compliance rule, you just add a compliance worker. The supervisor learns how to use it. If you find a new risk, you add a worker for that too. This is architecture built for change. It isn't static or brittle. It's adaptable. And it's what is winning in the real world right now. The autonomy ceiling. Why full autonomy is a myth. We need to stop here for a reality check. Everything we've covered so far sounds like the future has finally arrived. Agents that reason, systems that coordinate, parallel decisions. It feels like we're about to flip a switch and let the humans go home while the agents run the show. But in reality, that's not what's happening. Not even close. The current data on agentic systems shows something sobering. We are seeing a 40 to 73% correction rate. That means between 4 and 7 out of every 10 decisions an agent makes. Require a human to step in and fix it. Nearly half of what the agent decides to do has to be undone or corrected. But here's the problem. People see that as a failure. It's actually the opposite. It means the system is operating at the very edge of its capability. It's pushing into territory where it isn't fully reliable yet. And when it hits that edge, it escalates. It's saying, "I'm not confident enough to own this alone. I need a person." That's not a bug. That's the feature that makes autonomous systems safe. Most organizations have a fundamental misunderstanding of the goal. They think the point is full autonomy. Get the agents to make every decision. Remove the human entirely. That's the dream, right? Wrong. That's actually the nightmare. Full autonomy isn't the goal. Appropriate autonomy is the goal. Think about the distinction. A low risk change. Like updating documentation or refactoring internal code with zero customer impact. Can be fully autonomous. The agent reviews it. The agent is confident. The agent ships it. No human needed. That's appropriate autonomy. But a high risk change. Like a production deployment to a payment service. Requires a human. Even if the agent is confident. Even if every automated check passes. The risk is too high for the human to be out of the loop. It is appropriate to not be autonomous. This is tiered autonomy. Different decisions get different levels of oversight based on the risk. This is where it breaks for most companies. Organizations that try to force full autonomy usually fail. They give agents broad authority. Something goes wrong. A bad decision leads to a security breach or a compliance violation. They lose trust. They pull back. And then they restrict the agents more than they actually should. But the teams that implemented autonomy from the start are the ones that succeed. They are realistic about the correction rate. They build escalation paths. They measure what the agent does well and what it does poorly. They expand authority based on data. Not hope. Because in reality. We should be earned not granted. An agent that consistently makes good decisions in low-risk scenarios earns the right to handle medium-risk ones. But it doesn't get that right until it proves itself. You track the decision quality. You monitor the correction rate. If it performs well. You give it more authority. If it fails in a specific domain, you restrict it. That's how trust is built. Not by assuming the agent is perfect. But by measuring performance and expanding authority based on evidence. In practice, this looks like tiered gates. If a code change only touches test files. The agent merges it. If it touches business logic. The agent flags issues, but a human approves the merge. If it's a deployment to production. The agent proposes the strategy, but a human signs off. You aren't removing humans from the loop. You're removing humans from the routine decisions. And keeping them in the decisions that matter. Most organizations will operate in this tiered model for a long time. Maybe five years? Maybe ten. The question isn't whether full autonomy is possible. The question is whether it's desirable. The moment you give an agent the authority to make a decision. You are accepting the risk that it makes a bad one. And some decisions are just two high stakes for a system with a 70% correction rate. So you don't do it. You use the agent for what it's good at. You keep humans for what matters most. That's maturity. That's the realistic future. Governance as architecture, not policy. This is where most organizations go wrong with governance. It's a fundamental misunderstanding of how systems work. When companies start governing agents. They do what they've always done. They write a policy document. Agents must not deploy without approval. Agents must log all decisions. These are sensible rules. They're written in plain language. Legal and security teams review them. Everyone agrees they're good policies. And then they fail. The reason is simple. Policies are static. Systems are dynamic. The world changes and your infrastructure evolves. A policy document from six months ago no longer maps to how the system actually works. You end up with rules that are either too restrictive. Or too loose because the policy didn't anticipate a new scenario. Worse. Policies rely on compliance. You're trusting that the agent follows the rules. You're hoping it reads the document and acts accordingly. That's not security. That's faith-based governance. The new approach flips the model. Instead of writing rules about how agents should behave. You build constraints so agents can't violate the rules. This is governance as architecture. It's the difference between a sign that says don't enter and a locked door. Here's how it works. Instead of a general deploy permission. You grant specific scoped permissions and agent gets permission to deploy one specific service to staging, but only if security checks pass and an on-call engineer approves it. Notice what happened there. You didn't write a rule. You embedded the rule into the permission itself. The agent doesn't have the ability to deploy to production. The system literally won't let it. Not because of a policy, but because the permission doesn't exist. This requires a different architecture. Agents need scoped identities. Each agent has cryptographic credentials that specify exactly what it can do. It's zero trust for agents. You don't trust the agent based on its role or its intentions. You trust it only within the explicit boundaries of its credentials. Every action goes through validation. The agent wants to deploy. The system checks the permission. It checks the constraints. It checks the current state of the environment. Only if everything validates, does the action proceed. And here's the critical part. This happens in real time. The constraint isn't checked once at the start. It's validated at the moment of execution. Because the state of the system might change between the decision and the action. This approach is more secure because you aren't relying on the agent to follow rules. You're preventing it from breaking them. It's more auditable because every action is logged. And it's more scalable because you don't have to write new policies every time the system changes. It's a permission scope and the agent immediately operates within the new limits. Organizations using this model see 52% fewer security incidents. Not because the agent's got smarter, but because the system prevents unsafe actions before they happen. It's the difference between hoping an agent does the right thing. And making it impossible for it to do the wrong thing. That's architecture. That's real governance. The multi agent committee. There is a new pattern emerging. It is different from the supervisor worker model we just looked at. And it is powerful for decisions where the stakes are highest. Sometimes a single agent's reasoning isn't enough. Not because the agent isn't smart, but because the decision requires multiple kinds of expertise. A code review needs style validation. It needs security analysis. It needs performance evaluation. It needs business logic verification. No single agent can be an expert at all of those simultaneously. That is where the committee pattern comes in. Imagine a significant code change lands. Instead of one agent reviewing it, three agents evaluated in parallel. A code review agent checks the implementation. It looks for bugs and edge cases. A security agent analyzes the change. It looks for vulnerabilities or data exposure. A performance agent models the impact. It checks if the change will slow down the system or break scaling. Each agent brings its specialized perspective. They do not coordinate. They work independently. Then they converge on the decision. The supervisor synthesizes their outputs and decides whether to approve, reject, or request changes. The research on this is striking. Multi agent committees outperform single agents. We see a 34.3% success rate for committees versus 27.3% for single agents on complex decisions. That is not a marginal improvement. That is a meaningful difference in decision quality. Because each agent catches things the others miss. The code agent might approve the implementation, but the security agent catches a new data exposure. The performance agent flags a complexity issue that would have crashed the system later. By itself, each agent would miss something. Together, they see the whole picture. The committee pattern works best when different expertise genuinely matters. Security, performance, compliance, business logic. These are not areas where a single perspective is sufficient. You need specialists. And you need them reasoning independently. This is how organizations handle the autonomy ceiling from a different angle. Instead of saying an agent can only handle low-risk decisions, you say an agent can handle complex decisions if we distribute the reasoning. You do not lower the threshold by restricting what agents can do. You raise it by improving the quality of the reasoning. The committee can achieve higher autonomy because the decision quality is higher. If a single agent has a high correction rate, but a committee of three hits 85% confidence, that decision no longer needs a human. The collective judgment is good enough. And here is the shift. A committee can escalate gracefully when there is disagreement. If the security agent flags a vulnerability, but the code agent says the implementation is clean, the supervisor does not have to guess. It escalates to a human and explains that there are conflicting expert opinions. This is different from a single agent hitting a confidence ceiling. A single agent says, "I am not sure." A committee says, "We have conflicting advice." And here is what each perspective is telling us. The overhead of coordinating multiple agents seems like it should slow things down. But in reality, it does the opposite, the agents work in parallel, the synthesis is fast, and the improvement in decision quality makes it worth the effort. This is becoming the standard for production critical decisions, not because it is the fastest approach. But because it is the safest, when you need high confidence and the cost of a bad decision is high, having multiple expert perspectives is invaluable. The committee patent teaches us that scaling autonomy is not about giving one agent more authority. It is about distributing authority across specialists and letting their collective reasoning determine the outcome. Real-world impact, MTTR and Toil reduction. All of this sounds good in theory. Agents, Fabrics, Committees, Governance. But the real question is what it does to your actual operational metrics. What changes when you move from a pipeline to an agentex system? The financial case for agentex DevOps is built on two pillars. The first is MTTR, mean time to resolution. The second is Toil reduction. Let's start with MTTR because the numbers are the most striking. When agentex troubleshooting systems take responsibility for incident response, the results are dramatic. Some networks have reported up to a 95% MTTR reduction, an incident that used to take four hours to resolve now takes four minutes. That is not optimization. That is a fundamental restructuring of how fast you can recover. More conservatively, organizations see between 25 and 70% improvements. The range depends on your complexity and how much remediation you are willing to hand to an agent. Here is why that matters. For a high revenue service, every minute of downtime costs tens of thousands of dollars. If you run an e-commerce platform every minute of outage means transactions are not happening. Customers get frustrated, they switch to competitors, every minute of downtime compounds. You are not just losing revenue. You are losing trust. A 25% improvement saves 40,000 dollars per incident. If your average downtime costs 80,000 per hour. If you have 10 major incidents per month, that is 4.8 million dollars in annual cost avoidance. And that is just the direct cost. There is also the labor cost. Your senior engineers are not sitting around waiting for incidents to happen. When something breaks, they drop everything. They are in war rooms. They are being paged at 3am. A 25% MTTR reduction means 25% less on-call load. But MTR is only part of the equation. The other pillar is toil reduction. Toil is the operational work that does not create lasting value. It is the alerts that fire repeatedly because nobody fix the root cause. It is the log analysis that is done the same way every single time. Toil is what burns people out. Senior engineers did not join your team to run the same playbook a thousand times. They want to build, they want to solve hard problems. But instead they spend nearly 40% of their time on Toil. Agenetic systems handle that work. They run the playbooks. They analyze the logs. They execute the remedialations. Organizations report up to a 60% reduction in manual work when agents take over these tasks. But here is the thing. When that labor gets freed up, it does not disappear. It gets redeployed. A senior engineer who was triaging alerts now spends that time on higher value work. They are not idling. They are designing better systems. They are thinking about reliability at a deeper level. That is the real ROI. It is not just that agents do the work faster. It is that freeing up expensive human expertise and pointing it at harder problems generates disproportionate value. You get the same engineering staff, but you get higher output. Because they are working on things that matter instead of things that repeat. This is labor reallocation, not labor elimination. The team did not shrink. The value per person increased. The skills gap. What architects need to know. There is a constraint nobody talks about. It will shape your timeline more than any technical limit. The demand for people who can govern agentex systems is growing at 81% every year. But the supply isn't moving. Right now there is a 70% skills gap in AI governance roles. Organizations are trying to hire for positions that barely exist. They are looking for skills that don't have a degree or a pipeline. They are competing for talent that every other company is also trying to recruit. This creates a bottleneck. It isn't a technical one. It's a human one. You can build the infrastructure. You can deploy the agents. You can even set up the supervisor worker pattern. But you cannot govern them safely without people who understand the model and those people are rare. The skills you need are hybrid. Nobody is graduating with a degree in AI governance. You need someone who understands software engineering well enough to design architectures and write governance controls into the code. You need someone who understands risk and policy well enough to turn business rules into technical boundaries. You need security expertise to build zero trust models for agents. You need someone who sees the whole picture. That isn't a specialist. It's a specific kind of generalist. Most organizations don't have this person. You have engineers who build but don't think about policy. You have risk people who know policy but can't code. You have security architects who know constraints but haven't touched autonomous systems. Nobody has all four skills in one head. So you have a choice. You hire externally. You go into the market and fight every other company for the same person. You offer a massive salary for a role that just appeared. You hope you can find someone with experience but almost nobody has it because these roles are brand new. Or you upskill your own staff. You take a platform engineer and send them to training. You pair a security architect with an AI engineer and hope they figure it out together. You are betting on your team's ability to learn a domain that moves faster than the training can keep up with. Either way, your governance maturity will lag behind your technical capability. Except that now. Plan for it. The moment you deploy agents, you need people to oversee them and you probably won't have them yet. Your roadmap for agents is actually a roadmap for building human capability. The technical part is the easy part. The hard part is having people who know how to constrain the system, measure it and adjust it as the risk changes. Organizations that invest in internal training right now will have a massive advantage. They will have the infrastructure and the people who can actually run it. Instead of being stuck by hiring, they will be limited only by how fast they can architect new workflows. We are seeing a new role emerge. The AI orchestration engineer. This person sits between platform engineering and risk management. They design the workflows. They define the policies. They implement the controls. They watch how the agents behave and adjust the boundaries based on performance. It isn't a specialist in agents. It isn't a specialist in governance. It's someone who can translate between the two. They bridge what the business needs and what the agents can do. They bridge policy and code. They bridge risk and autonomy. This role didn't exist three years ago. Today it is critical. In five years it will be the standard. But right now it is in short supply. Talent is your constraint, not technology. Start developing that expertise today. Don't wait until the infrastructure is finished to realize you have nobody to operate it safely. Because that is where most organizations will stumble. The cost structure. Why agentic systems are more expensive? Now we need to talk about money. Everything we've discussed, the speed, the quality, the reduction in toil, comes with a price tag. And it is a bigger price tag than traditional automation. You have to understand this upfront. Going agentic isn't just a technical choice. It's a financial commitment. If you aren't ready for the economics, you'll build something halfway. And then quit when the ROI doesn't show up immediately. Building these systems costs more at the start. That isn't negotiable. You aren't just buying a tool. You are building a foundation. You need orchestration frameworks to coordinate agents and handle failures. You need policy engines to enforce rules at runtime. You need observability built for agents. You have to see how they are deciding. If they are respecting boundaries and if they are actually improving. You need governance infrastructure. This means identity management for agents and credential systems. You need audit logs that show not just what happened, but why the agent did it and which policy allowed it. You need testing frameworks to validate behavior before it ever hits production. And the testing itself is more intense. A script either runs or it fails. But an agent can run and give you the wrong answer without ever crashing. You have to test the reasoning, not just the execution. You have to stress test the logic and simulate failures to make sure the escalation parts actually work. The numbers are real. A production-grade agentic system usually costs between $10,000 and $50,000 to start. Compare that to traditional automation, which usually costs between $2,000 and $8,000. You are looking at 5 to 10 times the initial investment. Most organizations see that upfront cost and stop. They decide it isn't worth it and stick with what they have. But they are comparing the wrong numbers. Upfront cost isn't the metric that matters. Total cost of ownership is because the long-term cost curve is different. With traditional automation, maintenance costs grow. You write a script and it works. Then the infrastructure changes and the script breaks. You fix it. It breaks again. You are constantly chasing failures and patching things that used to work fine. The cost compounds, the older the automation gets, the more expensive it is to keep alive. With agentic systems that flips. And agent adapts. When you change the infrastructure, the agent learns the new pattern and keeps going. You don't rewrite the agent every time a small thing changes. The system evolves with the environment. Over three years these systems typically deliver 300 to 500% ROI. Traditional automation usually lands between 150 and 250%. The agentic system starts expensive but it ends up costing less over time. The payoff usually happens between month 4 and month 8. By then the system is mature. It's handling routine decisions. The team knows how to run it. The governance is working. That's when the investment starts paying you back. But there is a catch. You have to pick the right use case. High volume high variance workflows justify the cost. If you have 100 incidents a month and everyone is different, an agentic system pays for itself. It handles complexity that a static script cannot touch. If you are doing thousands of deployments across different services, the ROI is massive. Stable low variance workflows do not justify it. If you have a simple process, that is the same every single time. Traditional automation is better. It's cheaper. It's easier to maintain. Using an agent there is overkill. If you use agents for the wrong problems, you will waste money. You will pay the premium and never see the payoff because the work wasn't complex enough to need it. But if you get the use case right, the returns are huge. This financial model requires a three year horizon. Do not expect the payoff in the first 90 days. Do not judge the ROI based on the first year. Give the system time to mature and give your team time to learn. Pick the right problem, commit to the timeline and the math works. Pick the wrong problem. And you've just built a very expensive solution to something that wasn't a priority. Incident response. Where agents deliver immediately. If you want to see where agentex systems deliver value fastest, stop looking at deployments, stop looking at infrastructure provisioning, look at incident response. This is where the impact is immediate and measurable. Because in reality, incident response is just a problem of incomplete information combined with extreme time pressure. A service degrades, alerts fire, a human on-call engineer gets paged. It's 2am, they have no context. They know something is broken, but they don't know what or why. So they start gathering context. They log into the dashboard. They look at error rates. They pull up logs. They check recent deployments. They're trying to build a mental model of the failure. This takes time. If they're experienced and the problem is simple, it takes 15 minutes. If it's complex, it takes 30 minutes or longer. While they're digging, the customer impact is growing. Services stay down. Users experience slowdowns. The window for a quick recovery is closing. An agent system works differently. The moment the alert fires, the agent starts working. It pulls logs immediately. It analyzes them. It correlates the timing of recent changes with the start of the degradation. It looks at CPU, memory and database connections to flag anomalies. It checks if there's a pattern match to known failure modes in its memory. The agent does all of this in 30 seconds, not 15 minutes, 30 seconds. By the time the engineer's phone actually rings, the agent has finished the manual work that usually takes 15 minutes. The agent presents a diagnosis. It might say the payment service shows, High Latency that correlates with a user service deployment from 30 minutes ago. It notes that database connections are at capacity because the user service isn't releasing them. Then it recommends a rollback. Is the diagnosis definitely correct? No. Maybe there's a factor the agent missed, but the agent has moved the conversation forward. The engineer doesn't spend 15 minutes gathering context anymore. Now, the engineer spends that time evaluating the evidence and deciding whether to act. This is what agent's augmentation looks like. The engineer doesn't disappear. But the job changes. Instead of being a detective gathering clues, the engineer becomes a decision maker evaluating evidence. For straight forward incidents, the agent has seen before. It can often handle the fix without a human. It knows that cash invalidation resolves this specific issue. It clears the cash and monitors the result. Error rates drop. The issue resolves. The human gets a notification after the fact that an issue was handled autonomously. No emergency. No page. No wallroom. For novel incidents, the agent escalates to the human with everything they need to make a choice. The human isn't starting from zero. They're starting with a full diagnosis. And the set of options the agent already checked. Real organizations using these systems see a 45 to 60% improvement in MTTR within a year or 18 months. That's not because agents are faster at clicking buttons. It's because agents compress the diagnosis phase. The time from something broke to we know what to fix shrinks dramatically. This pattern spreads faster in incident response because the value is visible. Every engineer understands the on-call burden. Every team feels the pain of alert fatigue. When agents start handling that toil, adoption accelerates. Governance is also simpler here. You have clear runbooks to turn into policy. You have well-defined escalation parts. If the agent is confident, it acts. If not, it asks the human. The outcomes are measurable. Did the issue resolve? This is where organizations see their fastest wins. It's not about theoretical efficiency. It's about the very real experience of not being woken up at 2am for an incident the agent already fixed. Code review and quality gates. Code review is one of the most expensive gates in a traditional pipeline. But most organizations don't realize just how expensive it is. A senior engineer reviewing a pull request doesn't spend five minutes. They spend 30 minutes. They read the code. They think through the logic. They consider edge cases in architecture. They check for security issues and performance. That's a half hour of senior engineering time per review. If that engineer does 20 reviews a week, that's 10 hours gone. 10 hours that aren't spent building things or solving complex problems. When you multiply that across a team of 100 engineers, you're dedicating hundreds of hours every week just to the review gate. And that review is only good for the moment it happens. Issues can still slip past a tired reviewer. An agentic review system changes the model. It doesn't skip the review. It does the parts that don't require judgment in parallel with the developer's work. The agent runs style checks. It analyzes security vulnerabilities. It validates architecture patterns and identifies dead code. It flags concurrency issues and suggests refactorings to improve maintainability. All of this happens while the code is being submitted. In seconds, not one after another, but all at once. By the time a human looks at the code, the mechanical analysis is done. The reviewer doesn't have to waste energy on style issues or obvious bugs. The agent already caught those. The reviewer can focus on what actually requires human judgment. Does this solve the problem correctly? Is the design sound? Does this approach align with where the system is heading? Organizations using agentic code review report a 25% to 50% reduction in review time. And they do it while keeping or improving quality. That's not a compromise. It's an improvement. The human effort is directed at the decisions that matter. Instead of being scattered across tactical issues, the agent already found. The agent also generates recommendations. It suggests tests. It points out edge cases the author missed. It explains the why behind its suggestions. This turns the agent into a teaching tool. And this is where it gets interesting for career paths. If an agent can do code review, what happens to junior developers? This is the anxiety that surfaces in most teams. If agents can flag issues, why do we need juniors learning by doing reviews? The answer is that the junior developer's role shifts. They stop learning by fixing mistakes during a slow review process. They start learning by writing better code in the first place. Because now the agent is telling them why their approach is problematic immediately. The agent flags the issue and explains the principle behind it. The junior developer gets specific feedback right then. They don't have to wait for a senior engineer to send a Slack message two days later. The agent shows exactly what the concern is and why it matters. Juniors are freed from the expectation that they'll be perfect on day one. They can focus on understanding the problem and learning to design solutions. Instead of just trying to write code that works. Organizations that frame this as an augmentation tool see higher adoption. Teams that fear it as a replacement fight it. And they see lower value because they're restricting how the system helps. The real shift is structural. You aren't removing the review gate. You're restructuring it so the expensive part, senior engineer time, is spent on high value judgment. That's how you make code review scale without burning out your staff. Test generation and maintenance. Test maintenance is eating your QAT in alive. And most organizations don't realize how much of this is actually fixable. The issue is fundamental. You write tests to validate that your code works. But the code changes. And the tests have to change with it. If they don't, they become a liability. A test that doesn't reflect how the code actually behaves is worse than having no test at all. Because it gives you false confidence. It blocks your releases when it shouldn't. So someone has to keep those tests in sync with the code. That someone is usually your QAT team and they're drowning. In an active team, maintenance isn't just a background task. It's the core of the job. When a feature changes, the test has to change. When you re-factor, you have to rewrite tests. To focus on behavior instead of implementation details. Even a simple library upgrade can break every test that touched the old API. This is repetitive work. It follows a predictable pattern. A test breaks. You analyze why. You find the change that caused it. You rewrite the test and verify it passes. Then you do it again. Thousands of times across the entire suite. An agentic system handles this naturally. When the code changes, the agent sees it. It analyzes what the test was originally checking for and evaluates if that logic still holds up under the new code. If the test needs an update, the agent handles the edit. If the test is dead weight, the agent removes it. The result is a test suite that stays in sync with your code automatically. It isn't perfect because agents don't always understand human intent. But it works well enough that your developers aren't spending hours on manual updates every single sprint. The data backstarts up. A multi-agent testing framework recently showed a 60% reduction in invalid tests and a 30% jump in coverage coverage coverage. And a 30% jump in coverage compared to basic AI tools. That's a massive shift. You aren't just automating the boring stuff. You're actually making the suite better while you do it. And because code changes every day, the agent keeps everything aligned in real time. The friction that usually turns into technical debt gets deleted before it even starts. Organizations are seeing a 30 to 40% drop in maintenance time once they deploy these systems. That isn't a marginal game. It's a structural change. But here's what actually happens to the people. Their focus shifts. Instead of maintaining tests, they design them. They think about strategies. They figure out which scenarios actually matter. They spend their time making tests more meaningful instead of just making them green. This is the pattern we see with all these tools. Agents don't eliminate the work. They eliminate the maintenance of the work. The human still owns the suite. But now you're designing it instead of debugging it. For QA teams, this is a massive pivot. Your job isn't "keep the tests passing anymore." Your job is designed the strategy. That's harder work. But it's also more interesting. It's the kind of work that doesn't lead to burn out. The math is simple. A QA engineer making $150,000 a year often spends 40% of their time on maintenance. That's $60,000 in labor just to tread water. Agents can cut that down to 10%. You're freeing up $45,000 in capacity per person. When you multiply that across a team of five, you've recovered over $200,000 in value. More importantly, you've given your best people the cognitive space to solve much harder problems. Deployment strategy and canary rollouts. Deployment decisions are high stakes. A bad push can take down a service and cost millions in downtime. The stakes are real, and everyone in the room feels it. This is where traditional pipelines hit a wall. They use fixed strategies. Blue green for the service canary for that one. Rolling updates for the infrastructure. The strategy is locked in from the start. The pipeline just executes the same script every single time. That works when things are predictable. It works when the system is in a known state. But modern infrastructure doesn't stay in a known state. Loads bikes. Recent incidents leave the system fragile. A previous push might have left behind subtle bugs. The health of your service right now is not the same as it was yesterday. Yet, your deployment strategy doesn't care. The pipeline runs the same plan regardless of the context. An agentic deployment system flips that model. Instead of picking a strategy before you start, the agent looks at the current state and chooses the safest path for right now. The agent asks the hard questions, how healthy is the system? What are the error rates doing? Is the infrastructure under heavy load? Are there recent incidents that made things fragile? Based on that data, the agent picks the move. If the system is stressed, it recommends a slow canary rollout. It might start with 5% of traffic and watch. If things look good, it moves to 10%. Then 20%. Every step is monitored. Every step can be paused. But if the system is healthy and the load is low, the agent might approve a fast track. It might push to 50% immediately because the infrastructure can handle it. This is contextual reasoning. It's fundamentally different from a static pipeline. The agent isn't just following a plan. It's thinking about the situation. It realizes that in this specific moment, one strategy is safer than the other. And it doesn't stop once the deployment starts. It monitors everything in real time. If error rates spike, the agent sees it instantly. Not because a human is staring at a dashboard, but because the agent is built into the loop. The moment a threshold is hit, the agent can pause the rollout or trigger an immediate rollback. This is autonomous remediation. The system finds the problem and fixes it before a human even gets the alert. The impact on your customers is minimized because the response time is measured in seconds, not minutes. Teams using agentic strategies report a 29% improvement in their time to recover when things go wrong. That might sound small, but it means your back online nearly a third faster. Your customers feel less pain. Your incident response team spends less time in the wall room. The financial impact adds up fast. Every deployment is a risk. Most succeed. But the ones that fail are incredibly expensive. Faster recovery on those failures directly cuts your incident costs. Fewer outages mean less churn and less damage to your reputation. In a large organization, you're deploying hundreds of times a week. Even a tiny improvement in safety per push becomes massive when you scale it across the year. The real insight here is that deployment should be dynamic. It should adapt to what's happening right now. An agentic system makes that possible because it has the context. It can evaluate the options and it can course correct in real time. That isn't just a faster way to deploy. It's a smarter way. The governance fabric, zero trust for agents. Building a governance fabric is where your theory finally hits the infrastructure. You can talk about zero trust principles all day. But eventually you have to build a system that actually makes it work. And that's where things change. Because this is more complex than most organizations realize. The governance fabric isn't just a single tool you buy. It's a coordinated system of identity, credentials, policy and logs. All working together to make sure every single action an agent takes is validated. It starts with identity. Every agent needs a cryptographic identity. Not a username, not a password. You need an identity derived from a certificate or a token that proves the agent is exactly who it claims to be. Because that identity is cryptographically signed, the system can verify it hasn't been tampered with. The agent has one specific identity. It can't impersonate another agent. It can't borrow someone else's credentials. But here's the problem. Static credentials are a massive risk. So in this model, credentials are short-lived. They don't last forever. They expire in minutes or hours. When an agent needs to act, it requests a new credential, scoped only to that one specific task. It says, "I need to deploy service X to staging for the next 60 minutes." The system grants a credential for that window and nothing else. If that key is stolen, the exposure lasts for minutes. Not forever. The policy engine sits right at the intersection of the request and the resource. The agent makes its move. And the engine checks everything. Does it have the right credential? Is that credential still valid? What rules apply here? These policies are hard-coded as rules. Staging deployments needs security checks. Production deployments need a human to say yes. Every single environment needs an audit trail. The engine evaluates those rules against the live state of your system. It checks if the security scans passed or if the approval is on file. Then it either allows the action or it blocks it. It doesn't ask the agent to be responsible for following the rules. It enforces them technically. The agent either can act or it can't. There is no in-between. And this is the shift. Enforcement happens at execution time, not decision time, because circumstances change. The state of your system, when the agent decides to act, might be different from when it actually tries to run the command. The policy engine validates the conditions at the exact moment of the action, if something shifted and the conditions are no longer met. The action is blocked in real time. Then audit logging captures the entire story. Every credential requested, every policy decision made, every success and every failure, you aren't just looking at summary logs. You're looking at detailed decision traces that show exactly what the agent tried to do and why the system allowed it. This is the evidence you need for compliance. If you're in a regulated industry, auditors don't want to hear about your intentions. They want to see the proof. The governance fabric creates that proof automatically. You're documenting what actually happened with cryptographic certainty. The overhead here is real. You need the identity infrastructure. You need the policy engines and the credential managers. You need the monitoring to see when agents are hitting the edges of their permissions. This costs time and it costs money. But it's non-negotiable for critical systems. The moment an agent has the authority to break something. You need to know it didn't. Or if it did, you need to know exactly how. The governance fabric isn't a feature you add later. It's the prerequisite you build first. Get this right and you can scale with confidence, skip it. And you're running an unsupervised system that could do massive damage without leaving a single clue behind. That's the difference between governance that works and governance that fails. Between autonomy you trust and autonomy that terrifies you. Observability and monitoring agents. You can't manage what you can't measure. That's a cliche for infrastructure. But for agents, it's the only way to survive. Traditional monitoring tells you what the system is doing. CPU, memory, latency. You're watching the mechanics of the machine. If a metric goes red, you respond. But agents require a different kind of visibility. You aren't just watching what happened. You're watching what the agent decided to do. And whether that decision was actually smart. Imagine an agent recommends rolling back a deployment. You need to know why it thought that was necessary. What data did it see? What patterns did it pick up? If that rollback was a mistake and it broke something else. You have to understand where the reasoning failed. Not to blame the agent. But to fix the logic, that's decision level observability. You're tracking the thought process, not just the output. This takes specialized tools that most teams just don't have yet. You need metrics for decision quality. How often is the agent right? How often does a human have to step in? How often does its action cause the exact opposite of what you wanted? You need decision traces. Every time an agent acts, you want the full record of its inputs. The data it consulted, the policies it checked. The alternatives it looked at, and then rejected. A decision trace is the agent's explanation of its own work. You can read it after the fact and understand exactly what it was thinking. You also need policy dashboards. Is the agent staying inside the lines? Is it respecting its credentials? If an agent keeps hitting the same policy wall, that's a signal. Maybe the policy is too tight. Maybe the agent needs better training on when to escalate. Or maybe there's a gap between your rules and the agent's understanding. When you have this level of visibility, you can catch agent drift before it turns into a disaster. Drift isn't a sudden crash. It's a slow shift in how decisions are made. Maybe the agent gets too conservative and starts escalating everything. Or maybe it gets too aggressive and touches things it shouldn't. Without seeing the reasoning, drift is invisible until something breaks. With observability, you see the pattern early. This layer also creates a feedback loop for improvement. If an agent fails in a specific scenario, you don't just log it. You use that data to redesign the logic. If it escalates too much for one type of problem, you give it more context so it can handle it next time. This is continuous improvement built into the core of the system. Agents don't have to plateau. They get better because their behavior is monitored and refined. Every decision creates data. And that data becomes the input for the next version of the agent. Without this, you're operating in the dark. You deploy the agent. It makes a choice. Things happen. But you don't see the process. You don't understand the why. You don't know if it's learning or just repeating the same mistakes over and over. You're just hoping the system works without any way to verify it. And that's not governance. That's hope. Good observability turns that around. You see what they're doing. You understand why you measure the quality. That visibility is the only thing that makes autonomous systems actually work. The organizational shift from gatekeepers to orchestrators. The biggest change isn't technological. It's organizational. And it's the reason most agentec deployments fail. Not because of technical problems, but because people didn't expect how much their jobs would transform. In a traditional pipeline, DevOps and SRE engineers own critical decision points. A change comes in. They review it. A deployment is scheduled. They execute it and incident occurs. They respond to it. Their role is the gatekeeper. They stand at the thresholds and decide what passes and what doesn't. This role has status. It has clarity. People know what you do. You know what you do. You're the person who understands the system deeply enough to say yes or no to changes. The person who responds when things break. The expert. You are essential. In an agentec system, that role evaporates. Or rather, it transforms completely. You're no longer the gatekeeper. You become the orchestrator. Instead of reviewing individual changes, you design the policies that agents will follow when they evaluate those changes. Instead of approving deployments, you define the decision logic that agents use to choose a strategy. Instead of responding to incidents, you design the workflows and escalation paths. That agents execute when things go wrong. This is harder work in many ways. It requires deeper systems thinking. You're not making individual decisions anymore. You're designing the decision-making system itself. But here's where the resistance emerges. It also feels like less work. You're no longer the critical path. You're not the bottleneck. Decisions happen without you. And for people whose identity is built on being indispensable, that's threatening. Some engineers see this clearly and embrace it. They understand that designing systems is more interesting than executing decisions. And they see the opportunity to work on harder problems. These people transition smoothly. They move from being incident responders to being reliability architects, from being approval nodes to being policy designers. It's the same domain expertise applied at a different level. It's actually more satisfying. Others resist. And their resistance is real and rational. They've spent a decade becoming the person who knows how to handle production incidents. They've built expertise through experience. They've built identity around that expertise. Now the system doesn't need them for that anymore. Even if they understand why that's good intellectually. Emotionally, it feels like their skills are being devalued. And that's hard to process. Organizations that manage this transition well do three specific things. First, they invest in training. Not just training on how to use the tools. But training on how to think about agentex systems. Training on policy design, system architecture, and observability for agents. They build the capability that people need to be effective in the new role. People who feel equipped to do the new job feel less threatened by it. Second, they reframe the narrative explicitly, repeatedly. Not we're replacing your job with automation. But you're being elevated from doing reactive work to doing strategic work. This isn't a promotional slogan. It's true. But saying it matters. People need to hear it from leadership. They need to see it reflected in how they are compensated, how they're evaluated, and what projects they're assigned. Third, they build change management into the deployment itself. You don't just turn on agentex systems and hope people adapt. You plan for the transition. You identify champions who embrace the new model early and can help others understand it. You create opportunities for people to practice the new role in low-stakes settings before going live. You measure adoption and resistance and address both explicitly. The practical implication is simple. Your technical deployment schedule and your change management schedule need to be coordinated. If you're deploying agentex systems but haven't done the organizational work to help people transition, you'll have technical capability that your team doesn't trust and won't actually use. Teams that skip this step see lower adoption. People circumvent the agents. People push back on decisions the agents make. People ask for exceptions and manual overrides. The system becomes half automated because people don't trust it. And half autonomous systems deliver a fraction of the value of fully trusted autonomous systems. The organizations that succeeded this transition understand something fundamental. Technical capability isn't enough. Your team has to believe in the system. And belief comes from understanding the change, feeling equipped to operate in the new model. And experiencing early wins that prove the system works. That's where leadership and change management become as critical as architecture and tooling. Get the technical part right without the human part and you have a system that works but doesn't scale. Get both right and you have something that actually transforms how work happens. The three-year roadmap, building agente capability. Now theory becomes execution. You understand why traditional pipelines are broken. You understand how agente systems actually work. You understand the governance architecture and the organizational shifts required. But what does implementation actually look like? What's the sequence of moves that takes you from where you are to where you need to be? The most dangerous approach is to go all in. Pick the most critical path in your delivery system and hand it entirely to agents because theoretically they can handle it. Organizations that do this usually fail spectacularly. The agents aren't ready. Your team isn't ready. Your governance isn't mature enough. You learn these lessons by breaking something important. The right approach is staged. Year one is about building foundation and running pilots. You're not trying to solve your entire delivery problem yet. You're proving that agente systems work in your specific environment and building internal capability to operate them safely. Start with the lowest risk domains where agents can deliver immediate value. Log analysis and alert triage. These are red-only operations. An agent analyzing logs isn't changing anything. It's just making sense of data. Test generation. An agent writing tests isn't deploying anything. It's just creating test code that humans review before it ships. These are safe learning grounds. The agent can fail and the worst outcome is that you ignore its output. Simultaneously, you're building a governance framework, not as a document, but as infrastructure. You're implementing identity systems for agents. You're designing policy engines. You're setting up audit logging. You're creating the operational foundation that everything else will depend on. This takes time, three to six months to get it right. But rushing this is how you end up with systems that are powerful but ungovernable. And you're measuring baseline metrics. What's your actual MTTR right now? What percentage of your team's time goes to operational toil? How long does code review actually take? What's your current test maintenance burden? You need these numbers to measure improvement later. You need them to validate your financial models. You can't claim an agent improved MTTR by 30% if you don't know what MTTR actually was when you started. Year one concludes with a working pilot. Agents are analyzing logs. They're suggesting improvements to tests. You've built foundational governance. You've trained your team on how the system works. You've measured baseline metrics. You know where you stand. Year two is expansion and learning. You take what worked in year one and expanded to higher stakes domains. Incident response, deployment strategy, multi agent committees for complex decisions. You're not just running more agents. You're building the coordination layer. You're implementing the supervisor worker pattern at scale. You're setting up feedback loops. So agents learn from their decisions over time. This is where your observability infrastructure becomes critical. You're monitoring not just the infrastructure. You're monitoring the agents themselves. Are they making good decisions? Are they learning? Are they drifting? Your observability tells you what's working and what needs adjustment. You iterate based on that feedback. Year two also brings organizational shifts. You're promoting people into orchestrator roles. You're reframing how teams think about their work. You're seeing the early returns on your investment. MTTR is improving. Toil is dropping. People are starting to trust the system. This is the period where momentum builds. You can feel the difference. The wins are visible. Year three is maturity and scale. Agents handle the majority of routine decisions. Your team has shifted from execution to design. Your organizational structure reflects the new operating model. Senior engineers are designing policy frameworks instead of approving individual changes. The financial return on your investment is now clear. ROI is achieved and then some. But here's the critical thing. This roadmap isn't linear. You won't execute perfectly. You'll discover that something you plan for year two doesn't work until year three. You'll find unexpected opportunities to accelerate progress. You'll hit unexpected barriers that force you to pause and recalibrate. That's normal. That's expected. The roadmap is a direction. Not a GPS coordinate. The key principle is start with low risk pilots. Build confidence through measurable results. An expand authority gradually based on demonstrated performance. Organizations that follow that principle even if their specific timeline differs. Suicide. Those that skip the foundational work or try to expand faster than they've actually validated. Suicide file is often. The financial case building your business case. Building a business case for agentex systems isn't straightforward. There is no template that works everywhere. But there is a framework and the difference between organizations that see a massive ROI and those that just waste money is that framework. The financial case depends on three factors. If you get all three right your projections will be accurate if you miss even one. The whole thing collapses. The first factor is use case selection. Not every workflow justifies the investment. You need to find the parts of your delivery system that are high volume and high variance. High volume means the work happens so often that small improvements turn into massive time savings. High variance means the work is complex enough that standard automation constantly breaks. When you combine those two you found where agents actually deliver value. If you don't have both save your money. Incident response is a perfect example because it happens constantly yet every single incident is slightly different. An agent makes sense there. But a monthly deployment that follows the exact same steps every single time is low volume and low variance. In that scenario an agent is just overkill. Most organizations that struggle with ROI simply picked the wrong use case to start with. They deployed agents where simple automation would have worked or they expected a huge win in an area where the gains were always going to be tiny. You have to start where the impact is obvious. The second factor is baseline measurement. You can't claim you improved anything if you don't know where you started. This takes discipline. Baselines require waiting. You need three to six months of historical data to establish a clean starting point. You need to track MTTR for every incident class. The toil hours your team is logging and your deployment success rates. You need to know your test maintenance time, your code review cycles and exactly what your incidents are costing you. This is where most people skip ahead. They want to deploy the agents right now, measuring feels like a delay. But without knowing your starting point your ROI claims are just guesses. And if you're asking leadership for millions of dollars, your claims need to be grounded in data, not guesses. The third factor is realistic assumptions. Vendors will promise you a 90% reduction in MTTR and 80% less toil. Those numbers exist in labs under perfect conditions. In a real organization with real complexity you need to be more conservative. Plan for 25 to 40% improvement in MTTR, plan for 20 to 40% less toil. These are still massive gains. They are real. But they aren't magic. Once you have the right use case, the baseline and the realistic numbers. Then you build the model. Include everything. The upfront cost for orchestration, the policy engines and the observability tools. The ongoing costs for licensing and hosting. The labor costs for building expertise don't hide these numbers. Make them visible. Then you quantify the benefits. Take the time saved and multiply it by the hourly rate of the people doing the work. Calculate the downtime, avoid it and the revenue impact that comes with it. Factor in the hiring you don't have to do because agents are handling the load. Faster deployment means features get to customers sooner. And that leads to earlier revenue. The honest math shows a payback period of 4 to 8 months for a well-scoped project. That's a compelling story. But it only works if you select the right use case and build the model correctly. The discipline that separates a credible case from an optimistic guess is measuring the actual results against your projections. Track the real MTTR improvement every month. Compare it to your forecast. Track the actual labor hours you freed up. When reality looks different than your projection, you need to understand why. Adjust the model. Use that lesson for the next deployment. Organizations that follow this path see ROI that actually matches their projections. The ones that skip the discipline see projects that never materialize. They see investments that look like waste. And eventually the agents don't scale because leadership no longer trusts the math. The opportunity is real. The ROI is real. But you have to do the work upfront to prove it. The risks. What can go wrong? Agentex systems introduce new failure modes. That's the thing nobody wants to talk about. We talk about the value, the speed and the toil reduction. We don't talk about what happens when things break. An agent can make a decision that seems perfectly sound in the moment. But turns out to be exactly wrong. Imagine an agent sees a deployment causing high latency. It decides to roll back that deployment on the surface. That's a reasonable choice. Except the deployment wasn't actually the problem. The latency was caused by a slow database query triggered by a cache configuration that had nothing to do with the new code. The agent rolls back, removing the feature you just shipped. The latency stays. Now you've solved the wrong problem and broken the right solution. This isn't a theory. The correction rate for Agentex systems is between 40 and 73%. That means nearly half of agent decisions require a human to review or fix them. Let that sink in nearly half. That isn't a rounding error. It's a structural reality of how these systems work today. Most people see this as a failure. They ask why we would ever trust a system where half the decisions are wrong. But that's the wrong way to look at it. That correction rate exists because these systems are operating at the very edge of their capability. They are making decisions sophisticated enough that they occasionally need a human to refine them. They are built with escalation parts for a reason. That isn't a design flaw. That is exactly how the design is supposed to work. The real failure happens when you deploy agents without those escalation parts. When you give them the authority to act without any oversight. When you don't have human eyes available to catch a mistake before it becomes a disaster. That's when a 40% correction rate becomes a crisis instead of a feature. The other major risk is over autonomy. This is the temptation that kills most deployments. You get your first agent working well and it handles low risk decisions with great accuracy. So you expand its authority. You give it higher stakes. You remove the requirement for human check-ins. You try to maximize the autonomy because you think that's where the value is. Then something goes wrong. The agent hits a scenario it hasn't seen before. There is no human there to catch it. The impact is severe. And suddenly your entire program is under review because someone trusted the system too much too soon. The solution isn't to stop expanding authority. It's to expand it deliberately. Start with decisions where the agent has proven 90% accuracy over several months. Then move to slightly higher risk tasks. Measure again. Expand again. This is tiered. Autonomy. Different decisions get different levels of oversight based on proven performance. There is also an organizational risk that people underestimate. People feel threatened by agents. They feel like their expertise is being devalued. If your team doesn't buy in, they will find ways to sabotage the system. They'll ask for exceptions. They'll keep using manual workarounds. They'll push back on every decision the agent makes. The system becomes half trusted because the people running it don't actually believe in it. You can't solve this with technology. You solve it with change management. You need clear communication about what is actually happening. You need to involve the people affected in the design process. Frame the agents as augmentation, not a replacement. Make sure everyone understands how their role is changing and what their new responsibilities look like. If you skip this, you'll have a technical capability that nobody actually uses. Finally, there is the risk of governance. If you don't have clear policies, agents will eventually find a way to violate compliance. They'll access data they shouldn't. They'll make decisions that contradict your regulatory rules. They will create liability. The solution is building governance into the architecture from day one. Don't add it later. Don't write the policies after you've already deployed. Encode the constraints into the infrastructure itself. Make it impossible for an agent to violate a policy because the system won't let it. If you get these risks, write "agentic systems work". If you missed them, you've built a tool that is either too limited to be useful or powerful enough to be dangerous. There is no middle ground either you designed for these risks or you didn't. The five-year vision beyond the pipeline. Look five years ahead. The company starting this transition now are operating differently, not just slightly faster, fundamentally different. The pipeline isn't just gone from their tools. It's gone from how they think that they've stopped thinking about gates. They've stopped thinking about handoffs. They're thinking in terms of continuous reasoning, a change of lands. Instead of waiting for a sequence, multiple agents evaluate it at the same time. A code agent checks the logic. A security agent looks for holes, a performance agent hunts for bottlenecks. A test agent builds the coverage, a deployment agent looks at the system state and picks the strategy. They work in parallel, decisions converge, the change ships, or it escalates. Hours become minutes. The friction is gone. But here's the problem. The organization still optimizing the pipeline, are playing a losing game. They're trying to make the gates faster. They're trying to reduce latency in a broken model. They're polishing a system that needs to be abandoned. By year five, they aren't even in the conversation. They can't compete on speed. They can't compete on reliability. They're just slower. And one level deeper. The talent has changed. DevOps isn't a job title anymore. It's a domain. Inside that domain, you have orchestration engineers. They design how autonomous systems reason about infrastructure. You have policy architects. They set the constraints that keep agents safe. You have reliability engineers focusing on the architecture. Instead of the incident, you don't have people reviewing pull requests. You don't have engineers triaging alerts at two in the morning. You have people designing the systems that make those tasks unnecessary. The best people aren't spending time on execution. They're spending it on design. The structure of the company reflects this shift. The DevOps team is smaller but has more power. Platform engineering is larger and more strategic. Risk and compliance are part of the build, not a gatekeeper at the end. The financial model changes too. Early adopters have lower costs. They deploy more often. They support more services with fewer people. They avoid incidents because they fix problems before they're even visible. Their advantage isn't just that they're faster. It's that they're cheaper while being faster. That's a combination you can't beat. The organization's stuck with traditional pipelines have a choice. They can try to catch up. But they're starting five years behind. The talent has moved on. The tools have evolved. The mental model of delivery has shifted. Catching up is possible. But it requires admitting the old model is broken. It requires a total transformation. By year five most realize they should have started sooner. Some never realize it until they're disrupted. This is what happens in five years. Not because the tech is better, but because the organizations that move early build an advantage they can't lose. The pipeline is dead, not tomorrow, but over the next three to five years. The way you deliver software is going to change structurally. The shift from human gates to agentic orchestration isn't a small step. It's not a faster version of what you do today. It's a different model entirely. The organizations that understand this will lead. The ones that wait will disappear. So start with an honest assessment. Where are you in this transition? Where are your biggest bottlenecks? Where would an agent provide the most value right now? Build a roadmap. Start with low risk pilots. Expand based on results. That's how you build the future.